# Overview

For every algorithm, it is important to understand the following:

1. What problem does this algorithm solve?
2. When can this algorithm be applied? (i.e., what are the preconditions? When does the algorithm fail?)
3. Why does the algorithm give the correct answer?
4. What is the key invariant behind this algorithm?
5. What is the running time of the algorithm? Are there any optimisations possible?


# Time Complexity

## Introduction

Time complexity of a program shows the order of growth of the running time as the input gets larger and larger.

It tells nothing about the absolute/actual running time of the algorithm. So, it is not always a good idea to compare two algorithms simply based on their time complexities. For example, `MergeSort` runs in $$O(n \log n)$$ whereas `InsertionSort` runs in $$O(n^2)$$. But in practice, for smaller size arrays, `InsertionSort` often runs faster than `MergeSort`!!

Since constants are omitted while dealing with time complexity of algorithms, two programs may have the same complexity but very different running times. For example, consider program A with $$T(n) = 10^8n = O(n)$$ and program B with $$T(n) = n = O(n)$$. Obviously program B will run faster than program A, but this is not evident if you only look at their orders of growth.

## Useful Mathematical Facts

It is useful to know the following properties of exponents and logarithms:

1. $$a^x = m \iff x = log\_a (m)$$ → definition of logarithm
2. $$log\_a (mn) = log\_a (m) + log\_a (n)$$ → product property
3. $$log\_a(m/n) = log\_a(m) - log\_a(n)$$ → quotient property
4. $$log(m^n) = nlog(m)$$ → power property
5. $$log\_a(b) = 1/log\_b(a)$$
6. $$log\_b a = log\_c(a) \times log\_b(c) = log\_c(a)/log\_c(b)$$ → change of base property
7. $$a^{log\_a(x)} = a$$ → number raised to log
8. $$log\_a(a) = 1$$
9. $$log\_a(1) = 0$$
10. $$log\_a(1/b) = -log\_a(b)$$
11. $$a^{log\_b(x)} =x^{log\_b(a)}$$ (when $$x, a > 0$$) → can take $$log$$ on both sides to verify its true
12. $$a^ma^n = a^{m + n}$$
13. $$a^m/a^n = a^{m -n}$$
14. $$1/a^m = a^{-m}$$
15. $$(a^m)^n = a^{mn}$$
16. $$(ab)^m = a^mb^m$$

$$
1 + 2 + 3  + ...  + n = \dfrac{n(n+1)}{2} = O(n^2)
$$

The above arithmetic progression can appear in various different forms. The more general form is:

Given an arithmetic series $$a + (a + d) + (a + 2d) + \dots + a + (n-1)d = \dfrac{n}{2}(2a + (n-1)\times d) = \dfrac{n}{2}(a + l)$$ where $$l$$ is the last term of the series and $$n$$ is the number of terms.

$$
1^2 + 2^2 + 3^2 + ...  + n^2 = \dfrac{n(n+1)(2n+1)}{6} = O(n^3)
$$

$$
1^3 + 2^3 + \dots + n^3 = \left(\dfrac{n(n+1)}{2} \right)^2 = O(n^4)
$$

$$
1 + r + r^2 + r^3 + .... = \dfrac{1}{1-r}, \quad \text{for}\  |r| < 1
$$

More generally, the solution to the geometric progression $$a + ar + ar^2 + \dots + ar^{n-1} = \dfrac{a(r^n - 1)}{r-1}$$

$$
\dfrac{1}{1} + \dfrac{1}{2} + \dfrac{1}{3} + \dots + \dfrac{1}{n} = O(\log n)
$$

The above series (called the harmonic series) is divergent but the sum of $$n$$ terms is upper bounded by $$O(\log n)$$. This is because:

$$
\sum\_{n = 1}^{k} \dfrac{1}{n} > \int\_1^{k+1} \dfrac{1}{x}dx = ln(k+1)
$$

It is easy to view the bound in terms of the graphs.

$$
1 + 2 + 4 + 8 + 16 + \dots + 2^m = 2^{m + 1} - 1 = O(2^m)
$$

$$
1 + 2 + 4 + 8 + 16 + \dots + m = 2m - 1 = O(m)
$$

The following result is also very useful (e.g. for deriving the time complexity of `heapify`)

$$
\sum\_{i = 1}^{\infty} \dfrac{i}{2^i} = \dfrac{1}{2} + \dfrac{2}{4} + \dfrac{3}{8} + \dots = 2
$$

## Common Recurrence Relations

$$T(n) = 2T(\dfrac{n}{2}) + O(1) = O(n)$$

In general, $$T(n) = cT(\dfrac{n}{c}) + O(1) = O(n)$$

***

$$T(n) = 2T(\dfrac{n}{2}) + O(n) = O(n \log n)$$

A common example of an algorithm whose running time has the above recurrence relation is `MergeSort`

In general, $$T(n) = cT(\dfrac{n}{c}) + O(n) = O(n\log n)$$

***

$$T(n) = T(n-1)+ T(n-2)+... + T(1) = O(2^n)$$$$where$$ where $$T(1) = 1$$

**Proof**

Let $$T(1) = 1$$. Then, $$T(2) = T(1) = 1$$.

$$T(3) = T(2) + T(1) = 1 + 1 = 2$$

$$T(4) = T(3) + T(2) + T(1) = 2 + 1 + 1 = 4$$

$$T(5) = T(4) + T(3) + T(2) + T(1) = 4 + 2 + 1 + 1 = 8$$

$$T(6) = T(5) + T(4) + T(3) + T(2) + T(1) = 8 + 4 + 2 + 1 + 1 = 16$$

It is clear from the pattern that that the running time doubles when n is increased by 1.

Hence, the solution of this recurrence is given by $$T(n) = \begin{cases} 1 \text{\qquad, if n = 1 or 2} \ 2^{n-2} \text{\quad, otherwise}\end{cases}$$

Note that the solution depends on the exact value of $$T(1)$$ and cannot be determined simply by knowing that $$T(1) = O(1)$$ because when it comes to algorithmic time complexity, the base of the exponent matters!

***

$$
T(n) = T(n/c) + O(1) = O(logn) \text{\qquad for some constant c > 1}
$$

An example of an algorithm that follows the above recurrence relation is `BinarySearch` (here, c = 2).

***

$$
T(n) = T(n/c) + O(n) = O(n) \text{\qquad for some constant c > 1}
$$

<mark style="background-color:red;">Q. Solve the following recurrence relation:</mark> $$T(n) = 2T(n-1) + O(1)$$

$$
\begin{equation\*} \begin{split} T(n) &= 2T(n-1) + O(1) \ &= 2\[2T(n-2) + O(1)] + O(1) \ &= 4T(n-2) + 2O(1) + O(1) \ \text{Assuming that }O(1) = 1, \ &= 4T(n-2) + 2 + 1 \ &= 8T(n-3) + 4 + 2 + 1 \ &= 2^n + 2^{n-1} + \dots + 4 + 2 + 1 \ &= 2^{n+1} - 1 \ &= O(2^n) \end{split} \end{equation\*}
$$

## Some Fun Time Complexity Analysis Questions

<mark style="background-color:red;">What is the order of growth of a program which has running time</mark> $$T(n) = \left(\dfrac{n^2}{17}\right)\left(\dfrac{\sqrt{n}}{4}\right) + \dfrac{n^3}{n-7} + n^2\log n$$

Answer: There is no bound! Because, as $$n$$ approaches 7, $$T(n)$$ grows without any bound. Mathematically, $$lim\_{n \xrightarrow{} 7 } T(n) = \infty$$

<mark style="background-color:red;">What is the order of growth of the following code?</mark>

```java
public static int loopy(int n) {
	int j = 1;
	int n2 = n;
	for (int i = 0; i < n; i++)
		n2 *= 5.0/7.0;
		for (int k = 0; k < n2; k++) {
			System.out.println("Hello");
		}
	}
	return j;
}
```

Answer: $$O(n)$$

It is easy to observe that the total running time is directly proportional to the number of times “hello” is printed (i.e., the number of times the inner loop runs). This can be analysed as follows

$$
\begin{equation\*} \begin{split} T(n) &= \dfrac{5}{7}n + \left(\dfrac{5}{7}\right)^2n + \left(\dfrac{5}{7}\right)^3n +.... \ &= n \left( \dfrac{5}{7} + \left(\dfrac{5}{7}\right)^2 + \left(\dfrac{5}{7}\right)^3 +.... \right) \ &= n \dfrac{\frac{5}{7}}{1-\frac{5}{7}} \ &= 2.5n \ &= O(n)\end{split}\end{equation\*}
$$

Note that even though the outer loop runs n times, since the value of `n2` falls below 1 in less than n iterations, in the last few iterations of the outerloop, the inner loop does not run at all!

This is also a good example to not just assume $$O(n^2)$$ because there is a nested for loop or assume $$O(nlogn)$$ since at each stage, n2 is reduced by a fraction. **Don’t jump to conclusions!**

$$T(n)$$ <mark style="background-color:red;">is the running time of a divide-and-conquer algorithm that divides the input of size</mark> $$n$$ <mark style="background-color:red;">**into**</mark> $$\dfrac{n}{10}$$ <mark style="background-color:red;">**equal parts**</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">and recurses on all of them. It uses</mark> $$O(n)$$ <mark style="background-color:red;">work in dividing/recombining on all of them (and there’s no other cost, i.e., no other work done). The base case for the recursion is when the input is less than size 20, which costs</mark> $$O(1)$$<mark style="background-color:red;">. What is the order of growth of</mark> $$T(n)$$<mark style="background-color:red;">?</mark>

Ans: $$O(n)$$ (Read the question carefully! IT IS NOT $$O(n\log n)$$) $$T(n) = \dfrac{n}{10}T(\dfrac{n}{n/10}) + O(n) = \dfrac{n}{10}O(1) + O(n) = O(n)$$

<mark style="background-color:red;">What is the running time of the following code, as a function of</mark> $$n$$<mark style="background-color:red;">:</mark>

```java
public static int recursiveloopy(int n) {
	for (int i = 0; i < n; i++) {
		for (int j = 0; j < n; j++) {
			System.out.println("Hello");
		}
	}
	if (n <= 2) return 1;
	else if (n%2 == 0) return recursiveloopy(n+1);
	else return recursiveloopy(n-2);
```

Ans: $$O(n^3)$$

It is obvious that the nested for loops run in $$O(n^2)$$ time. The slightly more interesting part is the recursive call. If $$n$$ is even, `recursiveloopy(n+1)` is called to make it odd. If $$n$$ is odd, `recursiveloopy(n-2)` is called (and $$n$$ remains odd). So, `recursiveloopy(n+1)` is called at most 1 time. All other times, we can safely assume that `recursiveloopy(n-2)` is called. Now, the recurrence relation would be $$T(n) = T(n-2) + O(n^2)$$ (Since we can ignore the one time that `recursiveloopy(n+1)` is called, if ever). Solving the recurrence relation,

$$$
\begin{equation\*} \begin{split} T(n) &= T(n-2) + O(n^2) \text{\qquad assume that $$O(n^2) = n^2$$} \ &= T(n-4) + (n-2)^2 + n^2 \ &= T(n-6) + (n-4)^2 + (n-2)^2 + n^2 \ .... \ &= n^2 + (n-2)^2 + ... + 5^2 + 3^2 + 1 \ &= O(n^3) \text{\qquad (Since } 1^2 + 2^2 + 3^2 + ... + n^2 = \dfrac{n(n+1)(2n+1)}{6} = O(n^3) ) \end{split} \end{equation\*}
$$$

It is clear that the sum of all even squares and sum of all odd squares should contribute nearly equally to the sum of squares of all integers from 1 through n. That is, we are estimating that the sum of squares of odd integers from 1 to n would be roughly $$\dfrac{n(n+1)(2n+1)}{12}$$, which would still be order $$O(n^3)$$

<mark style="background-color:red;">What is the running time of the following code, as a function of</mark> $$n$$<mark style="background-color:red;">:</mark>

```java
public int f(int n) {
	for (int i = 0l i < n; i++) {
		for (int j = 1; j < i; j *= 2) {
			System.out.println(".");
		}
	}
	return 0;
}
```

Ans: $$O(nlogn)$$ This is a classic example of 2 nested for loops that produce order $$O(nlogn)$$ when the inner loop variable grows by a constant factor. The detailed analysis is as follows:

During the $$i^{th}$$ iteration of the outer for loop, the inner loop runs for about $$log(i)$$iterations. So,

$$
T(n) = \sum\_{i = 1}^{n} log(i) = log(1) + log(2) + ... + log(n) = log(1\cdot 2 \cdots n) = log(n!) < log(n^n) = nlogn = O(n\log n)
$$

<mark style="background-color:red;">What is the running time of the following code, as a function of</mark> $$n$$<mark style="background-color:red;">:</mark>

```java
public String f(int n) {
	String s = "";
	for (int i = 0; i < n; i++) {
		s += "?";
	}
	return s;
}
```

Ans: $$O(n^2)$$. This appears to be $$O(n)$$ at first glance since there is only 1 for loop that runs exactly n times. However, string concatenation takes $$O(l)$$ time, where $$l$$ is the length of the string. During the $$i^{th}$$ iteration of the loop, the string is $$i - 1$$ characters long. So, adding all of them up gives us $$T(n) = \sum\_{i = 0}^{n-1} = 0 + 1 + 2 + ... + n -1 = \dfrac{n(n-1)}{2} = O(n^2)$$

<mark style="background-color:red;">What is the asymptotic running time of the following code, as a function of</mark> $$n$$ <mark style="background-color:red;">when you execute</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">`loopyloop(n,n)`</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">?</mark>

```java
public static void loopyloop(int a, int b) {
	if (b == 1) {
		for (int i = 1; i <= a; i ++) {
			System.out.println("Loopy!");
		}
	}
	else loopyloop(a - 1, b/2);
}
```

Ans: $$O(n)$$. By the time `b` equals 1, there have been $$log\_2n$$ recursive calls made to `loopyloop` and so, the value of `a` would have reduced to $$n - log\_2n$$. So, the `for` loop runs for $$n - log\_2n$$ times. This is still $$O(n)$$.

<mark style="background-color:red;">What is the asymptotic running time of the following code, as a function of</mark> $$n$$ <mark style="background-color:red;">when you execute</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">`doubleTwist(n,n)`</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">?</mark>

```java
public static void doubleTwist(int a) {
	if (a == 1) return
	twist(a/2);
	twist(a/2);
}
public static void twist(int b) {
	if (b == 1) return;
	doubleTwist(b/2);
	doubleTwist(b/2);
}
```

Ans: Let the running time of `doubleTwist` be $$f(n)$$ and that of `twist` be $$g(n)$$. Then, $$f(n) = 2g(n/2) + O(1)$$ and $$g(n) = 2f(n/2) + O(1)$$. We can draw out the recursive tree or we can solve the recurrence relation rigorously. Either way the answer is $$O(n)$$.

$$
f(n) = 2 \times g(n/2) = 4 \times f(n/4) = 16 f(n/16) = \dots = O(n)
$$

<mark style="background-color:red;">Find the running time of the following program as a function of n (Assume that</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">`isDivisible(x,y)`</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">takes</mark> $$O(1)$$ <mark style="background-color:red;">to run):</mark>

```java
public static boolean isPrime(int n) {
	if (n < 2) return false;
	for (int i = 2; i <= sqrt(n); i++) {
		if (isPrime(i) && isDivisible(n,i)) {
			return false;
		}
	}
	return true;
}
```

Ans: $$O(n)$$

Let us consider the recurrence relation of the function. $$T(n) = \sqrt{n} + \sum\_{i = 2}^{\sqrt{n}}T(i)$$

This is because the for loop runs for $$O(\sqrt{n})$$ times (and each call of `isDivisible` is $$O(1)$$). So, excluding the recursive call, the time complexity of $$T(n)$$ should be $$O(\sqrt{n})$$. But it also makes recursive calls in every loop - so we add those too.

Note that this is not a trivial recurrence relation to solve.

$$
\begin{equation\*} \begin{split} T(n) &= \sqrt{n} + \sum\_{i = 2}^{\sqrt{n}}T(i) \ &\leq \sqrt{n} + \sqrt{n}\times T(\sqrt{n}) \ & = n^{1/2} + n^{1/2}\times T(n^{1/2}) \ &= n^{1/2} + n^{1/2}(n^{1/4} + n^{1/4}\times T(n^{1/4})) \ &= n^{1/2} + n^{3/4} + n^{3/4}T(n^{1/4}) \ &= n^{1/2} + n^{3/4} + n^{3/4}(n^{1/8} + n^{1/8} \times T(n^{1/8})) \ & = n^{1/2} + n^{3/4} + n^{7/8} + n^{7/8} \times T(n^{1/8}) \ \dots \ \dots \ &= n^{1/2} + n^{3/4} + n^{7/8} + \dots + nT(1) \ &= nT(1) + \dots + \dfrac{n}{n^{1/32}} + \dfrac{n}{n^{1/16}} + \dfrac{n}{n^{1/8}} + \dfrac{n}{n^{1/4}} + \dfrac{n}{n^{1/2}}\ \text{Let us assume that }T(1) = 1/2. \text{ Then,}\ T(n) &= \dfrac{n}{2} + \dfrac{n}{2^2} + \dfrac{n}{2^4} + \dfrac{n}{2^8} + \dots \ &= n \sum\_{i = 0}^{\infty} \dfrac{1}{2^{2^i}} = O(n) \text{\qquad since }\sum\_{i = 0}^{\infty} \dfrac{1}{2^{2^i}} \text{ is a constant approximately equal to 0.816} \end{split} \end{equation\*}
$$

## Big-O Notation Questions

<mark style="background-color:red;">Is</mark> $$2^{2n} = O(2^n)$$<mark style="background-color:red;">?</mark>

Ans: No! $$2^{2n} = 2^n 2^n = 4^n \neq O(2^n)$$ (The base of the exponent matters!)

<mark style="background-color:red;">Is</mark> $$log\_2n = O(log\_{10}n)$$<mark style="background-color:red;">?</mark>

Ans: Yes!! Because they differ only by a constant ($$log\_2n = log\_{10}n\* log\_210$$)

<mark style="background-color:red;">What is the best (tightest) asymptotic upper bound for the following?</mark>

$$f(n) = 2^{4logn} + n^5$$

Ans: $$O(n^5)$$. Because, $$2^{4logn} = 2^{logn^4} = n^4$$ (obviously we assume that the base of log is 2 since we are computer scientists :) )

$$f(n) = 2^{2n^2 + 4n + 7}$$

Ans: $$O(2^{2n^2 + 4n})$$. Only $$2^7$$ is a constant. All other terms are being multiplied (not added!) and hence, cannot be ignored as being insignificant. In particular, the answer cannot be $$O(2^{n^2})$$ or $$O(2^{2n^2})$$ since you are forgetting to multiply a factor of $$2^{4n}$$which is essentially $$16^n$$, not a constant!

## Amortized Analysis

It is a common technique for analyzing “average” cost per operation. We use this when most operations are cheap but once in a while, we need to pay a lot. This is similar to how you pay rent: you don’t pay rent every second or every day (although you could technically). So, you can think of it like you’re living for free on 29 days of the month and on 1 day you need to pay a large amount. But of course this does not give the true picture - so you find the cost you’re paying per day.

Similarly, we use amortized analysis for data structures.

**An operation is said to have amortized cost** $$T(n)$$ **if, for every integer** $$k$$**, the cost of** $$k$$ **operations is** $$\leq kT(n)$$

When we say $$k$$ operations, we mean $$k$$ continuous operations, starting from the first operation. You cannot pick any random $$k$$ operations from the middle and say that the amortized cost is so high.

In other words, for every prefix sequence, the total cost of that sequence of operations cannot exceed $$T(n)$$ times the length of that prefix sequence.

Amortized ≠ Average! Amortized is a much stronger constraint than average since it needs to hold for **every** value of $$k$$. In case of average, the total cost of **all** operations should not exceed $$T(n)$$ times the total number of operations.

Example (hash table): Inserting $$k$$ elements into a hash table takes time $$O(k)$$. Therefore, the insert operation has amortized cost $$O(1)$$.

### Accounting Method

Imagine a bank account $$B$$. Each operation performed adds money to the bank acconut. Every step of the algorithm spends money:

* Immediate money: to perform that particular operation
* Deferred operation: from the bank account

Total cost of execution = total money (Average time per operation = total money divided by number of operations)

For each operation, you are given $$T(n)$$ time. For most operations you need less than that. So, you’re saving the time when performing cheap operations and using that saved time to perform expensive operations (that take $$\geq T(n)$$ ) once in a while.

### Binary Counter Amortized Analysis

Binary counter ADT is a data structure that counts in base two, i.e. 0s and 1s. Binary Counter ADT supports two operations:

* increment() increases the counter by 1.
* read() reads the current value of the binary counter

To make it clearer, suppose that we have a k-bit binary counter. Each bit is stored in an array `A` of size $$k$$, where `A[k]`denotes the k-th bit (0-th bit denotes the most significant bit). For example, suppose `A = [0, 1, 1, 0]`, which corresponds to the number $$110$$ in binary. Calling `increment()` will yield `A = [0, 1, 1, 1]`, i.e. $$111$$. Calling `increment()` again will yield `A = [1, 0, 0, 0]`, the number $$1000$$ in binary.

Suppose that the k-bit binary counter starts at 0, i.e. all the values in A is 0. A loose bound on the time complexity if `increment()` is called $$n$$ times is $$O(nk)$$ (since each operation flips at most $$k$$ bits). What is the amortized time complexity of increment() operation if we call `increment()` n times?

Let us look at a few operations to gain some insight into the amortized cost (the cost is essentially just the number of bits we need to flip):

| $$n$$ (`increment` index) | Binary Counter | Cost of operation | Total cost of $$n$$ operations | Total cost/$$n$$ |
| ------------------------- | -------------- | ----------------- | ------------------------------ | ---------------- |
| 1                         | `[0,0,0,0,1]`  | 1                 | 1                              | 1                |
| 2                         | `[0,0,0,1,0]`  | 2                 | 3                              | 1.5              |
| 3                         | `[0,0,0,1,1]`  | 1                 | 4                              | 1.3              |
| 4                         | `[0,0,1,0,0]`  | 3                 | 7                              | 1.75             |
| 5                         | `[0,0,1,0,1]`  | 1                 | 8                              | 1.6              |
| 6                         | `[0,0,1,1,0]`  | 2                 | 10                             | 1.67             |
| 7                         | `[0,0,1,1,1]`  | 1                 | 11                             | $$< 2$$          |
| 8                         | `[0,1,0,0,1]`  | 4                 | 15                             | $$< 2$$          |

So, for each operation, if we assign a cost of $$2$$, the “bank balance” will never be negative and we can pay for expensive operations using previously saved money.

We can solve this problem using the Accounting Method – having a “bank” of “time saved up” which pays for expensive operations. We know to use amortized analysis on this question because increment takes a variable number of flips (read: some operations are expensive and others are cheap), and we are looking for a tighter bound than $$O(nk)$$ where $$n$$ is the number of times increment is called and $$k$$ is the total number of digits.

**We can also observe that in order for a digit to be flipped to 0, it must have been flipped to 1 first. By the accounting method, we want to “save” up for the more expensive operations, which is when many 1s have to be flipped to 0s. We propose that each flip of a bit takes 2 units of time - 1 unit to flip from 0 to 1, and 1 unit to be saved in the bank for when the bit must be flipped from 1 to 0 in the future. This has the invariant that the amount in the bank never dips below 0 (as when you flip the bit from 0 to 1, you pay in advance for the future flip back to 0). Hence the amortised bound is 2 flips per increment. Increment is** $$O(1)$$ **in amortized time per increment and** $$n$$ **increments is bounded by** $$O(n)$$**.**

Observe that the 0th bit flips $$n$$ times when increment is called $$n$$ times. The 1st bit flips $$n/2$$ times when increment is called $$n$$ times. The 2nd bit flips $$n/4$$ times when increment is called $$n$$ times. And so on. Also observe that in a sequence of $$n$$ operations, the total number of flips is $$n + n/2 + n/4 + \dots + 1 \leq 2n$$. So, the total cost of $$n$$ operations is $$\leq 2n$$ (Notice that this is true for any value of $$n$$ by the nature of how binary counting works)

### Stack 2 Queue

It is possible to implement a queue using two stacks. But is it really efficient? (a) Design an algorithm to push and pop an element from the queue. (b) Determine the worst case and amortized runtime for each operation

(a) Let’s call the two stacks as $$S\_1$$ and $$S\_2$$. When we push an element, we push it to stack $$S\_1$$. When we want to pop an element, note that the first element pushed in $$S\_1$$ should be popped first. We should pop the elements from $$S\_1$$ one by one and push it back at the same time to S2. Note that the ordering will be reversed in $$S\_2$$, hence when we pop from $$S\_2$$, it will be the first element pushed in $$S\_1$$. Therefore, when pop operation is called, we pop the element from $$S\_2$$. If $$S\_2$$ is empty, then we transfer the elements in $$S\_1$$ to $$S\_2$$.

(b) The worst case for one operation is $$O(n)$$, where n is the number of inserted elements. However, the amortized cost is much smaller than that. We will prove that the amortized cost for each operation is $$O(1)$$ using Accounting Method. Whenever we push a new element, we will deposit $2 to the bank. When we transfer an element from $$S\_1$$ to $$S\_2$$ or popping an element from $$S\_2$$, we will pay $1. Note that when pop is called and $$S\_2$$ is empty, we have at least $2k deposited in the bank, where k is the number of inserted elements in $$S\_1$$. This is enough money to pay for the transferring cost that takes $$O(k)$$ time. Note that the remaining money $2k − $k = $k can be used to pay for when the element is popped from $$S\_2$$.

## Clarification

There is a very important distinction between worst-case analysis, big-O notation, average-case analysis, expected time analysis, big-theta notation, etc.

Worst case analysis deals with the worst possible kind of input to a program. We carefully handpick the worst possible input by analysing how the algorithm works. When we say that insertion sort takes $$\Theta(n^2)$$ in the worst case, we mean that the algorithm running time grows quadratically as the array size increases and the worst possible input (e.g. reversed array) is fed to the program. It is not necessary to use $$O$$ while talking about worst-case analysis.

$$O(f(n))$$ simply represents a family of functions that grow slower than $$cf(n)$$ for some positive constant $$c$$, i.e., $$T(n) \in O(f(n)) \implies \exists n\_0, c \quad \forall n>n\_0 \quad cf(n) > T(n)$$. We often abuse notation and for convenience, simply write that $$T(n) = O(f(n))$$ to mean that the running time $$T(n)$$ is upper bounded by $$f(n)$$. BUT this does not give us any information regarding what type of running time we are dealing with or what scenario we are analysing.

Average-case analysis deals with how the program performs when a **random input** is fed to the algorithm. It is important to note that here, while the input is random, the program may still be deterministic.

An indeterministic program is one which makes **random choices** while the algorithm is running. When talking about indeterministic programs, the running time is a random variable (it depends on the random choice made by the algorithm). In fact, even for the same input, the running time may vary. For example, in case of `QuickSort` the running time depends heavily on the choice of a pivot. So, it is more practical to talk about the expected running time of a randomised algorithm.

In short, big-O and big-theta notations only give us bounds of a function. They do not tell us anything about the scenario for which the function is being considered.

In CS2040S, we normally consider the worst-case scenario unless otherwise specified.


# Binary Search

### **Pre-condition**

The array you are searching should be sorted (or more generally, the function should be monotonic)

### **Aim**

Given a sorted array, find an element in the array (and return its index). Return -1 if the element is not in the array.

### **Invariant**

If you are searching for key in an array (and key actually exists in the array),then `A[begin] <= key <= A[end]`is true at every step of the procedure.

### **Code**

```java
public int BSearch(A, key, n) {
	begin = 0;
	end = n - 1;
	while begin < end {
		mid = begin + (end - begin)/2 // to avoid overflow error, we don't use (begin+end)/2
		if key <= A[mid] {
			end = mid;
		} else {
			begin = mid + 1;
		}
	return (A[begin] == key) ? begin : - 1
```

### **Running time**

$$O(\log n)$$

At each stage, the array size to be searched splits in half. So, the running time reccurence relation is $$T(n)= T(\dfrac{n}{2}) +O(1)$$. The solution to this recurrence relation can easily be determined to be $$O(\log n)$$.

Binary search is often a part of much larger solution to a complicated problem. For example, you can binary search over the range of possible answers if you have a lower bound and an upper bound, and you have some monotonic property.

### Questions

<mark style="background-color:red;">**Random number guesser -**</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">Given that a random number has been chosen between 1 and 1024, guess the number correctly in less than 12 tries. Every time you make a guess, you will know whether your guess was too high or too low.</mark>

Ans: Just apply Binary Search with `begin = 1`and `end = 1024`

<mark style="background-color:red;">**Smallest Indistinguishable Integer -**</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">Given that there exists a limit beyond which integers cannot be represented effectively in a computer system, your task is to find the smallest number that is indistinguishable from its successor. An integer</mark> $$i$$ <mark style="background-color:red;">is said to be indistinguishable if</mark> $$i == i + 1$$ <mark style="background-color:red;">returns true.</mark>

Ans: Consider the function `boolean isDistinguishable(int i)`.Observe that the function here is monotonic. In other words, once the function crosses a certain threshold (that we need to find), it will always return indistinguishable, whereas it will always return distinguishable for values before the threshold. So, first try to the largest power of 2 (by multiplying by 2 at each iteration) that can be represented effectively, i.e, find $$j$$ such that $$2^j$$ is distinguishable but $$2^{j+1}$$ is not. Then apply Binary Search to find the exact integer between $$\[2^j, 2^{j+1}]$$.


# Sorting Algorithms

<table data-full-width="true"><thead><tr><th>Property</th><th>Bubble Sort</th><th>Insertion Sort</th><th>Selection Sort</th><th>Merge Sort</th><th>QuickSort (first element pivot)</th><th>QuickSort (random pivot)</th></tr></thead><tbody><tr><td><strong>Stablity</strong></td><td>Yes</td><td>Yes</td><td>No</td><td>Yes</td><td>No</td><td>No</td></tr><tr><td><strong>Running time</strong></td><td><span class="math">O(n^2), \Omega(n)</span></td><td><span class="math">O(n^2), \Omega(n)</span></td><td><span class="math">\Theta(n^2)</span></td><td><span class="math">\Theta(nlogn)</span></td><td><span class="math">O(n^2)</span></td><td><span class="math">E[T(n)] = O(nlogn)</span></td></tr><tr><td><strong>Worst case input</strong></td><td>Reversed array</td><td>Reverse array</td><td>All inputs</td><td>All inputs are average-case</td><td>Sorted array</td><td>All inputs are average-case</td></tr><tr><td><strong>Invariant</strong></td><td>At the end of the <span class="math">i^{th}</span> iteration, largest <span class="math">i</span> elements are sorted in their correct positions.</td><td>At the end of the <span class="math">i^{th}</span> iteration, the first <span class="math">i</span> elements in the array are relatively sorted</td><td>At the end of the <span class="math">i^{th}</span> iteration, the smallest <span class="math">i</span> elements are correctly sorted in the first <span class="math">i</span> positions of th array.</td><td>For every call to merge, both its arguments are always sorted.</td><td>After performing the partition, all elements smaller than the pivot occur before the pivot, and all elements larger than the pivot occur after the pivot</td><td>After performing the partition, all elements smaller than the pivot occur before the pivot, and all elements larger than the pivot occur after the pivot</td></tr><tr><td><strong>Extra space</strong></td><td><span class="math">O(1)</span> (In-place)</td><td><span class="math">O(1)</span> (In-place)</td><td><span class="math">O(1)</span> (In-place)</td><td><span class="math">O(n)</span></td><td><span class="math">O(1)</span> (In-place)</td><td><span class="math">O(1)</span> (In-place)</td></tr></tbody></table>

## Bubble Sort

**Algorithm:** Swaps adjacent elements if they are out of order. After each iteration, the next heaviest element bubbles to the end of the array.

**Proof of correctness:** At the end of n iterations, the n heaviest elements are in their sorted positions —> the array is sorted

Since swapping is only done between adjacent elements, it is easy to make the algorithm stable (only do swaps in case of strict inequality).

It is possible to implement a version that terminates as soon as no swaps performed for a complete loop. In such a case, the time taken to sort an already sorted array is $$\theta(n)$$.

Bubble Sort is quite inefficient and is rarely used in practical applications.

```java
BubbleSort(A, n) {
	for (int i = 0; i < n; i++) {
		for (int j = i; j < n - 1; j++) {
			if A[j] > A[j+1] swap(A, j, j + 1)
		}
	}
}
```

```java
OptimisedBubbleSort(A, n) {
	repeat (until no swaps):
		for (int j = 1; j < n - 1; j++):
			if A[j] > A[j+1] then swap(A, j, j + 1)
	
```

## Insertion Sort

**Algorithm**: Maintain a sorted prefix (beginning with the first element). For every iteration, insert the next element into the correct position in the sorted prefix.

**Invariant**: At the end of the $$i^{th}$$ iteration, the first $$i$$ elements in the array are relatively sorted.

Since swaps are performed between adjacent elements, it is easy to ensure stability by only swapping in case of strict inequality.

Best case scenario: already sorted array or very few elements out of place. eg. $$A = \[2,3,4,5,6,1]$$ performs significantly lower number of swaps than $$A = \[6,5,4,3,2,1]$$. You only need to perform 5 swaps to bring 1 to its correct positions. All other elements are relatively sorted.

```java
InsertionSort(A, n):
	for (int i = 1; i < n; i++):
		key = A[i];
		j = i - 1;
		while (j >= 0 and A[j] > key): // Repeats at most i times (the max distance that a key needs to move is i)
			A[j+1] = A[j] //Shift the elements by 1
			j--
		A[j+1] = key // Put the key in the correct position
```

Sometimes, its better to use insertion sort than `MergeSort`. For example, when you know that the list is mostly sorted, insertion sort performs very well. Moreover, even for unsorted arrays of any kind, if the length is less than 1024, insertion sort runs faster in practice than `MergeSort`.

## Selection Sort

**Algorithm**: Find the minimum element. Swap it to the first element in the unsorted array. Continue on the remaining elements.

**Proof of correctness**: After n iterations, the minimum n elements are in their sorted positions —> the array is sorted

**Invariant**: There is a sorted prefix being maintained. At the end of each iteration, the size of the sorted prefix grows by 1 and the size of the unsorted portion decreases by 1. It is important to note that this sorted prefix is absolutely sorted with respect to the entire array, i.e., the elements in the sorted prefix are in their correct positions relative to the entire array too. This is in contrast to insertion sort, in which, after each iteration, the size of the sorted prefix grows by 1 too, but the elements are relatively sorted —> their positions need not be the correct position w\.r.t. the entire array.

Finding the minimum element takes $$O(n)$$ time even if the array is sorted (because we don’t know if the array is sorted or not). So, the total algorithm takes $$\Theta(n^2)$$ irrespective of the input.

Since the swapping of elements is performed with other elements in between, it does not guarantee stability. An example would be the following array:

$A = \[3, 2, 3, 1, 3]$$. The swap is performed between A\[0] and A\[3], in which case the ordering of the 3’s changes. Hence, selection sort is unstable.

```java
SelectionSort(A, n):
	for (int j = 0; j < n; j++):
		let k be the index of minimum element in A[j...n-1]
		swap(A, j, k)

```

## Merge Sort

Classic recursive divide-and-conquer algorithm. Split the array in half. MergeSort each half. Merge the two sorted halves together.

Merging two arrays of length $$\dfrac{n}{2}$$ each takes $$O(n)$$ time.

MergeSort can be made stable by adding the element from the left half in case both elements are equal.

The recursive relation of the time complexity for MergeSort is: $$T(n) = 2 T(\dfrac{n}{2}) + O(n)$$. Solving the recursive relation gives $$T(n) = O(n logn)$$

The **total** space consumed by `MergeSort` is also $$O(nlogn)$$ (Note that at any given time, the space being used is $$O(n)$$ but in **total**, the algorithm uses $$O(nlogn)$$ space). At each level of the recursion, you need an array of length n to store the sorted portions of the origninal array. Another way to explain this is that all the time spent during `MergeSort` is essentially to use up space. This is because, merging two arrays requires space equal to the sum of the lengths of both halves. So, you’re spending all the time during merge to put elements in the new array. Since we proved that $$T(n) = O(n logn)$$, it follows that $$S(n) = O(n logn)$$.

However, there is a space optimisation possible in which only $$O(n)$$ space is consumed. ($$S(n) = 2S(\dfrac{n}{2}) + O(1) = O(n)$$). Just reuse the same temporary array at each level of the recursive tree. Don’t allocate new memory for each recursive level. This is because, for any call to `Merge`, you only need the current ordering of the elements and not the ones before that.

Hence, for all references to `MergeSort` in the exam, assume it uses $$O(n)$$ space.

(The following implementation uses $$O(n\log n)$$ space since it creates .)

```java
MergeSort(A, n):
	if (n == 1) return;
	else:
		x = MergeSort(A[1...n/2],n/2);
		y = MergeSort(A[n/2 + 1... n], n/2);
		return Merge(x,y,n/2);

Merge(A, B):
	int i = 0;
	int j = 0;
	int[] result = new int[A.length + B.length];
	while (i < A.length && j < B.length) {
		if (A[i] <= B[j]) { // equality ensures stability, i.e., if they are equal, pick from left.
			result[i + j] = A[i] 
			i++;
		} else {
				result[i + j] = B[j];
				j++;
		}
	}

	// Exactly one of the following while loops will be executed (since the above while loop terminated, it means that one of the
	// pointers is now equal to the length of the corresponding array
	
	while (i < A.length) {
		result[i + j] = A[i];
		i++;

	while (j < B.length) {
		result[i + j] = B[j];
		i++;

	return result

```

`MergeSort` can be slower than `InsertionSort` when the number of items to sort is very small. This is due to caching performance, branch prediction, etc. So, for `array.length < 1024` it is advisable to use insertion sort. Moreover, the best algorithm might be to use insertion sort in the base case of recursion during MergeSort (the base case would be `if array.length < 1024: return InsertionSort(array)`).

If you use an iterative version of `MegeSort`(with 2 nested for loops), you have a loop invariant: After the $$i^{th}$$ iteration, every chunk of size $$2^i$$ starting from the first element is sorted.

#### Iterative MergeSort

For the iterative MergeSort, we will sort the array in groups of power of 2. In other words, we will first sort the arrays in pairs, then merge into 4’s, 8’s and so on, until we have merged the entire array.

For each given size i (that is a power of 2),

* Copy the first i/2 elements into a left array and the next i/2 elements into the right array
* Set the left pointer and right pointer to the first element of each array, and array pointer to the first element of the original array
* Repeat until there is no more element in both arrays

  – Check the first element of the left and right array, and place the smaller element at index array pointer in the original array

  – Increment the pointer for the array containing the smaller number, and – Increment the array pointer
* Repeat the above for the next power of 2

In the iterative MergeSort, each size requires $$O(n)$$ operation to perform the merge operation, where n is the length of the array. The possible number of sizes is $$logn$$. And hence, the runtime complexity is $$O(n \log n)$$.

For space complexity, we only require an additional auxillary array, and thus it only requires $$O(n)$$ space.

## QuickSort

**Invariant**: After performing the partition, all elements smaller than the pivot occur before the pivot, and all elements larger than the pivot occur after the pivot.

It is also a divide-and-conquer algorithm like `MergeSort`.

If randomised pivot is chosen, the expected running time of the algorithm (with very high probability) is $$O(n\log n)$$.

This is because, for any deterministic pivot selection algorithm, is it possible to produce an adversarial “bad” input such that the algorithm runs in $$O(n^2)$$. This is an example of worst-case analysis

Stability cannot be ensured since swaps are being performed with other elements in between. For example, consider the following example in case of the pivot being equal to 5: `A = [8, 2, 5, 3, 8, 3]`. When partition occurs about 5, `A[0]` and `A[5]` swap, and the first 8 moves behind the other 8, violating stability.

QuickSort is very fast in practice and many optimizations are also possible. Its variants (eg. dual pivot QuickSort) are used almost ubiquitously in the implementation of sorting algorithms in programming languages.

In case of duplicate elements, we can use three-way partitioning to prevent the running time from being $$O(n^2)$$.

```java
QuickSort(A[1...n],n):
	if (n == 1) return
	else:
		// Somehow choose pivot index pIndex
		p = partition(A[1...n],n, pIndex) // partition returns the position of the pivot after the partition procedure
		x = QuickSort(A[1...p-1],p-1)
		y = QuickSort(A[p+1...n], n-p)

partition(A[1...n], n, pIndex):
	pivot = A[pIndex] // store the pivot value in another variable
	swap(A, 1, pIndex) // move the pivot to the front of the array
	low = 2 // start after the pivot
	high = n + 1 // Define A[n+1] = infinity
	while (low < high):
		while (A[low] < pivot) and (low < high) do low++ // increment low till you find an element that is greater than pivot
		while (A[high] > pivot) and (low < high) do high -- // decrement high till you find an element smaller than pivot
		if (low < high) swap(A, low, high);
	swap(A, 1, low - 1) // move the pivot to its correct position, which is at index low - 1
	return low - 1 // return the index of the pivot after partitioning - now the pivot is in its correct sorted position.
```

### QuickSort with 3-Way Partitioning

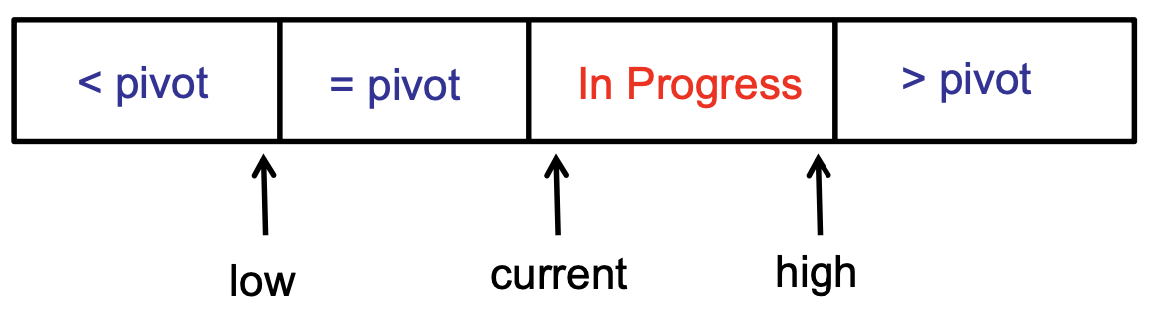
<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2F9KPKgNxC8LxaN7YoACre%2FScreenshot_2022%2003%2002_at_8.06.35_PM.png?alt=media" alt=""><figcaption></figcaption></figure>

**Option 1: 2 passes of the array** (Easier to understand and still $O(n)$ for partition)

1. Regular partition
2. Pack duplicates (swap all the elements in the left half that are equal to the pivot to be adjacent to the pivot)

**Option 2: 1 single pass**

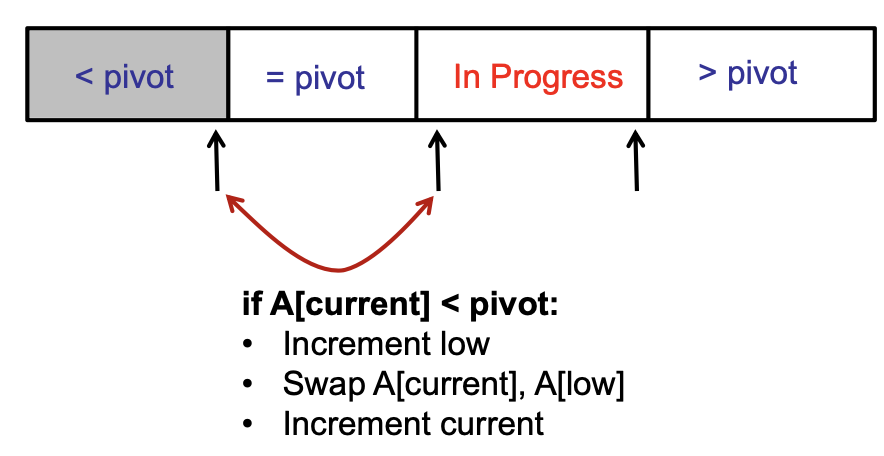
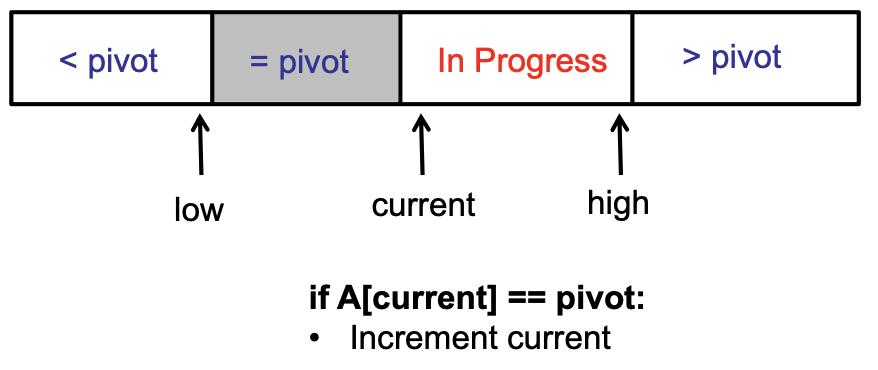
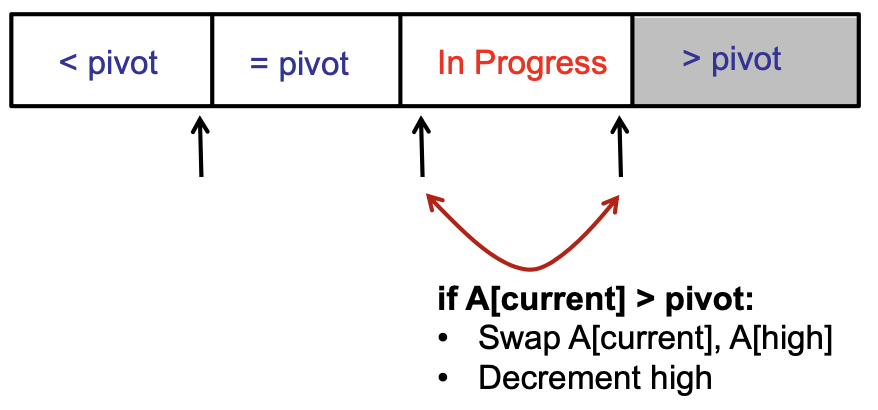
Maintain 4 regions of the array

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FZ0jH3PmboHJCXj0wVWVV%2FScreenshot_2022%2003%2002_at_8.07.45_PM.png?alt=media" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FZAYCMvTlLEkNvQ5a00on%2FScreenshot_2022%2003%2002_at_8.08.24_PM.png?alt=media" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fi7OnHvhaqzQLJweK9nrq%2FScreenshot_2022%2003%2002_at_8.08.34_PM.png?alt=media" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fks0GRIfSnNPvfDdOfU25%2FScreenshot_2022%2003%2002_at_8.09.07_PM.png?alt=media" alt=""><figcaption></figcaption></figure>

The key invariants for this are:

* Each region has proper elements (< pivot, = pivot, > pivot)
* Each iteration, In Progress region decreases by one

### Analysing Complexity of QuickSort

First, lets try and find the time complexity of a deterministic implementation of `QuickSort`, say one that picks the first element as the pivot. Then, the worst-case running time would be $$\Theta(n^2)$$ when the array is already sorted (or reverse sorted). The recurrence relation would be $$T(n) = T(n-1) + T(1) + \Theta(n) = 1 + 2 + 3 + \dots + n = \Theta(n^2)$$.

Since `QuickSort` is a randomised algorithm, its running time is also a random variable. Hence, it is more useful to talk about expected running time of the algorithm. To make it easier to analyze, we consider a paranoid version of `QuickSort` that repeatedly finds a pivot that divides the array such that the bigger half is at most $$9/10$$th of the total array size. In other words, we only move to the recursive calls if we are sure that the pivot is not terribly bad (for example, if we pick the smallest element as the pivot it would be a bad pivot). Then the expected running time would be $$E\[T(n)] = E\[T(9n/10)] + E\[T(n/10)] + E[#partitions](https://cs2040s.devanshshah.dev/n)$$. Note that we need to find out the expected number of times we would have to try before we get a good pivot (this is denoted by $$#partitions$$). If this turns out to be a large number, that is bad!

Note that in a randomised algorithm, the algorithm makes random choices (such as the choice of pivot index in this case) and for every input, there is a good probability of success. This is in contrast to average-case analysis in which the algorithm may be deterministic and the environment chooses random inputs (based on some heuristic or statistical distribution)! Some inputs are good, some inputs are bad. For most of the inputs, the algorithm does fairly well.

```java
ParanoidQuickSort(A[1...n],n)
	if (n == 1) return
	else
		repeat
			pIndex = random(1,n)
			p = partition(A[1...n], n, pIndex)
		until p > (1/10)n and p < (9/10)n
		
		x = QuickSort(A[1...p-1, p-1)
		y = QuickSort(A[p+1...n], n-p)
```

Every time we recurse (call `QuickSort`), we reduce the problem size by at least 1/10.

**Claim**: We only execute the repeat loop $$O(1)$$ times in expectation. Then we know $$T(n) \leq T(n/10) + T(9n/10) + n\*#iterations = O(nlogn)$$.

**Proof:**

A pivot is “good” if it divides the array into 2 pieces, each of which is at least size $$n/10$$. If we pick a pivot at random, what is the probability that it is “good”? Ans: $$8/10$$. Then, probability of choosing a bad pivot is $$2/10$$.

$$
E\[#choices] = \dfrac{8}{10}\*1 + \dfrac{2}{10}(E\[#choices] + 1)
$$

Explanation: If you get a good pivot (with probability 8/10, you are done in just 1 iteration). If not (with probability 2/10), you need to repeat the process and include the fact that you already tried once.

Then, $$\dfrac{8}{10}E\[#choices] = 1 \implies E\[#choices] = \dfrac{10}{8}$$. So, in expectation, we only need to choose a pivot $$10/8$$ times to get a good pivot.

Then, $$T(n) \leq T(n/10) + T(9n/10) + 2n = O(n\log n)$$. This follows from the fact that whenever you divide a problem into two parts by reducing them by a constant factor and then recurse on each of them separately, it takes $$O(nlogn)$$ time if the work done in combining/dividing the work is $$O(n)$$. In particular, the solution to $$T(n) = T(n/c) + T(n-\dfrac{n}{c}) + O(n)$$ is $$O(n\log n)$$.

Hence, randomised `QuickSort` has an expected running time of $$O(n\log n)$$

### More Pivots!

<mark style="background-color:red;">So, we have shown that</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">`QuickSort`</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">is pretty fast. But that was only with one 1 pivot? Can we improve it by using 2 pivots? What about</mark> $$k$$ <mark style="background-color:red;">pivots? What would the asymptotic running time be?</mark>

Okay, so we want to find the running time of `QuickSort` with $$k$$ pivots. The following steps are involved:

1. Selecting $$k$$ random indices to be the pivot indices - for ease, lets just take this to be a constant time operation. (Even if you consider this to be $$O(k)$$, it will give the same answer).
2. Sorting the pivots in order - $$O(k\ log(k))$$ - Either use `MergeSort` or the ordinary `QuickSort`.
3. Now, you have $$n-k$$ remaining elements to be put in $$k + 1$$ possible buckets (between each of the pivots). For each of the element, it takes $$log(k+1)$$ time to find the correct bucket using Binary Search. So the total running time is $$\approx (n-k)log(k)$$
4. Now, we perform this recursively on each of the $$k+1$$ buckets.

Overall, the recurrence relation is $$T(n) = (k+1)T(\dfrac{n-k}{k + 1}) + O(nlogk)$$.

All this simplifies to approximately $$T(n) = kT(\dfrac{n}{k}) + O(nlogk)$$. Assuming that $$k$$ is just a constant greater than 1, the asymptotic running time is $$O(n(log\_kn)(logk)) = O(nlogn)$$

So, more pivots does not lead to a better asymptotic running time. But then why do we use dual-pivot quicksort? Because it is much faster in practice. Dual-pivot quicksort takes advantage of modern computer architecture and has reduced cache misses.

### Another Question

Consider a QuickSort implementation that uses the 3-way partitioning scheme (i.e. elements equal to the pivot are partitioned into their own segment).

i) I<mark style="background-color:red;">f an input array of size n contains all identical keys, what is the asymptotic bound for QuickSort? For example, you are sorting the array</mark> $$\[3, 3, 3, 3, 3, 3]$$

Solution: It should always take $$O(n)$$ time, as after the first partitioning pass (which takes $$O(n)$$), the “unsorted” segments would be empty.

ii) <mark style="background-color:red;">If an input array of size n contains</mark> $$k < n$$ <mark style="background-color:red;">distinct keys, what is the asymptotic bound for</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">`QuickSort`</mark><mark style="background-color:red;">? For example, with</mark> $$n = 6,k = 3$$<mark style="background-color:red;">, sort the array</mark> $$\[a,b,a,c,b,c]$$

Solution: We can think of each level in the recursion tree of QuickSort as a result of partitioning using only 1 distinct pivot. As there are only $$k$$ distinct keys in the array, up to $$k$$ pivots would be chosen in the whole QuickSort run, and so this bounds the height of our recursion tree (in the worst case) to be $$O(k)$$. As we have no information on how many of each key we have, we can only assume that at every level of the tree, $$O(n)$$ time would be used for partitioning. So, putting them together the asymptotic bound should be $$O(nk)$$.

If our pivot selection is guaranteed to be balanced, the asymptotic bound should be $$O(n log k)$$ (Because at each level, we choose 2 times the number of pivots we chose at an earlier level. So, it is a balanced binary tree with $$k$$ nodes —> height = $$O(logk)$$ ).

### Stability?

<mark style="background-color:red;">Are any of the partitioning algorithms we have seen for QuickSort stable? Can you design a stable partitioning algorithm? Would it be efficient?</mark>

All partitioning algorithms we've seen so far are not stable. However, we can make them stable by associating the original indices of each key with the key - a simple way would be to create an auxiliary array of indices which swaps will be performed on too. Original Array : $$\[1, 2, 5, 3, 5, 3, 8, 7, 2]$$ Auxiliary Array : $$\[0, 1, 2, 3, 4, 5, 6, 7, 8]$$ When comparing elements, the auxiliary array would be used to disambiguate elements with equal keys, creating a “**total ordering**” between every key. For example, when comparing the two 2s in the original array, the sorting algorithm will take a look at the auxiliary array to determine which value came first in the original array (1 or 8). Note that by doing so, the partitioning algorithm is no longer in-place since an auxiliary array is needed to store the original indices. Consider an example to explain: Assume that we ran `QuickSort` once on the original array and the pivot chosen was 5 (bad!). The swaps were performed and after the partition, the array looks like this: $$\[1, 4, 4, 2, 4, 5]$$. Since we stored a value associated with every key, we also have the auxiliary array to be: $$\[0,2,1,4,3,5]$$. Now, if the element at index 2 is chosen as the pivot, we know that the 4 at index 1 is supposed to be after the pivot (using the values in the auxiliary array) even though both of them have the same key = 4. This helps us ensure the correct ordering.

### Application of QuickSort

<mark style="background-color:red;">Your aunt and uncle recently asked you to help out with your cousin’s birthday party. Alas, your cousin is three years old. That means spending several hours with twenty rambunctious three year olds as they race back and forth, covering the floors with paint and hitting each other with plastic beach balls. Finally, it is over. You are now left with twenty toddlers that each need to find their shoes. And you have a pile of shoes that all look about the same. The toddlers are not helpful. (Between exhaustion, too much sugar, and being hit on the head too many times, they are only semi-conscious.) Luckily, their feet (and shoes) are all of slightly different sizes. Unfortunately, they are all very similar, and it is very hard to compare two pairs of shoes or two pairs of feet to decide which is bigger. (Have you ever tried asking a grumpy and tired toddler to line up their feet carefully with another toddler to determine who has bigger feet?) As such, you cannot compare shoes to shoes or feet to feet. The only thing you can do is to have a toddler try on a pair of shoes. When you do this, you can figure out whether the shoes fit, or if they are too big, or too small. That is the only operation you can perform.</mark>

<mark style="background-color:red;">Come up with an efficient algorithm to match each child to their shoes. Give the time complexity of your algorithm in terms of the number of children.</mark>

Solution: This is a classic QuickSort problem, often presented in terms of nuts-and-bolts (instead of kids). The basic solution is to choose a random pair of shoes (e.g., the red Reeboks), and use it to partition the kids into “bigger” and “smaller” groups. Along the way, you find one kid (“Alex”) for whom the red Reeboks fit. Now, use Alex to partition the shoes into two piles: those that are too big for Alex, and those that are too small. Match the big shoes to the kids with big feet, the small shoes to the kids with small feet, and recurse on the two piles. If you choose the “pivot” shoes at random, you will get exactly the QuickSort recurrence, which results in a runtime of $$O(n \log n)$$ where n is the number of children.

## Counting Sort

Consider an array of $$n$$ integers between 0 and $$M$$ where $$M$$ is a small integer ($$n > M$$). What is the most efficient way to sort it?

1. Go through the array once, counting how many of each element you have, and store this in an array (say, `count`)
2. Then create a new result array of length $$n$$.
3. Starting from index 0 and $$i = 0$$, put $$i$$ at `result[index]`. Increment index and decrement `count[i]`. If `count[i] == 0`, increment $$i$$ until you find the next non-zero `count[i]`. Repeat till `index == n - 1`.

Running time: $$O(M + n)$$

Space complexity: $$O(M)$$ (You can avoid creating a new result by simply overwriting in the original array, but you cannot avoid creating the histogram-like counting array)

Observe that this is a non-comparison based sorting algorithm (does not perform any comparison between elements) and therefore, it is okay for it to be linear in $$M$$ (Since we already know that the minimum number of comparisons required to sort an array is $$nlogn$$.)

## Radix Sort

Before exploring radix sort, let us consider a simpler problem:

Consider an array consisting of 0s and 1s, what is the most efficient way to sort it?

We can do this using `QuickSort` partitioning with 2 pointers, one at each end. The 0-pointer will advance to the right up until it finds the first 1; the 1-pointer will move left until it finds the first 0. Then if the 0-pointer is on the left side of the 1-pointer, the elements are swapped. Continue until the 2 pointers cross each other. This takes $$O(n)$$ since the array is scanned exactly once.

Now, consider the following algorithm for sorting integers represented in binary (radix sort):

First use the in-place algorithm described above to sort by the most significant bit. Once this is done, you have divided the array into 2 parts: the first part contains all the integers that begin with 0 and the second part contains all the integers that begin with 1. That is, all the elements of the (binary) form ‘0xxxxxx’ come before all the elements of the (binary) form ‘1xxxxxx’.

Now, sort the 2 parts using the same algorithm, but using the second most significant bit instead. And then, sort each of those parts using the 3rd bit etc.

Assume that each integer is 64 bits, what is the running time? When is it faster than `QuickSort`?

This algorithm makes 64 total passes through the entire array, i.e., each element is visited 64 times (once for each bit). So, it takes about $$64n$$ steps. Each level takes $$O(n)$$ to be sorted, and we repeat this for each bit, making the recursion at most 64 level deep.

`RadixSort` will be faster than `QuickSort` when $$64n < nlogn$$. In other words, $$n > 2^{64}$$, which is quite large.

#### Optimize?

We can divide each of the 64 bits into 8 chunks of 8 bits ech. Then, we can use counting sort to do the sorting of all the elements based on the each element’s first 8 bits. This only takes $$O(n)$$. Now the recursion goes 8 levels deep. So, for $$n > 2^8$$, this will be faster than `QuickSort`

Steps:

1. Convert each integer into its binary representation
2. Create a counting array of size $$2^8 - 1 = 255$$.
3. Based on the first 8 bits of each element, use `CountingSort` to sort the elements.
4. Sort the 2 parts using the next 8 bits and so on

This takes up space during counting sort and so it is not in-place.


# Order Statistics

Find the kth smallest element in an unsorted array

Let length of the array be $$n$$ and the number of queries performed be $$m$$

Naive approaches:

1. Sort the array in $$O(n\log n)$$ time. Answer queries in $$O(1)$$ time. Total running time: $$O(n\log n + m)$$. Good when the there is a large number of queries, bad when only 1 or 2 queries are being performed (because then you’re over-computing stuff you’re not going to use)
2. Keep the array unsorted and run QuickSelect for each query. QuickSelect takes $$O(n)$$ time. So, total running time: $$O(nm)$$. Good when only a few number of queries need to be performed.

## QuickSelect

**Aim: Given an unsorted array, find the** $$k^{th}$$ **smallest element**

`QuickSelect` is a randomised algorithm - its an adaptation of `QuickSort` that solves the order statistics problem.

The expected running time of `QuickSelect` is $$O(n)$$ but it can take $$O(n^2)$$ in the worst case (if the choice of pivot is bad).

```java
QuickSelect(A[1...n], n,k):
	if (n == 1) return A[1];
	else:
		// Choose a random pivot index pIndex
		p = partition(A[1..n], n, pIndex);
		if (k == p) return A[p];
		else if (k < p) return QuickSelect(A[1...p-1], k)
		else if (k > p) return QuickSelect(A[p+1...n], k - p) // find the k - p th element from the remaining elements since you 
		// eliminated the smallest p elements
```

### Complexity Analysis

`QuickSelect` is a randomised algorithm and so its running time is a random variable. But we can find the expected running time. On average, we expect our pivot to be somwhere in the middle (such that it divides the array into 2 portions - even if it divides the array into 1/10 and 9/10, we can be confident with high probability that the pivot will be good. We will analyse a paranoid version of `QuickSelect` in which we keep repeating the selection of pivot and partitioning until we dont get a good pivot.

Let us assume that our good pivot divides the array into $$\dfrac{1}{10}$$ and $$\dfrac{9}{10}$$.

Then, $$E\[T(n)] \leq E\[T(9n/10)] + E[#partitions](https://cs2040s.devanshshah.dev/n)$$.

As we have shown in the complexity analysis for `QuickSort`, the number of times we need to partition to find a good pivot is less than 2. So, $$E\[T(n)] \leq E\[T(9n/10)] + 2n$$.

Solving this recurrence relation,

$$
\begin{equation\*} \begin{split} E\[T(n)] &\leq E[#partitions](https://cs2040s.devanshshah.dev/n) + E\[T(9n/10)] \ & \leq 2n + E\[T(9n/10)] \ & \leq 2n + 2n(9/10) + (9/10)E\[T(81n/100)] \ & \leq 2n + \dfrac{9}{10}2n + \left(\dfrac{9}{10}\right)^22n + \dots \ & \leq 2n \left( \dfrac{9}{10} + \left(\dfrac{9}{10}\right)^2 +\dots \right) \ & \leq O(n) \end{split} \end{equation\*}
$$

### Tree-Based Solution

Use a balanced tree for dynamic order statistics (dynamic simply means that you can insert and delete elements too)!

Whenever you augment a tree to solve a problem, think about the following:

1. Will my invariant/data be maintained in order during insertion/deletion/rotation? If not, how can I ensure that it is maintained? Does this make the operations too expensive? (Anything more than $$O(logn)$$ is considered expensive for a tree)
2. Is the property that I am trying to store local? (that is, does it only depend on the node’s children and/or parent? Or do I need to look at every other node in the tree?)

Local properties are great! Because they take $$O(1)$$ to compute and are easily maintainable during rotations.

We augment the AVL tree data structure to solve this problem - what extra information can we store at each node to help us?

**We will store the rank in every node** (the rank is the position of the element in the sorted array)

For example,

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fo5xkqFchSWJSdRfRbmV0%2FScreenshot_2022%2003%2003_at_9.01.19_AM.png?alt=media" alt=""><figcaption></figcaption></figure>

Then, if we are searching for an element $$k$$ and we are at the root node, when $$k < node.rank$$, we search in the left subtree. Else if $$k > node.rank$$, we search in the right subtree.

Bu there’s a problem with this approach - insertion requires the rank of **all** nodes to be updated accordingly - making it $$O(n)$$ operation. We want to do better than that! It is too expensive to store the rank at every node (rank of a node is not a local property!)

**Idea: Store the size of left and right subtree at each node**

We define weight of a node to be the size of the tree rooted at that node. It should be apparent that the weight of a leaf node is 1 and the weight of any other node is the sum of the weights of its children + 1, i.e., $$w(v) = w(v.left) + w(v.right) + 1 ; \ w(leaf) = 1$$.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FhZ48f3WS6jjoTijIaooT%2FScreenshot_2022%2003%2003_at_9.06.57_AM.png?alt=media" alt=""><figcaption></figcaption></figure>

Then, for insertion, we only need to update the weights on the root-to-leaf path. Hence, it becomes $$O(logn)$$. Similarly for deletion, we only need to update the wights of the nodes on the root-to-leaf path and so it is also $$O(logn)$$.

```java
select(k,v) // intially called with v = root
	rank = v.left.weight + 1
	if (k == rank) return v
	else if (k < rank) return select(k, v.left)
	else if (k > rank) return select(k - rank, v.right) // you eliminated k - rank nodes already
```

We define the `rank` of a node to be its position in the sorted array. It is the inverse function of `select`. That is, `rank(select(k)) = k`.

`rank(v)` computes the rank of the node `v`.

```java
rank(node)
	rank = node.left.weight + 1; 
	while (node != null) do
		if node is left child then do nothing // nothing becomes before you since you are the left child
		else if node is right child then
			// add the number of nodes that came before you (basically add the weight of your left sibling and 1 for your parent)
			rank += node.parent.left.weight + 1; 
		node = node.parent; 
return rank;
```

A key invariant for the above `rank` algorithm is that after every iteration, the rank is equal to the its rank in the subtree rooted at `node`. At the end of the program, the rank would be equal to the rank of the subtree rooted at the `root`, which proves the correctness of our algorithm. In every node, the rank is either the same (if no nodes have come before me), or the rank is increased by the number of nodes that came before me)

Are we done?? No! we still need to show how we can maintain the weights during AVL rotations.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FsmrF7dCVpbqfyktr2yBl%2FScreenshot_2022%2003%2003_at_9.16.09_AM.png?alt=media" alt=""><figcaption></figcaption></figure>

How long does it take to update the weights during rotation? $$O(1)$$ !!! Just look at the weights of the new children.

```java
rightRotate(v)
	w = v.left
	v.left = w.right
	w.weight = v.weight // since w is now the root
	w.right = v
	v.weight = v.left.weight + v.right.weight + 1 // O(1) time :) 
```

Similarly, for `leftRotate(v)` too.

Notice how we followed the basic methodology for problem-solving here: Start with a naive basic implementation (usually just an array or list or tree - in fact, a tree an be represented by a (nested) list too).

Basic methodology:

1. Choose underlying data structure (tree, hash table, linked list, stack, etc.)
2. Determine additional info needed.
3. Verify that the additional info can be maintained as the data structure is modified. (subject to insert/delete/rotation/etc.)
4. Develop new operations using the new info. (select, rank, etc.)


# Interval Searching

Given an array of unsorted and possibly overlapping intervals, and a point, find an interval containing the point.

An example of such a problem is cell tower coverage - given a location of where I am on the highway, and a list of cell-towers and their corresponding coverages, find a cell tower that covers my location.

### Idea 1

If there is only one query being made (i.e., only point to check for), there is no need to do any work in making a data structure to solve this problem - just use linear traversal and return the answer in $$O(n)$$ time. But if there are $$m$$ queries being made (and $$m$$ is large), then we need to do better than $$O(nm)$$.

### Idea 2

How about if we just have a long array (equal to the size of the maximum end point of an interval) and store which cell-tower covers which intervals?

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FufQ5wkh4otJzMcgD15Sq%2FScreenshot_2022%2003%2003_at_9.36.00_AM.png?alt=media" alt=""><figcaption></figcaption></figure>

This takes up a lot of space and moreover, insertion and deletion of intervals can take $$O(n)$$.

### Idea 3 :bulb:

We use a dynamic data structure to solve this problem! (Dynamic simply means that we can insert and delete intervals from the structure too!)

It should be no surprise that our basic underlying data structure is a balanced AVL tree. We augment it as follows:

Each node is an interval. The tree itself is sorted by the **left endpoint**.

Notice that if we just store the intervals sorted by left endpoint, it doesn’t really help us at all. We need some more information to decide whether to look in the left subtree or right subtree of any node. How do we do that?

**Key Insight: Store the maximum endpoint (right) in the subtree at the node too!!!**

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FGI7AM6SlzQwzL2b7K0Jo%2FScreenshot_2022%2003%2003_at_9.40.36_AM.png?alt=media" alt=""><figcaption></figcaption></figure>

The algorithm is as follows:

Observe that even though we keep the tree sorted by the left endpoint, we never really use this in the algorithm. But this is crucial to the correctness of the algorithm.

#### Proof of correctness

```java
searchInterval(x)
	c = root;
	while (c != null and x not in c.interval) do
		if (c.left == null) c = c.right;
		else if (x > c.left.max) c = c.right;
		else c = c.left
	return (x in c) ? c : NOT_FOUND;
```

The logic of the algorithm is as follows: if `x` is in the interval, return the interval. Otherwise, if `x` is larger than the maximum endpoint in the subtree rooted at the left child of interval, then we can be sure that it is not in the left subtree. So, we search the right subtree. However, if `x` is less than the maximum of the left child, we search there.

**Claim 1**: If we ever go right, we are sure that there is no interval that contains the point `x` in the left subtree. (this is pretty obvious since `x` is greater than the maximum of any interval in the left subtree)

**Claim 2**: If we go left, and we do not find any interval overlapping with the point, then we can be sure that there is no interval containing the point even in the right subtree (and so we did not make any mistake by choosing to go to the left)

This is because of the fact that the tree is sorted by the left endpoint! (Take some examples to convince yourself)

**Conclusion**: the `searchInterval` finds an overlapping interval if it exists.

It should be pretty clear that the running time of the algorithm is $$O(\log n)$$ (since you are traversing the root-to-leaf path of a balanced binary tree). Insertions and deletions also take $$O(\log n)$$ and we need to update the max values of the nodes on the root-to-leaf path.

#### How to maintain the max during rotation?

This is really easy and is left an exercise for the reader (hint: you can do it in $$O( 1)$$ as shown below).

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FFix8YCeQzjSt2ByUYEEd%2FScreenshot_2022%2003%2003_at_10.01.03_AM.png?alt=media" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FFGurmm2jdpnvVPNsFxyA%2FScreenshot_2022%2003%2003_at_10.01.25_AM.png?alt=media" alt=""><figcaption></figcaption></figure>

#### What if you wanted to find all the intervals that contained a point?

1. Find an interval, add it to a list, delete from the tree.
2. Repeat step 1 until no more correct intervals remain.
3. Add the intervals back to the tree (because no one told us we could go ahead and delete them in the first place)

If there are $$k$$ intervals that contain a point, the running time would be $$O(klogn)$$ (since our `searchInterval` algorithm would run $$k + 1$$ times (we only find out we are done in the last time it runs because it would return null)


# Orthogonal Range Queries

(1D-Version) Given an array of points and an interval, find the points (not just the number of points) that are contained the interval.

Example: Find the names of everyone aged between 22 and 27 (important in databases)

Firstly, you should be able to see how this is different from interval searching although in both the problems, there are points and intervals.

Moreover, this can be extended to d-dimensions (e.g. in the 2-D case, we would ask “find the points that lie within a given rectangle”, thus giving the name “orthogonal” range queries) but we only discuss the 1-D case here.

### Strategy

1. Use a Binary Search Tree in which all the nodes are sorted by the property we are going to query by. (Decide the underlying data structure)
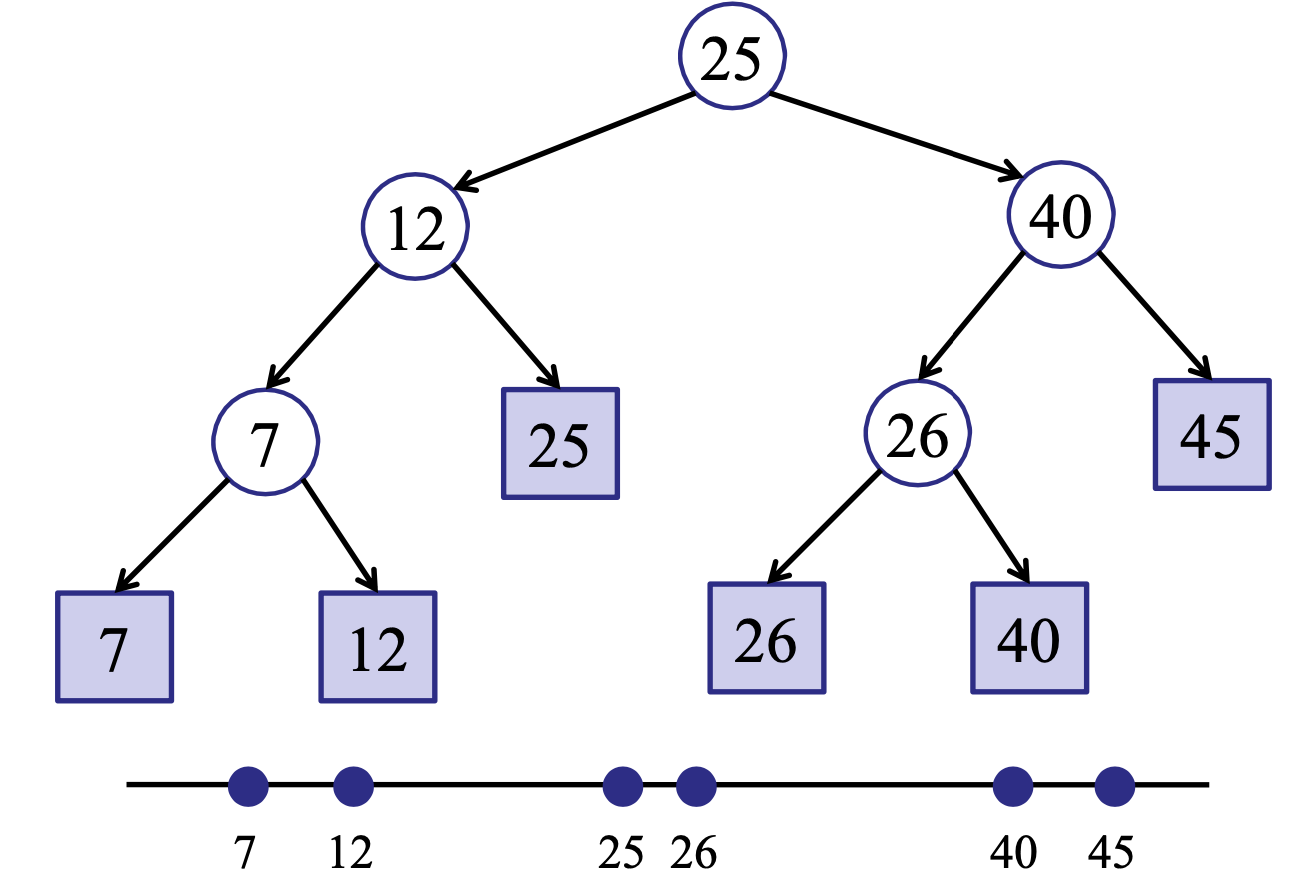
2. Store all the points in the **leaves** of the tree. (Internal nodes only store copies of these) (**Invariant**: The tree would still have the BST property)
3. Each internal node `v` stores the **max of any leaf in its left subtree** (this is quite a common strategy to help you determine whether to go left or go right). (Augment the data structure to help you perform your operations)

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FVx6dhtMqq5rjDeTyLTZ4%2FScreenshot_2022%2003%2003_at_10.16.25_AM.png?alt=media" alt=""><figcaption></figcaption></figure>

### Algorithm

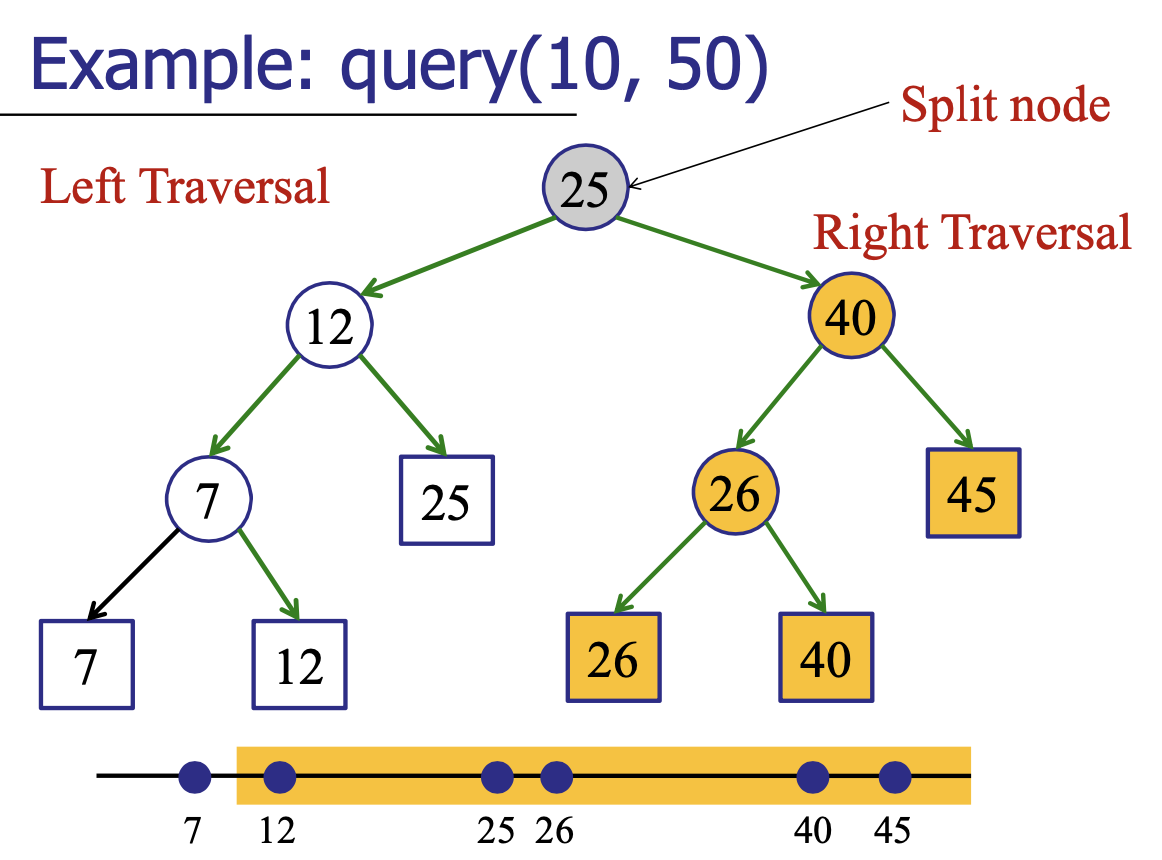
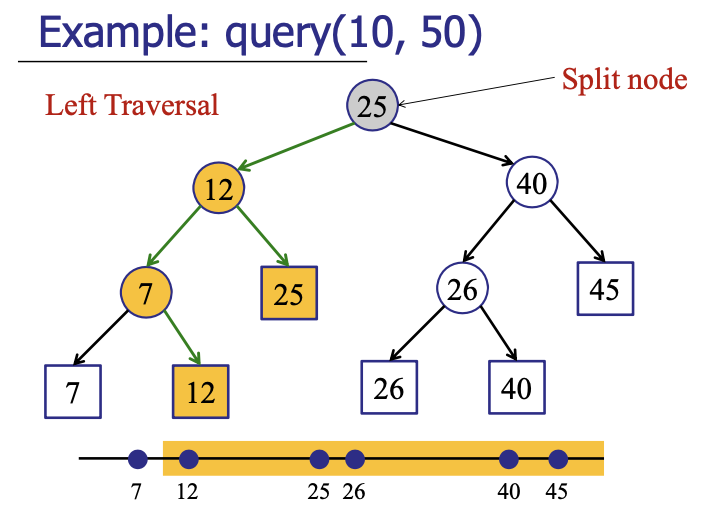
1. Find the split node (the highest node that falls between the interval bounds)
2. Perform `leftTraverasal`
3. Perform `rightTraversal`

Example of a left and right traversal:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FRC9ui77Wrz0s7KurfW5N%2FScreenshot_2022%2003%2003_at_10.23.56_AM.png?alt=media" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fy03vZaNRxQRENHf8dZ1i%2FScreenshot_2022%2003%2003_at_10.24.27_AM.png?alt=media" alt=""><figcaption></figcaption></figure>

### Pseudocode

```java
findSplit(low, high)
	v = root;
	done = false;
	while !done {
		if (high <= v.key) v = v.left;
		else if (low > v.key) v = v.right;
		else (done = true)
	}
	return v;
```

```java
rightTraversal(v, low, high)
	if (v.key <= high)
		allLeafTraversal(v.left);              // basically do an in order traversal of all the leaves in that subtree
		rightTraversal(v.right, low, high);
	}
	else {
		rightTraversal(v.left, low, high);
	}
```

```java
leftTraversal(v, low, high)
	if (low <= v.key)
		allLeafTraversal(v.right); // basically do an in order traversal of all the leaves in that subtree
		leftTraversal(v.left, low, high);
	}
	else {
		leftTraversal(v.right, low, high);
	}
```

### Running Time Analysis

1. Finding split node: $$O(\log n)$$
2. `leftTraversal`
   1. Doing all leaf traversal takes $$O(k)$$ where k is the number of leaves in the subtree.
   2. Then, `leftTraversal` is recursively called (at most $$O(\log n)$$ times)
3. `rightTraversal` is identical (in running time) to `leftTraversal`

So, query time complexity is $$O(k + \log n)$$ where $$k$$ is the number of points found.

(Preprocessing) Building the entire tree takes $$O(n\log n)$$ time. - Run `QuickSelect` to find the median, then run `QuickSelect` on the two halves and so on.. at each level, it takes $$O(n)$$ time to run the `QuickSelect`.

Insertion, deletion takes $$O(\log n)$$ time.

Total space complexity $$O(n)$$ (Number of nodes in a tree $$\leq$$ $$2 \times$$ number of leaves in the tree) (easy to prove since $$1 + 2 + 4 + \dots + 2^n = 2^{n+1} - 1$$ and at every level of the tree, the maximum number of possible nodes double).


# Random Permutation Generation

Given an array A of  items, come up with an algorithm that produces a random permutation of A on every run

### Approach 1

Our main objective is here is to generate permutations with good randomness. For an array with $$n$$ items, we need to ensure every one of the $$n!$$ permutations will be producible by our algorithm with probability exactly $$1/n!$$.

Does the following algorithm work?

```java
for (i from 1 to n) do
	j = random(1,n)
	swap(A, i, j)
```

No. The above algorithm does not ensure that each permutation of `A` has equal probability of being generated. This can be proved as follows:

For each iteration, there are $$n$$ possible outcomes of $$j$$. So, there are a total of $$n^n$$ outcomes that can be generated (obviously many of them will give rise to the same permutation). But the crucial point to note is that it is (in general) not possible to divide each of the $$n^n$$ outcomes equally among the $$n!$$ permutations. In particular, $$n^n/n!$$ is not necessarily an integer (eg. $$n = 3$$). So, there is no way that each permutation has equal chance of being chosen).

### Approach 2

What about the algorithm below? (Note that once we mark an element as picked, we don’t select it again)

```java
randomPermutation(A)
	create new array B[] of size = A.length;
	for (i = 0 to i = n-1)
		do
			choose j = random(1,n)
		while A[j] is picked // keep trying to find a j such that A[j] has not been picked yet
		// once you have found your A[j],
		B[i] = A[j]
		mark A[j] as picked
	// for every value of i from 0 to n-1, you are essentially picking a random element from A and assigning it to B[i] 
	// you need to mark as picked to make sure that B is ultimately a permutation of A (and you have not added the same
	// element multiple times or forgotten to add some element)
```

The above algorithm is in fact "random" in the sense that each of the $$n!$$ permutations have equal chance of being generated. But there are some problems with this algorithm too:

1. Firstly, we are using an additional $$O(n)$$ space.
2. More importantly, the probability of randomly selecting a previously picked item increases as we progress, leading to more and more time spent on re-picking the random index. As $$n$$ gets very large, the probability of having to keep re-picking a random index for the last slot approaches 100%. (Think about it this way, if $$n = 1000$$ and you are at the $$999^{th}$$ iteration. You have only 1 acceptable value of $$j$$ that has not been picked yet. But you don’t know what that is and you are trying to find it randomly (trial and error). So, the expected number of iterations to find the correct $$j$$ would be: $$E(X) = 1\times \dfrac{1}{1000} + \[ 1 +E(X)] \times \dfrac{999}{1000}$$ , where $$X$$ is the number of times you need to call $$random()$$ to find the correct $$j$$ (there is a 1/1000 chance that you get it in the first try, if you don’t get it, then you are at your initial stage again and you have to try again - you haven’t even eliminated anything lol)

Solving the above would give you $$E(X) = 1000$$. In other words, it would take you $$1000$$ iterations to find the correct value of $$j$$ for the last slot. As $$n$$ gets larger, this expected number also increases!

### Best Random Permutation Algorithm

```java
for (int i = 0; i < n; i++):
	j = random(1, n-i) // pick a random element
	swap(A, j, n - i + 1); // send it to the back of the array
```

It can be shown that each permutation has exactly $$1/n!$$ probability of being generated.

**Time:** $$O(n)$$**, Space:** $$O(1)$$

#### Checking Randomness?

To show that an algorithm does not in fact generate a truly random permutation, it suffices to:

1. find a permutation that can never be generated
2. show that the number of possible choices/decisions made by the algorithms is not a multiple of $$n!$$ and so each permutation cannot be equally likely

### Application Question

Assume that we use a truly random permutation algorithm for peer-checking of homework. That is, given an array of distinct student names `A`, the algorithm generates a permutation of `A` (say `B`). Then, student `A[i]` is told to grade student `B[i]`'s homework. If the size of the class is 600, what is the **expected** number of students who have to grade their own homework?

Answer: Only 1 !!! (Moreover, this does not depend on the size of the class)

The question is identical to asking: “After generating a permutation, what is the probability that a specific element remains in its exact spot?”

Each element has $$1/n$$ probability of being assigned to any position. In particular, it has $$1/n$$ probability of being assigned to its original spot. (In other words, the probability that a student named John gets to grade his own homework is $$1/n$$ —> which depends on the class size)

Alternatively, number of permutations of the remaining $$n-1$$ elements, if we keep one of them fixed in its place: $$(n-1)!$$. So, the probability that the element stays in its spot is $$\dfrac{(n-1)!}{n!} = \dfrac{1}{n}$$.

Since there are $$n$$ students, the expected number of elements which are at their original spot = $$n \times 1/n = 1$$

It is interesting that for any student, the probability that they get to grade their own homework is inversely proportional to the total class size but the expected number of such students is independent of the class size.

Alternatively, we can solve it without thinking of permutations at all (and simply using linearity of expectation). Suppose we have $$n$$ students. Then, for any student $$x\_i$$, the probability that she has to grade her own homework is $$\frac{1}{n}$$, and this probability is the same for any student.

Let $$I\_i$$ be an indicator variable that is 1 iff student $$i$$ grades her own homework. Then, we want to calculate $$E\[I] = E\[\sum\_i I\_i]$$.

By linearity (recall that this applies even though the variables are not independent!), we have:

$$
E\[I] = \sum\_{i=1}^n E\[I\_i] = \sum\_{i=1}^n  \frac{1}{n}\cdot 1 = 1
$$

and so, we get the same answer as before.


# Disjoint Set Union

Also known as Union Find Disjoint Set

**Problem:** Given some elements, a user can perform two types of operations: `Union(u, v)` (in which case the set containing $$u$$ and $$v$$ are merged) and `Find(u, v)` (in which case we need to determine whether $$u$$ and $$v$$ are in the same set). Our aim is to make both operations as fast as possible.

This is a problem on dynamic connectivity. Union means that the two objects are connected and Find asks us to check whether there is a path connecting the two objects.

## Naive Solution

Model each object as a node. Each edge represents connectedness. `Union` will take $$O(1)$$ since you just need to connect the two nodes. `Find` will take $$O(V+E)$$ since you need to check if there is a path between the nodes. In this case, a connected component will represent a maximal set of mutually connected objects (obviously the edges are undirected).

But we can make `Find` faster?

## QuickFind

Since the number of objects is fixed, we can use an array to store the componentId to which the object belongs. To convert an object to an integer (to be used in an array index) we can use a HashMap with open addressing (since we absolutely don’t want collisions - otherwise their indices will get messed up).

So `array[i]` stores the component identifier of $$i$$. We can let the component identifier be the object with the lowest id in the set.

Then, two objects are connected if they have the same component identifier. Hence, `Find` becomes $$O(1).$$ But what about `Union`?

Now, to `Union` two components, we need to scan the entire array and change all the componentId of one set to match the other. This takes $$O(n)$$.

Pseudocode:

```java
find(int p, int q)
	return(componentId[p] == componentId[q]);

union(int p, int q) updateComponent = componentId[q]
	for (int i=0; i<componentId.length; i++)
		if (componentId[i] == updateComponent)
			componentId[i] = componentId[p];
```

If you think of a connected component as being in the shape of a tree, each node in the tree stores the root of the tree to uniquely identify the tree. So two nodes are in the same set (tree) if they have the same root.

## QuickUnion

We use the same idea as before but instead of storing the root of the tree, we only store the parent of each object. As before, two objects are connected if they are part of the same tree. For example,

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FCj5As6yAwKJZCIgkJRL9%2FScreenshot_2022%2004%2001_at_10.27.28_PM.png?alt=media" alt=""><figcaption></figcaption></figure>

```java
find(int p, int q):
	while (parent[p] != p) p = parent[p]; // traverse up till you reach the root of tree containing p
	while (parent[q] != q) q = parent[q]; // traverse up till you reach the root of tree containing q
	return (p == q); // p and q are connected if they are in the same tree -> same root

union(int p, int q)
	while (parent[p] != p) p = parent[p]; // find p's root
	while (parent[q] != q) q = parent[q]; // find q's root
	parent[p] = q; // let the root of p's tree point to the root of q's tree (if you directly connect p to q, p will have multiple parents)
```

The problem with this implementation is that the intuition is correct but there is no guarantee that our tree has height $$O(\log n)$$. Both `Find` and `Union` rely on travelling up the entire height of the tree to find the root and this may take at most $$O(n)$$. (It shouldn’t be called QuickUnion since it can’t even perform union quickly lol)

Notice that this tree need not be a binary tree (a node can have many chidren).

We need to make some optimisations to make sure our tree has height $$O(logn)$$ and the tree is as flat as possible.

## Optimisations

### 1. Weighted Union (Rank Heuristic)

In deciding which root to make the root (during `Union`), we can ensure that our trees are more balanced by making the smaller tree a child of the larger tree’s root. We decide which tree becomes the “parent” using their weights.

```java
union(int p, int q)
	while (parent[p] !=p) p = parent[p]; 
	while (parent[q] !=q) q = parent[q]; 
	if (size[p] > size[q] {
		parent[q] = p; // Link q to p 
		size[p] = size[p] + size[q];
	} else {
		parent[p] = q; // Link p to q 
		size[q] = size[p] + size[q];
  }
```

Okay, this may give us a slight improvement over the previous method but how do we know that our heights are now $$O(logn)$$?

Well, it is easy to see that the height of our tree only increases when another tree having equal or more weight is added to our tree. If we add a smaller tree as a child of our tree, the height of our tree will not increase. In other words, **height only increases when total size doubles.**

**Claim: A tree of height** $$k$$ **has at size at least** $$2^k$$**. Or, the height of a tree of size** $$n$$ **is at most** $$logn$$

Proof by induction:

How do you get a tree of height $$k$$? You make a tree of height $$k - 1$$ the child of another tree. By induction hypothesis, this tree of height $$k - 1$$ has size at least $$2^{k-1}$$. Moreover, since you are making it a child of the other tree rather than the other way around, we know that the size of the other tree is greater than $$2^{k-1}$$ (by our union-weight rule). So, the total weight of our final resultant tree of height $$k$$ is $$\geq 2^{k -1} + 2^{k-1} = 2^k$$. Hence, proved.

Now since both our find and union operations just traverse the tree once, they run in $$O(logn)$$ time.

Note that we could also do union-by-rank (instead of union-by-weight) in which case $$rank = log(size)$$. We could have also done union-by-height. In fact, the important property is that weight/rank/size/height of a subtree does not change except at root (so we only need to update the root when we union) and moreover, the weight/rank/size/height only increases when tree size doubles.

### 2. Path Compression

We have already achieved $$O(logn)$$ for find and union. But can we do any better? It turns out we can!

After finding the root during some `find` or `union` operation, we can set the parent of each traversed node to the root (while we are traversing the nodes from the leaf-to-root path, we can just store these nodes in an array and once we find the root, assign the root to be the parent of all these nodes). Essentially, now we are trying to make the height of the tree as small as possible by “flattening” or “compressing” the path between the node and the root.

```java
findRoot(int p) {
	root = p;
	while (parent[root] != root) root = parent[root]; // we found the root
		while (parent[p] != p) {
			temp = parent[p]; // before assigning the root to be the parent, we need to store th current parent to traverse the path lol
			parent[p] = root; 
			p = temp; // now make the parent of each node the root
		}
  return root;
}
```

It turns out that for path compression to work well, we don’t even need to assign the root to be the parent of every traversed node. Even if we make every node in the path point to its grandparent, it works just as well!

```java
findRoot(int p) {
	root = p;
	while (parent[root] != root) {
		parent[root] = parent[parent[root]]; 
		root = parent[root];
	}
  return root;
}
```

Tarjan (1975) gives an upper bound for the running time of Union-Find with weight union and path compression

**Theorem (Tarjan, 1975): Starting from empty, any sequence of** $$m$$ **union/find operations on** $$m$$ **object takes** $$O(n + m\alpha(m,n))$$ **time.**

Here, $$\alpha$$ is the inverse ackermann function (in our universe, it is always less than 5). BUT the inverse ackermann is not a constant, i.e., $$\alpha \neq O(1)$$.

**Remember that** $$O(\alpha)$$ **is the AMORTIZED cost of an operation in UFDS with path compression and weighted union - NOT the worst case of an operation.**

Can we do better than this? Nope! Tarjan also proved that it is impossible to achieve linear time (although we did get really close to linear time!)

***

## Questions

<mark style="background-color:red;">What is the</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">**worst-case running**</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">time of the find operation in Union-Find with path compression (but no weighted union)?</mark>

Ans: $$O(n)$$ (In the worst case, the tree is completely unbalanced - a straight line). Path compression won’t help if you keep calling union on the root of the tree and adding the entire tree as a subtree of that one node.

<mark style="background-color:red;">What is the</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">**worst case**</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">running time for a</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">`Find`</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">operation on the UFDS that is using both weighted union and path compression. Assume there are at most</mark> $$n$$ <mark style="background-color:red;">disjoint sets, initially each element is in its own set.</mark>

Ans: $$O(logn)$$. Think of what would happen if you kept calling `Union` on the roots of the distinct trees - there would be no path compression performed! Path compression ensures that once you have travelled a particular root-to-leaf path entirely, you don’t need to travel it again. But, you at least need to do it once in order to do the path compression in the first plae. More generally, if a `Find` or `Union` operation has not been called on $$u$$ or $$v$$ or any of their anccestors (except the root), then there is no effective “path compression”. So, the worst case would still be $$O(logn)$$ but notice that after you call `Find(u,v)`, all subsequent calls of `Find` to any of $$u's$$ parents or $$v's$$ parents would take $$O(1)$$ since they are directly connected to the root. (Assuming you don’t perform more `Union` operations in between).

In short, when you use weighted union, you guarantee that the size of the subtree is always $$O(logn)$$ (since you use it for **every** call to `Union`) and so, `Union` and `Find` cannot take more than that. But path compression has its limitations and can be side-stepped by an adversarial input that ensures no effective path compression is taking place at all.

<mark style="background-color:red;">Here’s another algorithm for Union-Find based on a linked list. Each set is represented by a linked list of objects, and each object is labelled (e.g., in a hash table) with a set identifier that identifies which set it is in. Also, keep track of the size of each set (e.g., using a hash table). Whenever two sets are merged, relabel the objects in the smaller set and merge the linked lists. What is the running time for performing m Union and Find operations, if there are initially n objects each in their own set? More precisely, there is: (i) an array</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">`id`</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">where</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">`id[j]`</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">is the set identifier for object</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">`j`</mark><mark style="background-color:red;">; (ii) an array size where</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">`size[k]`</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">is the size of the set with identifier</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">`k`</mark><mark style="background-color:red;">; (iii) an array list where</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">`list[k]`</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">is a linked list containing all the objects in set</mark> <mark style="background-color:red;"></mark><mark style="background-color:red;">`k`</mark><mark style="background-color:red;">.</mark>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FoZBB8r3GX7KdtTABPA3u%2FScreenshot_2022%2004%2015_at_6.18.20_PM.png?alt=media" alt=""><figcaption></figcaption></figure>

<mark style="color:red;">Assume for the purpose of this problem that you can append one linked list on to another in O(1) time.</mark>

Find operations obviously cost $$O(1)$$. For $$m$$ union operations, the cost is $$m log n$$. The only expensive part is relabelling the objects in `list[k2]`. And notice that, just like in Weighted Union, each time we union two sets, the size of the smaller set at least doubles. So each object can be relabelled at most logn times (as we can double the size of a set at most logn times). Note that since there are $$m$$ union operations, the biggest set after those operations is of size $$O(m)$$, and as each object in that set was updated at most $$logn$$ times, the total cost is $$m log n$$. Of course, notice that any one operation can be expensive (each union operation have different costs). For example, the last union operation might be combining two sets of size $$m/2$$ and hence have cost $$m$$, while the first union operation would have a cost of $$O(1)$$. The appending of one linked list to the end of another is pretty easily done in O(1) through manipulation of the head and tail pointers.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Ftnhnx61iuUqLyRFMS17r%2FScreenshot_2022%2004%2024_at_9.20.41_PM.png?alt=media" alt=""><figcaption></figcaption></figure>

## Summary

The table below shows the running time of each operation of find and union:

Note: actually for path compression, the first time you run `find` or `union` on the node, it is possible that it takes $$O(n)$$ since you are not ensuring balanced binary tree.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FhLO3SXUhW146oIpYL5Dg%2FScreenshot_2022%2004%2001_at_10.51.46_PM.png?alt=media" alt=""><figcaption></figcaption></figure>

## Applications

* In a maze, we can find whether 2 locations are connected using the find operation
* In a game, we can check whether we can get from one state to another
* We can find the least-common-ancestor in a tree
* In a graph, we can find connected components (e.g. largest connected component in graph with common factor)


# Binary Search Tree

**Aim:** Implementing a dynamic data structure that supports searching in $$O(\log n)$$ time, inserting in $$O(\log n)$$ time, and deleting in $$O(\log n)$$ time.

## Option 1: Use a sorted array

Then searching takes $$O(\log n)$$ time but insertion takes $$O(n)$$ time. (Since, you need to move all the other elements by 1 space)

## Implementation Idea: Tree!

Recall that a tree is a circuit free and connected graph. In most trees, there is a root and edges are directed away from the root.

A binary tree is a tree in which every node has less than or equal to 2 children. We denote the two children of any node as `node.left` and `node.right` respectively. Every node except the root has exactly 1 parent. Non-leaf nodes are called internal nodes. That is, a node with at least 1 child is called an internal node.

So, a binary tree can be defined recursively as being either empty or a node pointing to 2 binary trees.

### BST property

The key BST property that allows us to perform searches, insertion, and deletion in $$O(logn)$$ time is that:

**All elements in left sub-tree < key < all elements in the right sub-tree.**

Here, we do not allow duplicate elements to remain in the tree.

### Height

The height of any node is equal to 1 greater than the maximum of the heights of its two children. Leaves are assumed to have a height of 0. An empty node (null or absence of a node) is assumed to have a height of -1 (which is consistent with how we defined the height of a leaf).

`height(v) = max(height(v.left), height(v.right)) + 1` - this represents a common property of trees: often, you just need to look at the children of a node to determine the node’s value. You don’t have to search the entire tree. Thus, recursion plays a key role in trees.

Height of a binary tree is the number of edges on the longest root-to-leaf path.

### Searching for a Key

```java
public TreeNode search(int queryKey, TreeNode node) { // this is called with node = root initially
	if (queryKey < node.key) {
		if (node.left != null) return search(queryKey, node.left);
		else return null; // key is smaller than node.key but there is no smaller key in the tree.
	}
	else if (queryKey > node.key) {
		if (node.right != null) return search(queryKey, node.right);
		else return null; //  key is bigger than node.key but there is no bigger key in the tree.
	}
	else return this; // exactly one of <. > and = must be true.
```

It is clear that searching for a key takes $$O(h)$$ time where $$h = height(tree)$$.

Notice that for most of the algorithms involving trees, we will be using a recursive approach. If some criteria is satisfied, call the method on the left child, or if some other criteria is satisfied, call the method on the right child. If not, you are done. Mostly the base case is when you encounter a `null` node or a leaf node.

A property of a node is said to be local if it only depends on its children/parent.

### Inserting a new Key

```java
public void insert(int key, int value, TreeNode node) { // this is called with node = root initially
	if (key < node.key) {
		if (node.left != null) insert(key, value, node.left)
		else node.left = new TreeNode(key, value); // insert the new key as the left child of this node
	} else if (key > node.key) {
		if (node.right != null) insert(key, value, node.right)
		else node.right = new TreeNode(key, value); // insert the new key as the right child of this node
	}
	else return; // Key is already in the tree!
```

Observe that a new key is always inserted at a leaf position.

It is clear that inserting a new key takes $$O(h)$$ time where $$h = height(tree)$$. (Since at every call of insert, you move down the tree by one level)

### Analysing Complexity of BST

Worst case complexity of insertion and deletion of a node in a tree with n nodes: $$O(n)$$! This is because the height of the tree can be $$O(n)$$ in the worst case. All our algorithms depend on the height of the tree (which depends on the shape and hence, order of insertion of elements in the tree). For example, consider inserting elements in their sorted order into a tree. In this case, $$h = n$$ and we have made no improvement! Then, what’s the advantage in using a BST instead of a regular array? We’ll come back to this when we discuss the importance of being balanced.

Same keys $$eq$$ same shape! Performance depends on shape of the tree. If you insert keys in random order, you can expect the tree to be roughly balanced.

### Tree Traversal

* **In order**: left child, node, right child (When you do an in-order traversal of a tree, you get the elements in sorted order)
* **Pre-order**: node, left child, right child
* **Post-order**: left child, right child, node

All traversals take $$O(n)$$ time where $$n$$ is the number of nodes in the tree. This is because each node is “visited” exactly once.

### Finding Successor/Predecessor

BSTs are very useful in finding a successor or predecessor of a given key. Here, we only explain how to find the successor but the algorithm for finding the predecessor is very similar.

**Aim:** Given a key `key`, find the smallest key in the tree which is greater than `key`.

**Observation:** When you try to find a key that is not in the tree, you eventually reach a leaf node (say, `u`). `u` is either the predecessor or successor of the key. Verify this by trying a few examples.

**Algorithm:** There are two possibilities - the key `key` may be in the tree or it may not be in the tree.

**Case 1:** `key` not in the tree

1. Perform a search for `key` in the tree. You will eventually reach a leaf node. Say, `u`.
2. If `u.key` > `key`, the successor is `u`
3. If `u.key` < `key`, `u` is the predecessor. So, find the successor of `u`. (This falls under case 2 since we know that `u` is in the tree.) The successor of `u` is also the successor of `key`. (Proof: `u` is the predecessor of `key`. So, there is no element in the tree which lies between `u` and `key`. So, `u's` sucessor must be greater than `key`. Moreover, since it is the successor of `u`, there is no other element that is smaller than it but greater than `u`. Hence, it must also be the successor of `key`.)

**Case 2:** `key` in the tree

**Case 2a:** `key` has a right child.

1. Find the minimum element in `key.right`. (Just keep going left until you reach the leaf node or a node has no left child, which will be the minimum element). This gives the successor of `key`

**Case 2b:** `key` does not have a right child

1. Keep going to the parent of `key` until `parent.left == key`, i.e., find the lowest ancestor of `key` for which `key` lies in its left subtree. That is the successor of key.

Not every node in the graph has a predecessor/successor. In particular, the maximum element of the BST does not have a successor and the minimum element of the BST does not have a predecessor.

### Deletion

When trying to delete `node` from the tree, there are three cases:

**Case 1:** `node` has no children

Simply delete `node` in this case.

**Case 2:** `node` has 1 child

Connect the child of `node` to the parent of `node`, and then just delete `node`

**Case 3:** `node` has 2 children (The most interesting case!)

Find the successor of `node`. Swap `node` with it’s successor. Delete `node`.

**Question**: What if the successor of `node` also has 2 children? Then what can we do??

**Answer**: That is not possible if you think carefully about it. The successor of `node` cannot have a left child (when `node` itself has 2 children, the successor of `node` lies in the right subtree of `node`) because if it did, the left child of our so-called “successor” would be the actual successor of `node` instead.

Deletion also takes $$O(h)$$ time where $$h = height(tree)$$.

#### The Importance of being Balanced

Since `insert`, `delete`, `findMin`, `findMax`, `successor`, `predecessor`, `search` - all take $$O(height)$$ time, it is very crucial to try and reduce the height of the tree.

**What is the maximum possible height of a binary tree with** $$n$$ **nodes**? $$n$$ (Imagine a straight line where each node has exactly 1 child)

**What is the smallest possible height of a binary tree with** $$n$$ **nodes?** $$\Theta(logn)$$**.**

Proof: We will find the (maximum) number of nodes $$n$$ in a tree with height $$h$$ (we are trying to make the tree as compact as possible - i.e., we want a BT as close to a complete BT as possible). Note that at any depth $$d$$ of a tree, we can have at most $$2^d$$ nodes (where depth is defined as the distance from the root to the node). Observe that the maximum of the depths of all leaves will be equal to the height $$h$$ of the tree. Then, the number of nodes in a tree with height $$h$$ is:

$$
n \leq 1 + 2 + 4 + \dots + 2^h < 2^{h+1}
$$

So, a tree with height $$h$$ has **at most** $$2^{h+1}$$ nodes. In other words, $$h + 1 \geq log\_2(n)$$ or, the minimum height of a tree with $$n$$ nodes is $$log\_2(n) - 1$$. So, we cannot do better than $$O(\log n)$$.

### Balanced Tree

We try to minimize the height of the tree so that our algorithms run faster. We will show how to do this later on using **AVL trees.**

A tree is said to be balanced if its height has $$O(\log n)$$.

#### How to get a Balanced Tree?

1. Define a good property (invariant) of a tree.
2. Show that if the invariant holds, then the tree is balanced.
3. After every insertion/deletion, make sure the invariant still holds. If not, fix it.

## AVL Trees (Adelson-Velskii & Landis 1962)

1. Augment the tree

   1. Store the height of the node at every node. (Or, you can simply store the difference of the left child’s height and right child’s height)
   2. On insertion and deletion, update the height recursively. (You only need to update the heights along the root-to-leaf path along which the insertion or deletion took place so it takes $$O(height)$$ time. This is crucial: if you had to update the heights of every other node when performing insertion/deletion, it would take $$O(n)$$, which is very inefficient).

   ```java
   insert(x)
   	if (x < key) left.insert(x)
   	else right.insert(x)
   	height = max(left.height, right.height) + 1
   ```
2. Define the invariant
   1. **A node `v` is height-balanced if:** $$|v.left.height - v.right.height| \leq 1$$ (That is, the difference in heights of a node’s children should not exceed 1)
   2. A binary search tree is height-balanced if **every** node in the tree is height-balanced.
3. Prove that a height-balanced tree is also a balanced tree. (This is not trivial or obvious in any way). Recall that balanced $$\implies h=O(\log n)$$
   1. **Claim**: A height-balanced tree with $$n$$ nodes has at most height $$h < 2logn$$ (which would mean $$h = O(\log n)$$ and hence, balanced)
   2. This is equivalent to proving that a height-balanced tree with height $$h$$ has at least $$n > 2^{h/2}$$ nodes.
   3. Let $$n\_h$$ be the minimum number of nodes in a height-balanced tree of height $$h$$.
   4. If a node has a height $$h$$, at least one of its children must have a height of $$h -1$$ (only then it can be of height $$h$$). Since we are trying to show the minimum number of nodes is greater than $$2^{h/2}$$, we consider the smallest possible height-balanced tree of height $$h$$. This would be the case when one of the node’s children is of height $$h - 1$$ and the other of $$h - 2$$ (to minimize the number of nodes). Then, $$n\_h \geq 1 + n\_{h-1} + n\_{h-2}$$ (Minimum number of nodes in a tree rooted at `node` $$\geq$$ `node` itself + Minimum number of nodes in its left and right children). So, we need to solve the reccurence relation,
   5. $$n\_h \geq 1 + n\_{h-1} + n\_{h-2} \geq 2\*n\_{h-2}$$ (Obviously, $$n\_{h-1} \geq n\_{h-2}$$)
   6. This becomes much easier to solve now, $$n\_h \geq 2n\_{h-2} \geq 4n\_{h - 4} \dots \geq 2^{h/2}n\_0$$ (where $$n\_0 = 1$$, i.e., a tree of height 0 can have at most 1 node.)
   7. Therefore, $$n\_h \geq 2^{h/2}$$.
   8. Hence, $$h \leq 2logn$$
   9. (In fact, it is possible to show that $$h \approx 1.44log(n)$$)

### Insertion in AVL Trees

Just insert the node as you would do so in a normal BST. Update the heights of every node once the recursive `insert` call returns. Check if the node is out-of-balance. If it is unbalanced, then balance it. You only need to balance 1 node - the **lowest unbalanced node** in the root-to-leaf path of the newly inserted node. This is because once you balance it, the height of the subtree reduces by 1 and the balance is restored (since at any given time, the maximum difference between the heights of the children can be 2 even if it is unbalanced - this is because whenever we see an unbalanced node, we immediately balance it). So, by reducing the height of the larger child by 1, we bring the difference back to less than or equal to 1.

So, the **maximum number of rotations we need to perform during insertion is 2. (It takes** $$O(1)$$ **to rotate after insertion)**

### Tree Rotations

A node is said to be **left-heavy** if the height of its left child is more than that of its right child. Similarly, a node is said to be **right-heavy** if the height of its right child is more than that of its left child. For the purpose of explaining tree rotations, we assume that the node we wish to balance is left-heavy. Then, there are 3 cases to consider:

**Case 1:** `node.left` is balanced - perform right rotation on the node. (the height of the subtree remains unchanged) (This case is unreachable during insertion - think carefully why: a newly inserted node caused $$A$$ to go out of balance. Since $$B$$ has a heavier weight, this means that $$B's$$ height increased by $$1$$ after the insertion. The new element either went to the left subtree or right subtree of $$B$$ and caused an increase in the height. So, before the insertion, at least one of them had a height $$k-1$$. If the other had a height $$k$$, then $$B's$$ height would already have been $$k+1$$ and there would be no increase in height of $$B$$, and hence no imbalance of $$A$$. So, the other subtree of $$B$$ must have had a height $$k-2$$. But this contradicts the fact that after insertion, both subtrees of $$B$$ have the same height. Hence, this can never happen during insertion!!! If you still don’t understand, write a formal proof for it.)

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fw4ZAgkRPsQLqBeqcECIG%2FScreenshot_2022%2003%2001_at_3.28.10_PM.png?alt=media" alt=""><figcaption></figcaption></figure>

**Case 2:** `node.left` is also left-heavy - perform right rotation on the node (the height of the subtree reduces by 1 —> restores balance).

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fpmoyu8Z8ifHm05njICHl%2FScreenshot_2022%2003%2001_at_3.29.19_PM.png?alt=media" alt=""><figcaption></figcaption></figure>

**Case 3:** `node.left` is right-heavy, then first perform left-rotation on the left child (to make it left heavy, and reduce it to case 2), and then perform a right-rotation on the node.

<div><figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FzR5empevyu5yzGpyH00e%2FScreenshot_2022-03-01_at_3.31.25_PM.png?alt=media&amp;token=21190226-71d4-4cb1-9912-b82d8ceb804d" alt=""><figcaption></figcaption></figure> <figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FYqDzkC7IrtiZK8spbByP%2FScreenshot_2022-03-01_at_3.31.43_PM.png?alt=media&amp;token=eeb026a7-2f47-4930-becc-2a5c73779fb8" alt=""><figcaption></figcaption></figure></div>

```java
rightRotate(v):
	w = v.left;
	w.parent= v.parent // w becomes the root of the subtree
	v.parent = w;
	v.left = w.right;
	w.right = v; // v becomes the right child of w
```

Right rotation —> root of the subtree moves right

Left rotation —> root of the subtree moves left

Note that a left-rotation requires a right child and a right-rotation requires a left-child.

In Cases 2 and 3, the height of the resulting tree reduces by 1, and Case 1 is unreachable during insertion (since if this happened, it would mean that the tree was already unbalanced before). Therefore, we only need to perform rotation on the lowest unbalanced node during insertion and we are done!

Trick to remember which rotation to perform:

1. **When a node is left-heavy, we perform a right-rotation (on that node) and vice versa.**
2. **When the node and its heavier child have opposite heaviness (left-right-heavy or right-left-heavy), we need to perform 2 rotations.**

### Deletion in AVL Tree

Similar to insertion into an AVL tree, when you delete a node, you need to update the heights of the nodes once the recursive call returns. Also, there is a chance that some nodes become unbalanced. However, in case of deletion, you need to perform $$O(\log n)$$ rotations, as simply balancing one node does not ensure that the rest of the nodes become balanced automatically. This is because deletion results in a possible reduction of height. Rebalancing also results in a possible reduction of height. So, the two do not “cancel out” as they did in case of insertion. So, it is necessary to propagate the change in height throughout the root-to-leaf path by performing rotations whenever necessary. In the worst case when the height of the tree is $$h$$, you may have to perform $$2h$$ rotations.

Fun fact: It is possible to create every possible tree shape using rotations !!

A possible optimisation: Storing the height of a node can possibly take 32 bits (depends on the default memory for an `int`). You can instead store just the difference between the left and right child of the node and use a maximum of 2 bits!)

Note (Midterm question): **An AVL tree (in fact, any balanced tree) does not give any bound for the difference in depths of leaves. In particular, the difference in depth of leaves (from the root) can be as large as** $$\Theta(logn)$$ **where** $$n$$ **is the number of nodes in the height-balanced binary tree.**

An AVL tree is said to be **maximally imbalanced** if it has the maximum possible height for the number of nodes it contains. A property of a maximally imbalanced tree is that every node in the tree is maximally imbalanced, i.e., the subtree rooted at every node is also maximally imbalanced. To generate a maximally imbalanced tree, you need to ensure that each node is either left-heavy or right-heavy (but not balanced! since that would decrease height). This is simply a consequence from the fact that an AVL tree with the minimum possible number of nodes with height $$h$$ has two subtrees with minimum possible number of nodes with height $$h − 1$$ and $$h − 2$$, namely $$S(h) = S(h−1)+S(h−2)+1.$$


# Trie

**Aim: Searching for a string in a tree in** $$O(L)$$ **time (where** $$L$$ **is the length of the string), Performing Partial String Operations, Prefix Queries, etc.**

## Option 1: Just use a Tree!

If we store a string at every node of a tree, in which all the nodes are sorted lexicographically, then how much time do we take to find a string in the tree?

It takes $$O(L)$$ to compare two strings of length $$L$$. So, in the worst case it would take $$O(hL)$$time to find a string in a tree, where $$h$$ is the height of the tree. We can do better than this!

## Using Tries!

Store a letter (instead of a string) at every node of the tree. Then, you just have to compare each letter at every level of the trie. You need to have an end-of-string character to indicate that a string ends at that particular node. This can be done simply by using a variable at every node. Each node stores an array of its children. If you wish to have only lower-case strings in your trie, each node will have an array of length 26 for its children.

Note that it takes $$O(1)$$ to find the child since you maintain an array of children at each node. For example, if you are searching for “c” as the next character, you know that if the node exists, it would be at index 2 of the children array. No need to loop through the entire array. Thus, $$O(1)$$ lookup time.

### Time

* Tries are much faster than trees for string-comparisons (and other cool stuff too!).
* Does not depend on the size of the total text.
* Does not depend on the number of strings in the trie.

### Space

* Trie tends to use more space
* BST and Trie use $$O(\text{text size})$$ space.
* Trie has more nodes and more overhead.

### Applications of Tries

* Searching, sorting and enumerating strings in a “dictionary”
* Performing partial string operations inlcluding but not limited to:
  * **Prefix queries**: find all the strings that start with a specific substring
  * **Long prefix**: what is the longest prefix of a given string in the trie
  * **Wildcards**: find a string of the form pi??e where ? could be any letter

### Basic Trie implementation

Supports insertion, search, prefix query, wildcards

```java
import java.util.ArrayList;

public class Trie {

    // Wildcards
    final char WILDCARD = '.';
    TrieNode root; //Each trie needs to have a root of the trie

    private class TrieNode {

        // 26 (Uppercase) + 26 (Lowecase) + 10 (Numbers) = 62
        int[] presentChars = new int[62];

        /*
        0 - 9 correspond to the numbers 0 - 9
        10 - 35 correspond to the uppercase alphabets A - Z
        36 - 61 correspond to the lowercase alphabets a - z
         */
        TrieNode[] children = new TrieNode[62];
        boolean endOfString = false;
        String c;

        TrieNode(String c) {
            this.c = c;
        }
        TrieNode() {}

    }

    public Trie() {
        // TODO: Initialise a trie class here.
        this.root = new TrieNode("");
    }

    /**
     * Inserts string s into the Trie.
     *
     * @param s string to insert into the Trie
     */
    void insert(String s) {
        // TODO
        insert_helper(s,this.root,0);
    }

    /**
     * Inserts the ith character of the string into the trie at node
     * @param s
     * @param node
     * @param i
     */
    public void insert_helper(String s, TrieNode node, int i) {
        if (i >= s.length()) {
            node.endOfString = true;
            return;
        }
        char character = s.charAt(i);
        int ascii = (int) character;
        if (ascii >= 48 && ascii <= 57) {
            ascii -= 48; //Since ascii = 48 corresponds to index 0 in the children array
        } else if (ascii >= 65 && ascii <= 90) {
            ascii -= 55; //Since ascii = 65 corresponds to index 10 in the children array
        } else if (ascii >= 97 && ascii <= 122) {
            ascii -= 61;
        }
        if (node.children[ascii] == null) node.children[ascii] = new TrieNode(Character.toString(character));
        insert_helper(s, node.children[ascii], i + 1);
    }

    /**
     * Checks whether string s exists inside the Trie or not.
     *
     * @return whether string s is inside the Trie
     */
    boolean contains(String s) {
        // TODO
        return contains_helper(s, this.root, 0);
    }
    public boolean contains_helper(String s, TrieNode node, int i) {
        if (i >= s.length()) return node.endOfString;
        char character = s.charAt(i);

        int ascii = (int) character;
        if (ascii >= 48 && ascii <= 57) {
            ascii -= 48; //Since ascii = 48 corresponds to index 0 in the children array
        } else if (ascii >= 65 && ascii <= 90) {
            ascii -= 55; //Since ascii = 65 corresponds to index 10 in the children array
        } else if (ascii >= 97 && ascii <= 122) {
            ascii -= 61;
        }
        if (node.children[ascii] == null) return false;
        else return contains_helper(s, node.children[ascii], i + 1);
    }

    /**
     * Searches for strings with prefix matching the specified pattern sorted by lexicographical order. This inserts the
     * results into the specified ArrayList. Only returns at most the first limit results.
     *
     * @param s       pattern to match prefixes with
     * @param results array to add the results into
     * @param limit   max number of strings to add into results
     */
    void prefixSearch(String s, ArrayList<String> results, int limit) {
        // TODO
        if (results.size() >= limit) return;
        prefixSearchHelper(s, results, limit, 0, this.root, new StringBuilder());

    }
    void prefixSearchHelper(String s, ArrayList<String> results, int limit, int index, TrieNode node, StringBuilder curr) {
        if (node == null || results.size() > limit) return;
        // If you are at a node, it means that you are meant to be there. So, add that letter to curr without checking
        // Then continue checking for the rest

        curr.append(node.c);
        if (node.endOfString && index >= s.length()) results.add(String.valueOf(curr));

        // we have already finished the prefix, just find all possible strings in the trie rooted at node
        // sort of DFS
        // We exploit the lazy evaluation of logical operators in java below
        if (index >= s.length() || s.charAt(index) == WILDCARD) {

            for (TrieNode child : node.children) {
                if (results.size() > limit) return;
                prefixSearchHelper(s, results, limit, index + 1, child, new StringBuilder(curr));
            }
        }
        else {
            // we still need to stick to finding the prefix
            char character = s.charAt(index);
            int ascii = (int) character;
            if (ascii >= 48 && ascii <= 57) {
                ascii -= 48; //Since ascii = 48 corresponds to index 0 in the children array
            } else if (ascii >= 65 && ascii <= 90) {
                ascii -= 55; //Since ascii = 65 corresponds to index 10 in the children array
            } else if (ascii >= 97 && ascii <= 122) {
                ascii -= 61;
            }
            if (node.children[ascii] == null) return;
            prefixSearchHelper(s, results, limit, index + 1, node.children[ascii], curr);
        }

    }

    // Simplifies function call by initializing an empty array to store the results.
    String[] prefixSearch(String s, int limit) {
        ArrayList<String> results = new ArrayList<String>();
        prefixSearch(s, results, limit);
        return results.toArray(new String[0]);
    }

    public static void main(String[] args) {
        Trie t = new Trie();
        t.insert("peter");
        t.insert("piper");
        t.insert("picked");
        t.insert("a");
        t.insert("peck");
        t.insert("of");
        t.insert("pickled");
        t.insert("peppers");
        t.insert("pepppito");
        t.insert("pepi");
        t.insert("pik");

        System.out.println(t.contains("peter"));

//        String[] result1 = t.prefixSearch("pe", 10);
//        for (String s : result1) {
//            System.out.println(s);
//        }
//        String[] result2 = t.prefixSearch("pe.", 10);
//        for (String s : result2) {
//            System.out.println(s);
//        }
//        String[] result3 = t.prefixSearch(".e.p", 10);
//        for (String s : result3) {
//            System.out.println(s);
//        }

        // result1 should be:
        // ["peck", "pepi", "peppers", "pepppito", "peter"]
        // result2 should contain the same elements with result1 but may be ordered arbitrarily
    }
}
```


# Hash (Symbol) Table

### Symbol (Hash) Table

A symbol table is an abstract data type that supports insert, search, delete, contains and size methods. The important thing to note here is that unlike a dictionary which supports successor or predecessor queries, a symbol table is **unordered**. That is, there is no ordering of keys in the data structure.

### Java `hashCode()`

Every object supports the method: `int hashCode()` - it returns the memory location of the object. Every object hashes to a different location.

hashcode is always a 32-bit integer. Therefore, every 32-bit integer can get a different hashcode (without any collisions in this step!)

```java
// implementation of hashCode() for integers (32-bit)

public int hashCode() {
	return value;
}

// implementation of hashCode() for Long (64-bit)
// there will be collisions because the number of items is twice the possible number of hashcodes.
// In particular, for every hashcode, there will be 2 Longs that have that same hashCode.
// Note: x >>> n removes the last n (least significant) bits from x
// So, XOR is performed between the first 32 bits and the last 32 bits of the Long
public int hashCode() {
	return (int) (value ^ (value >>> 32));
}

// implementation of hashCode() for Strings is a little more complicated
public int hashCode() {
	int h = hash;
	if (h == 0 && count > 0) {
		int off = offset;
		char val[] = value;
		int len = count;
		for (int = 0; i < elen; i++) {
			h = 31*h + val[off++]; // we choose 31 because it is prime and also 2^5 - 1 (close to a power of 2)
		}
		hash = h;
	}
return h;
}
```

#### Rules regarding `hashCode()`

* Always returns the same value, if the object hasn’t changed
* If two objects are equal, then they return the same hashCode (but the converse is not necessarily true)
* You must redefine the `equals(Object obj)` method to be consistent with `hashCode()`

#### Rules regarding `equals(Object o)`

* Reflexive: `x.equals(x)` is true
* Symmetric `x.equals(y)` $$\iff$$`y.equals(x)`
* Transitive `x.equals(y)` $$\wedge$$ `y.equals(z)` $$\implies$$`x.equals(z)`
* Consistent: always returns the same answer
* Null is null. `x.equals(null)` is always false

#### Java implementation of `V get(Object key)` (Uses Chaining)

```java
public V get(Object key) {
   if (key == null) return getForNullKey();
   int hash = hash(key.hashCode());
   for (Entry<K,V> e = table[indexFor(hash,table.length)]; e != null; e = e.next) {
		Object k;
		if (e.hash==hash &&((k=e.key)==key)||key.equals(k))) // Java checks if the key is equal to the item in the hash table
		// before returning it
		      return e.value;
		}
   return null;
}
```

#### Java `int hash(int h)`

```java
static int hash(int h) {
   h ^= (h >>> 20) ^ (h >>> 12);
   return h ^ (h >>> 7) ^ (h >>> 4);
}
```

Before `hash()` is applied, the object is converted to an integer representation - that is called a **pre-hash.**

### `java.util.HashMap`

#### `java.util.map` Interface

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FpoEPEbHHjhwqzlDTVWpq%2FScreenshot_2022-03-14_at_10.06.40_AM.png?alt=media&amp;token=069d2bf7-7386-4468-a0e9-1e0d54d36308" alt=""><figcaption></figcaption></figure>

Map is a parameterized interface: parameterized by key and value. The key and value need not be comparable.

No duplicate keys are allowed

No mutable keys are allowed - if you use an object as a key then you can’t modify that object later

Although java.util.Map also supports the following operations, it is not necessarily efficient to work with them since it is not sorted:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FIBIKODYm88yLVbm5TJrO%2FScreenshot_2022-03-14_at_10.08.52_AM.png?alt=media&amp;token=a4afb4bf-91f8-4356-bbe4-2c5eb3b57b38" alt=""><figcaption></figcaption></figure>

In java, TreeMap (dictionary) supports far more operations than HashMap (symbol table) but HashMap provides efficient implementations for the operations that it does support

## Idea 1: Implement using AVL tree

If we implement a symbol table using an AVL tree, the cost of insertion is $$O(logn)$$ and the cost of searching is also $$O(logn)$$ (Moreover, this is because it stores the key in an ordered fashion and hence it also supports successor and predecessor queries).

But what if we don’t want/need any ordering or successor/predecessor queries? Is it possible to sacrifice the ordering to gain some extra speed in insertion and searching? YES!

Our aim is to implement a symbol table with cost of insertion and cost of searching $$O(1)$$.

It is a well-known fact that any comparison based sorting algorithm requires at least $$\Omega(nlogn)$$ comparisons. Furthermore, the fastest searching algorithms (eg. binary search) require at least $$\Omega(logn)$$ comparisons. So, how is it possible to achieve $$O(1)$$ for insertion and searching?? Simple - we don’t use comparison based operations (at least not directly - i.e., we don’t directly compare the elements, we compare based on their hashes 😅).

## Attempt 1: Use a direct access table - indexed by keys

For example, if you wanted to store (4, Devansh) in the table, it would be stored at index 4 of the array/table.

Problems:

1. Too much space (in particular, if keys are integers, then the table size > 4 billion)
2. How would you store non integral values?
3. How do you handle duplicates?

## Hash Functions

We use hash functions to map a huge possible number of keys (out of which we have $$n$$ actual keys) to $$m$$ number of buckets.(You don’t know which keys are going to be inserted, and new keys can be inserted, old keys can be deleted, etc.)

So, we define a hash function $$h : U \rightarrow {1,\dots,m}$$ where $$U$$ is the universe of possible keys (the permissible keys). We store the key $$k$$ in the bucket $$h(k)$$.

Time complexity for insertion: Time to compute $$h$$ + Time to access bucket. If we assume that a hash function has $$O(1)$$ computational time, then we can achieve insertion in $$O(1).$$

### Collisions

We say that 2 distinct keys $$k\_1,k\_2$$ collide if $$h(k\_1) = h(k\_2)$$.

By pigeonhole principle, it is impossible to choose a hash function that guarantees 0 collisions (Since the size of the universe of keys is much larger than $$m$$)

So, how do we deal with collisions? Chaining and Open Addressing, of course!

## Chaining

Each bucket contains a linked list of items. So, all the keys that collide at a particular value are all inserted into the same bucket.

How does this affect the running time of insert? No change! Still $$O(cost(h))$$ to compute hash function + $$O(1)$$ to add it to the **front** of the linked list. This is if we assume that we are not checking for duplicate keys while inserting.

How does this affect the running time of search? Well, now once we find the bucket in $$O(cost(h))$$ time using the hash function, we may need to traverse the entire linked list to find the key. So, it can take up to $$O(\text{length of the longest chain})$$, which is $$O(n)$$ **in the worst case** (when all the inserted keys collide into the same bucket - as obviously intended by the adversary who is running your program)

Similarly, deletion also takes $$O(n + cost(h))$$ time.

**Question**

Imagine that we implement a symbol table using a single-ended Queue as the data structure. What would be the worst-case time complexities of insert, delete and search operations? (Assume we do not try to insert duplicate keys. You can only access the queue using standard queue operations, e.g., enqueue and dequeue.)

Answer: Insertion takes $$O(1)$$, Search and Deletion takes $$O(n)$$

**Question**

Assume that we're using a hash function to map keys to their respective positions in the symbol table. The time complexity for computing the hash is `O(b)` for an input key of size `b` while array access and comparing keys is constant time complexity.  Assuming collisions are resolved by chaining linked lists and `m` elements are present in the table, and assuming there are never duplicate values inserted, what is the worst-case time complexity of insert and search operations on keys containing n bits?

Answer: Insertion $$O(n)$$, Search $$O(n + m)$$

#### Simple Uniform Hashing Assumption (SUHA)

1. Every key is equally likely to map to every bucket.
2. Keys are mapped independently of previously mapped keys.

**Question**

Why don’t we just insert each key into a random bucket, i.e., why do we need a specific hash function at all?

Answer: Because then searching would be very very slow. How would you find the item when you need it?

### Load

The load of a hash table is the expected number of items per bucket. If we assume that we have $$n$$ items and $$m$$ buckets then,

$load(hash\ table) = \dfrac{n}{m} = average \ # items/bucket$$

So, Expected Search Time = $$O(1)$$ + Expected number of items per bucket (Assuming it takes $$O(1)$$ for hash function computation and array access)

Let us calculate the expected search time in such a case.

Let $$X$$ be a random variable defined by:

$$
\begin{equation\*} X(i,j) = \begin{cases} 1 \qquad \text{if item } i \text{ is put in bucket }j \ 0 \qquad \text{otherwise} \end{cases} \end{equation\*}
$$

We define the random variable in this way so that for any bucket $$j$$, $$\sum\_i X(i,j)$$ gives us the number of items in that bucket.

$$P(X(i,j) = 1) = \dfrac{1}{m}$$ for any value of $$i,j$$. This is simply because there are $$m$$ possible buckets for any item and each can be picked with equal probability.

$$
E(X(i,j)) = P(X(i,j) = 1)\times 1 + P(X(i,j) = 0)\times 0 = \dfrac{1}{m}
$$

So, expected number of items in bucket $$b$$ would be:

$$\sum\_i X(i,b) = \dfrac{n}{m}$$. (Each item contributes $$1$$ to the bucket it is in).

Hence, Expected Search Time = $$O(1)$$ + $$\dfrac{n}{m}$$. (So, we take $$m = \Omega(n)$$ buckets, eg. $$m = 2n$$)

(But it is important to realise that the **worst-case search time** (not expected running time!) is still $$O(n)$$).

**Question**

What if you insert $$n$$ elements in your hash table which has $$n$$ buckets. What is the expected **maximum** cost?

Answer: This is like throwing $$n$$ balls into $$n$$ bins. The expected maximum number of balls in a bin is $$O(\log n)$$. Actually, a tighter bound would be $$\Theta(logn/log(logn))$$ → it’s not that trivial to prove.

## Open Addressing

#### Advantages

* No linked lists!
* All data is stored directly in the table
* One item per slot

**Logic:** On collision, probe a sequence (deterministic) of buckets until you find an empty one

Example of a probe sequence: **linear probing:** (if $$h(k)$$ is taken, then look at bucket $$h(k) + 1$$ and so on, until you find a bucket that is empty)

So now for this we need to have a new hash function,

$$h(key, i) : U \rightarrow {1,2,\dots, m}$$ where $$key =$$ the item to map, $$i + 1=$$ the number of collisions encountered so far.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FxtXYtZKmYlQnsm7VHly8%2FScreenshot_2022-03-14_at_8.27.10_AM.png?alt=media&amp;token=118fca73-851f-4697-bde2-b1e8fc78ea40" alt=""><figcaption></figcaption></figure>

#### Probing Code (Need not be Linear Probing)

```java
hash-insert(key, data) {
	int i = 1;
	while (i <= m) {
		int bucket = h(key, i);
		if (T[bucket] == null) { // Found an empty bucket
			T[bucket] = {key, data}; // Insertion
			return success;
		}
		i++;
	}
	throw new TableFullException(); // you visited every bucket and checked that it was full :(
```

```java
hash-search(key) {
	int i = 1;
	while (i <= m) {
		int bucket = h(key, i);
		if (T[bucket] == null) // Empty bucket! If this is empty, we know that the key cannot be
		// after this because it would have come here during the probe sequence
			return key-not-found;
		if (T[bucket].key == key) // Full bucket
			return T[bucket].data;
		i++;
	}
	return key-not-found; // Exhausted entire table
```

#### Deleting a Key

If you just remove the key from the table and set it to `null`, during search, the hash-search function may return `key-not-found` even if the key exists (because of the “gap” in the probe sequence).

Simple solution: Don’t set the value to `null` on deletion, set it to `DELETED` to indicate that the slot is empty now but there was an element here before.

If you encounter a `DELETED` value while probing for a bucket to insert, you can feel free to insert the new item there (because `DELETED` is just a placeholder that can be safely overwritten)

#### Hash Functions

2 Properties of a good hash function:

1. $$h(key, i)$$ enumerates all possible buckets as $$i$$ iterates from $$1$$ to $$m$$ (So that you only return `TableFullException()` when the table is actually full and you have made sure that there are no empty slots).
   1. For every key $$key$$, and for every bucket $$j, \exists \ i, \ h(key, i) = j$$
   2. The hash function is a permutation of $${1,2,\dots,m}$$
2. **Uniform Hashing Assumption (UHA) -** Every key is equally likely to be mapped to every permutation, independent of every other key. (There are $$m!$$ permutations for a probe sequence, where $$m =$$ table size.

Note that Linear Probing satisfies the first property but does not satisfy the second property! (For example, it is impossible to find a key $$k$$ such that its hash generates the permutation $$2,1,3$$ for a table of size 3. This is because the only possible permutations generated by the linear probing sequence is $$1,2,3$$ or $$2,3,1$$ or $$3,1,2$$)

#### Problem with Linear Probing: Clusters

If there is a cluster (when a lot of elements are placed in contiguous buckets), there is a higher probability that the next $$h(k)$$ will hit the cluster. Because if $$h(k,1)$$ hits the cluster (any bucket in the cluster), the cluster grows bigger as the item gets added to the end of the cluster. This is an example of “rich get richer”.

If the table is $$1/4$$ full, there will be clusters of $$\Theta(\log n)$$. This ruins constant-time performance for searching and inserting.

But, in practice linear probing is very fast! Why?

Because of caching! It is cheap to access nearby array cells (since the entire block containing a lot of contiguous array cells is loaded into the main memory). For example, if you want to access `A[17]`, the cache loads `A[10...50]`. Then, it takes almost 0 cost to access any cells in that range. Recall that block transfer time is far far more than memory access time.

So, even though there will be clusters of $$\theta(logn)$$ when the table is $$1/4$$ full, the cache may hold the entire cluster. So, this makes linear probing no worse than a wacky probe sequence that circumvents the issue of clusters.

#### Good hashing functions

We saw that linear probing does not meet the second criteria of a good hash function, i.e., it does not satisfy UHA. So, the question is: How do we get a good hash function that satisfies UHA? Double hashing of course!

Start with 2 ordinary hash functions satisfying SUHA: $$f(k), g(k)$$

Define a new hash function: $$h(k, i) = (f(k) + i\times g(k))\ mod \ m$$

Since $$f(k)$$ is pretty good, $$h(k,1)$$ is “almost random”.

Since $$g(k)$$ is pretty good, the probe sequence becomes “almost random” (we just added some “noise” to the value to increase randomness). (we need to $$mod \ m$$ in the end so that we get a value between $$0$$ and $$1-m$$ and we can map it to a bucket of table size $$m$$.)

#### $$h(k,i) = (f(k) + i\times g(k))\ mod \ m$$

**Claim: if** $$g(k)$$ **is relatively prime (co-prime) to** $$m$$**, then** $$h(k,i)$$ **hits all buckets (i.e., it generates a permutation of** $${1,\dots,m}$$**.**

Proof: Suppose not. Then for some distinct $$i, j< m$$ (since it does not hit all buckets then there must be two equal values of $$h(k,i)$$ for two distinct $$i,j$$ - by Pigeonhole Principle):

$$
\begin{equation\*} \begin{split} (f(k)+ ig(k)) \ mod \ m&= (f(k) + jg(k)) \ mod \ m \ ig(k) \ mod \ m &= jg(k) \ mod \ m \text{\quad (since (a+b)mod m = ((a mod m) + (b mod m)) mod m ) } \ (i - j)g(k) &= 0 \ mod \ m \ \implies & g(k) \text{ is not relatively prime to }m \text{ since }i,j < m \end{split} \end{equation\*}
$$

Example: If $$m = 2^r$$, then choose $$g(k)$$ to be odd for all keys $$k$$.

### Performance of Open Addressing

Let Load $$\alpha = n/m = Average # \dfrac{ items}{bucket}$$. Assume $$\alpha < 1$$ (the table is not full)

**Claim: For** $$n$$ **items, in a table of size** $$m$$**, assuming uniform hashing, the expected cost of an operation (insert, search, delete) is:** $$\leq \dfrac{1}{1-\alpha}$$**.**

Example: if $$\alpha = 90%$$, then $$E\[#probes] = 10$$.

**Proof of Claim:**

Say, you have already inserted $$n$$ items and you want to insert the next element $$k$$.

The probability that the first bucket you find (i.e., $$h(k,1)$$) is full is $$n/m$$. Then, the probability that the second bucket is full given that the first bucket is also full is $$\dfrac{n-1}{m-1}$$. So, you need to probe again: probability that the third bucket is also full given that the first two are full: $$\dfrac{n-2}{m-2}$$ and so on..

Expected cost: $$1 + \dfrac{n}{m}\left( 1 + \dfrac{n-1}{m-1}\left( 1 + \dfrac{n-2}{m-2} \dots\right)\right)$$

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2F2XPN2qgd2Hdtczd1l8KV%2FScreenshot_2022-03-14_at_9.43.08_AM.png?alt=media&amp;token=a6653c47-b895-4c49-a082-fe043490e7ad" alt=""><figcaption></figcaption></figure>

**Note:** $$\dfrac{n - i}{m - i} \leq \dfrac{n}{m} = \alpha$$**. (only when** $$\dfrac{n}{m} < 1$$**).** For example, $$\dfrac{4-1}{3-1} = \dfrac{3}{2} > \dfrac{4}{3}$$)

Therfore, expected cost is $$\leq 1 + \alpha(1 + \alpha^2(1 + \dots)) \leq 1 + \alpha + \alpha^2 + \dots = \dfrac{1}{1-\alpha}$$

If $$n < m$$, the expected cost of searching in a hash table using open addressing is $$O(1)$$. Is this true or false?

False. Let $$n = m - 1$$. Then $$\dfrac{1}{1-\alpha} = \dfrac{1}{1-(n-1)/n} = \dfrac{1}{1-(1-1/n)} = \dfrac{1}{1/n} = n$$ so it will take $$O(n)$$ to search for an item in a hash table with $$n$$ items and $$n+1$$ buckets. Moreover, we know that when we use linear probing and even if the table is quarter full, we will have clusters of size $$\Theta(logn)$$ in expectation. So, the cost of searching in a hash table using open addressing is at least $$logn$$.

**You are only allowed to use** $$O(\dfrac{1}{1-\alpha})$$ **under the assumption of UHA. Linear probing, quadratic probing, etc. do not satisfy UHA and you cannot use this time complexity!**

**If** $$m$$ **(table size) is prime, and** $$\alpha < 0.5$$**, only then we can guarantee that quadratic probing hits all the buckets in the table. Sometimes, it is possible that quadratic probing finds an empty slot in the table after** $$m$$ **tries too (which is why some people wait for a longer time before they return a `tableFullException()`.**

### Summary of Open Addressing

Advantages:

* Saves space - Empty slots vs linked lists (in chaining)
* Rarely allocate memory (only during table resizing) - no new list-node allocations
* Better cache performance - table all in one place in memory. Fewer accesses to bring the table into cache. Linked lists can wander all over memory.

Disadvantages:

* More sensitive to choice of hash function: clustering is a common problem in case of linear probing
* More sensitive to load (than chaining) - performance degrades very badly as $$\alpha \rightarrow 1$$&#x20;

| Chaining                                                     | Open Addressing                                                     |
| ------------------------------------------------------------ | ------------------------------------------------------------------- |
| When $$m== n$$, we can still add new items to the hash table | When $$m == n$$, the table is full and we cannot add any more items |
| We can still search efficiently when $$m == n$$              | We cannot search efficiently when $$m == n$$                        |

## Table Resizing

Throughout this discussion of table resizing, assume that we are using **hashing with chaining** and our hash function obeys simple uniform hashing (although this is a false assumption - it can never be true in practice)

We know that the expected search time is $$O(1 + n/m)$$.

So, the optimal size of the table is $$m = \Theta(n)$$.

The problem is we don’t know $$n$$ in advance. If $$m < 2n$$, then there’s a possibility of too many collisions, and if $$m > 10n$$ , there’s too much wasted space (of course the numbers 2 and 10 here are arbitrary but it provides some intuition as to why we need to grow and shrink our table size as new elements are added and old elements are deleted from the table).

**Idea:** Start with a small constant table size. Grow and shrink the table as necessary.

1. Choose a new table size $$m'$$
2. Choose a new hash function $$h'$$ (Why do we need a new hash function? Because the hash function depends on the table size! $$h: U \rightarrow {1,\dots,m}$$. Java hides this by doing the hashing itself)
3. For each item in the old hash table, compute the new hash function and copy item to the new bucket.

How much time would this take? Well, it takes $$O(m)$$ to access $$m$$ buckets. In each of the $$m$$ buckets, we need to access the elements themselves. There are $$n$$ elements. So, it takes $$O(n)$$ elements for that. ALSO, allocating memory takes time proportional to the memory size being allocated. That is, if you initialise a large array, that takes some time. So, to allocate a table of size $$m\_2$$, it takes $$O(m')$$.

Hence, the total time to grow/shrink the table is $$O(m + m' + n)$$.

But... How much should we grow by? When should we grow?

#### Idea 1: Increment table size by 1

This is a ridiculously bad idea because each time you add a new element, you need to create an entirely new table. This takes too much time (in particular, the total time for inserting $$n$$ items would be $$O(n^2)$$) This is because you are thinking short-term and each time you insert after growing the table, the table becomes full again. So, when you insert again, you need to resize.

Note that this is also true for incrementing the table size by a constant number (i.e., $$m' = m + c$$ will also take $$O(n^2)$$ for large values of $$n$$ no matter how large $$c$$ is). Unfortunately, even seasoned software engineers write code that grows the table size by a constant factor like 1000, forgetting that it is still a bad design decision which leads to $$O(n^2)$$ complexity.

#### Idea 2: Double table size

if $$(n == m): m' = 2m$$ (when the table is full, create a new table whose size is double - so there is sufficient space for insertions to occur)

Then, you perform expansions only $$O(logn)$$ times while inserting $$n$$ items. So, the total cost of inserting $$n$$ items is $$O(n)$$.

For example, let your initial table size be 8 (it’s always good practice to keep your table size a power of 2). Then, the cost of resizing is:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FprlpkKDbF8nXPhStFoSs%2FScreenshot_2022-03-14_at_10.27.40_AM.png?alt=media&amp;token=383bcba6-c2a0-44a9-8b86-5b44c58fa706" alt=""><figcaption></figcaption></figure>

Cost of resize: $$O(n)$$

Cost of inserting $$n$$ items + resizing: $$O(n)$$

Most insertions take $$O(1)$$ time (since no resize is required). Some insertions are expensive (linear cost).

The average cost per operation is $$O(1)$$. In fact, the amortized cost of insertion is $$O(1)$$ - think of depositing $$$3$$ each time you insert an element, with each insert operation itself costing $$$1$$. You use the additional $$$2$$ to grow the table size (assuming growing to a size $$m$$ requires $$$m$$ and so, each element needs to have $$$2$$ to contribute to the expansion process). Observe that you are growing the table only after filling it completely and so you are sure that you have added $$m$$ new items before the next growth occurs (assuming current table size is $$m$$). Similarly for deletion, deposit $$$3$$ for each delete operation: $$$1$$ to fund the delete operation and $$$2$$ for future shrink operations. So, each operation requires a constant amount of money and hence is amortized $$O(1)$$.

#### Idea 3: Squaring table size

If doubling table size is good, squaring table size must be better right? Well, no. not really. In fact, it is $$O(n^2)$$. This is because you’re allocating toooo much memory at each resize. For example, if your table size is 64 and you insert the 65th element, the table size grows to 64\*64 = 4096!

Each resize takes $$O(n^2)$$ time. So, average cost of each operation is $$O(n)$$.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fdqhf2TEViV3oQFgzV5dg%2FScreenshot_2022-03-14_at_10.31.42_AM.png?alt=media&amp;token=a1a84ab2-110f-4169-95f0-9bbd59f620e2" alt=""><figcaption></figcaption></figure>

### Shrinking Table

When the table becomes too big, we need to shrink the table. Again, the question is: When do we shrink?

#### Attempt 1

if $$(n == m) : m' = 2m$$ (grow) and if $$(n < m/2) : m' = m/2$$ (shrink).

This is actually a really bad idea! Consider the following problem:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FD9Sb7XXMPgM4cDGXLEs8%2FScreenshot_2022-03-14_at_10.34.38_AM.png?alt=media&amp;token=13fba7dd-f5b9-4057-b9a8-19d89ed49284" alt=""><figcaption></figcaption></figure>

You might have to resize at every insertion and deletion

#### Attempt 2

If $$(n== m): m' = 2m$$ (grow when the table is full)

If $$(n < m/4): m' = m/2$$ (shrink when the table is less than a quarter full so that when you half the size, there is still sufficient space for insertions to be performed)

**Claim (very important invariants that you should be able to observe for any kind of growth/shrink rules given):**

* **Every time you double a table of size** $$m$$**, at least** $$m/2$$ **new items were added (after your previous grow/shrink operation)**
* **Every time you shrink a table of size** $$m$$**, at least** $$m/4$$ **items were deleted. (after your previous grow/shrink operation)**

These two claims can be easily proven by observation.

By analysing the amortized time complexity, we find that insertion and deletion both take $$O(1)$$ amortized.

Note that search takes **expected** time $$O(1)$$ (not amortized!)

* Insertions and deletions are amortized because of table resizing (i.e., an insertion/deletion algorithm can trigger a table resize once in a while - which is expensive)
* Inserts are not randomized (because we are not searching for duplicates)
* Searches are expected (because of randomization of length of chains in each bucket) and not amortized (since no table resizing on a search)

Suppose we follow these rules for an implementation of an open-addressing hash table, where n is the number of items in the hash table and m is the size of the hash table. (a) If n = m, then the table is quadrupled (resize m to 4m) (b) If n < m/4, then the table is shrunk (resize m to m/2) What is the minimum number of insertions between 2 resize events? What about deletions?

Solution: Insertions: m/2 + 1; Deletions: 1 Suppose that the new inserted entry will cause n = m. Then the table will be resized into m′ = 4m. When we delete an entry, the number of entry will be n−1 = m−1 = m′/4−1 < m′/4. The table will resize again. Hence, the minimum number of deletion before resizing is 1.

At this time, the new table size is m′′ = m′/2 = 2m. The number of insertions before it expands is m′′ − (n − 1) = m′′ − (m′′/2 − 1) = m′′/2 + 1 elements. Note that the answer is calculated relative to the current table size.

#### Designing good hash functions

Simple Uniform Hashing does not exist! It is a false assumption made merely to simplify the analysis and understanding. Even UHA is a false assumption.

This is because keys are not random. There’s lots of regularity between keys and often there are mysterious patterns too! Patterns in keys can induce patterns in hash functions unless you’re very careful.

Consider the following example:

What if we want to hash strings and we keep one bucket for each of the 26 letters from a through z. Then, we define our hash function to be $$h(string) = first\ letter$$ of the string. for example, $$h("hippopotamus") = h$$.

This is a bad hash function! Why? Because many fewer words start with the letter $$x$$ than with the letter $$s$$. So, the length of the chain in bucket $$s$$ will be huge while that in bucket $$x$$ will be very small.

Okay, what if we try another function: one bucket for each number from 1 to 26\*28 (since the longest word in the english language has 28 letters) and we define the hash function to be $$h$$(string) = sum of the letters. Eg. $$h$$(”hat") = $$8 + 1 + 20 = 29$$.

Umm, this is also a bad hash function. Lots of words collide and you won’t get a uniform distribution because most words are short and so the sum will likely be low)

But pretty good hash function exists (eg. SHA256 is a cryptographically secure hash function)

The moral of the story is simple: don’t ever design your own hash function unless you absolutely need to.

### Designing Hash Functions

**Goal: Find a hash function whose valus&#x20;*****look*****&#x20;random (it is impossible to get** $$100%$$ **randomness since we are using a deterministic algorithm)**

This is similar to pseudorandom generators - there’s no real randomness. Instead, the sequence of numbers generated just looks random.

For every hash function, there is some set of keys which leads to bad outputs!

But, if you know the keys in advance, you can choose a hash function that is always good. But if you chaneg the keys, then it might be bad again.

There are 2 common techniques used to design hash functions:

1. Division Method
2. Multiplication Method

#### Division Method

$$h(k) = k\ mod \ m$$

Example: If $$m = 7$$, then $$h(3) = 3, h(10) = 3, h(8) = 1$$

Two keys, $$k\_1$$ and $$k\_2$$, collide when $$k\_1 \ mod \ m = k\_2 \ mod \ m$$

Collision is unlikely if keys are random.

**(Bad) Idea:** choose $$m = 2^x$$ becaue it is very fast to calculate $$k \ mod \ m$$ via bit shifts.

Recall that $$001001 >> 2 = 0010$$ (just remove the last 2 bits).

Then, it can be shown that $$k \ mod \ 2^x = k - ((k >> x) << x)$$.

What is the problem with this? Input keys are often regular. Assume that input keys are all even. Then $$h(k) = k \ mod \ m$$ is always even.

**Note: The remainder when** $$y$$ **is divided by** $$x$$ **(i.e.** $$y % x$$**) is always a multiple of the common divisors (in fact** $$gcd$$**) of** $$y$$ **and** $$x$$**.** (easy to prove)

So, if $$d$$ is a divisor of $$m$$ and **every** key $$k$$, then what percentage of the table is used? $$1/d$$.

Because all the remainders generated are multiples of $$d$$. So, there are only $$m/d$$ such buckets in the table. Hence, out of $$m$$ buckets, only $$m/d$$ buckets would be used. So, $$1/d$$ of the table is used. (you use only 1 slot out of every d slots).

So, we choose $$m=$$ prime number (to minimize the chances of having any divisor common between $$m$$ and the keys). It should not be too close to a power of 2 or a power of 10 (since those are common input keys)

Overall, the division method is popular (and easy) but not always the most effective. This is also because division is often slow.

## Questions on Hashing

#### Implementing sets using Hash Tables

**Consider the following implementations of sets. How would intersect and union be implemented for each of them? (a) Hash table with open addressing (b) hash table with chaining**

(a) Solution: For intersects, we would need to iterate through the bins in one set a and check if the element is also present in the other set b. Elements that are present in both are then placed in the result set r, which can be initialised to an appropriate capacity given that we know the sizes of a and b. Under the uniform hashing assumption, the expected complexity is $$O\left(m\_a + n\_a\left(\dfrac{1}{1-\alpha\_b} + \dfrac{1}{1-\alpha\_r} \right)\right)$$, where $$m\_a$$ denotes the size of hash table $$a$$ and $$n\_a$$ as the number of entries in hash table $$a$$. For unions, we can iterate through the elements in set $$b$$ and insert them into set $$a$$. With similar analysis as in intersects, this is in $$O\left(m\_b + n\_b\left(\dfrac{1}{1-\alpha\_a}\right)\right)$$ where $$m\_b$$ and $$n\_b$$ is defined similarly.

(b) We can use the same strategies for intersects and unions as in 4a). The runtime of both these solutions are $$O(m\_a + \sum\_{k\in a} len(h\_b(k)))$$, and $$O(m\_b + \sum\_{k\in b} len(h\_a(k))$$ respectively. $$len(h\_t(x))$$ denotes the number of entries in the bucket $$h\_t(x)$$ in table $$t$$. In practice, this solution would be good enough, as the length of chains should be $$O(1)$$ (under SUHA, and an appropriate load factor). But to mitigate bad hash functions, Java implements an interesting strategy where buckets exceeding a threshold size are turned into a tree. While this increases insertion times to $$O(log\ size(h(x)))$$, this improves searches in each bucket to the same complexity. Using an ordered structure like a tree also means that in the very specific scenario where the two sets’ capacities and hash functions are the same, we unions and intersects can be done in exactly $$O(size(a) + size(b) + m)$$

#### Table Resizing question

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FrV9lOBaGWZKDEeBi1vEo%2FScreenshot_2022-04-24_at_9.27.18_PM.png?alt=media&amp;token=a6178b2f-b675-4823-9ee9-e711862563d8" alt=""><figcaption></figcaption></figure>

Answer: $$O(1)$$. The explanation is as follows:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2F8glvqUjsr08rcMemZBXw%2FScreenshot_2022-04-24_at_9.26.27_PM.png?alt=media&amp;token=ec982387-589a-4437-ac8f-d8513ca073dd" alt=""><figcaption></figcaption></figure>


# (a, b)-Trees

**Aim:** Allow efficient insertion, deletion, resizing of data in extremely large databases

{% embed url="<https://www.youtube.com/watch?v=aZjYr87r1b8>" %}
Great video to watch
{% endembed %}

## Invariants

In an $$(a,b)$$ tree, $$a$$ and $$b$$ are the parameters where $$2 \leq a \leq (b+1)/2$$.

Respectively, $$a$$ and $$b$$ refer to the minimum and maximum number of **children (NOT keys)** an internal (i.e., non-root, non-leaf) node can have.

| Binary Tree                      | (a,b)-trees                             |
| -------------------------------- | --------------------------------------- |
| Each node has at most 2 children | Each node can have more than 2 children |
| Each node stores exactly 1 key   | Each node can store multiple keys       |

Every $$(a,b)$$-tree must satisfy the following 3 rules:

#### 1. $$(a,b)$$ *- child Policy*

| Node Type | Min Keys  | Max Keys  | Min Children | Max Children |
| --------- | --------- | --------- | ------------ | ------------ |
| Root      | 1         | $$b - 1$$ | 2            | $$b$$        |
| Internal  | $$a - 1$$ | $$b - 1$$ | $$a$$        | $$b$$        |
| Leaf      | $$a - 1$$ | $$b - 1$$ | 0            | 0            |

With the exception of leaves, note that the **number of children is always one more than the number of keys.**

#### 2. *Key Ranges*

A **non-leaf** node (i.e, root or internal) must have one more child than its number of keys. This is to ensure that all value ranges due to its keys are covered in its subtrees. The permitted range of keys within a subtree is called its **key range.**

In particular, for a non-leaf node with $$k$$ keys and $$k + 1$$ children,

* Its keys in sorted order are $$v\_1, v\_2, \dots , v\_k$$
* The subtrees due to its keys are $$t\_1, t\_2, \dots, t\_{k+1}$$

Then,

* First child $$t\_1$$ has key range $$\leq v\_1$$
* Final child $$t\_{k+1}$$ has key range $$> v\_k$$
* All other children $$t\_i$$ where $$i \in \[2,k]$$ has key range $$(v\_{i-1}, v\_i]$$

#### 3. *Leaf Depth*

All leaf nodes must be at the same depth from the root.

You should realize that a regular BST is just an $$(a,b)$$ tree with $$a = 1, b = 2$$.

## B-Trees

Firstly, it is important to note that the B in B-Tree does not refer to Binary. Actually, no one really knows what the B stands for - it could be Balanced?

B-trees are simply $$(B,2B)$$ trees. That is, they are a subcategory of $$(a,b)$$ trees such that $$a = B, b = 2B$$. For instance, when $$B = 2$$, we have a $$(2,4)$$-tree. (This is sometimes referred to as a $$(2,3,4)$$ tree. An example of a $$(2,3,4)$$-tree is given below:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FX57yYM2qW7tTb95awGnO%2FScreenshot_2022-03-06_at_6.12.12_PM.png?alt=media&amp;token=e752a900-6831-420e-bd55-928fde740900" alt=""><figcaption></figcaption></figure>

**Are B-trees balanced?**

Yes! This is because of Rule 3: All leaves must be at the same depth from the root. This ensures height-balance, which implies balance. In fact, any two siblings (in terms of depth too!) are at exactly the same height. This is due to the fact that a B-tree grows upward from the leaves.

**What is the minimum and maximum height of an** $$(a,b)$$ **tree with n keys?**

The minimum height would be when each leaf has maximum possible number of children (i.e, the tree is dense) and so, minimum height is $$O(log\_bn)$$ and maximum height would be $$O(log\_an)$$.

Now that we have established that an $$(a,b)$$ tree is balanced and height is $$O(log\_an)$$, we see how it helps us for searching, insertion and deletion.

## Searching

What data structure should we use for storing the keys and children in a node?

One possible way is to use an array of (key, subtree) pairs as follows:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2F5lIkIMqMs55FuhQUk8lg%2FScreenshot_2022-03-06_at_6.19.43_PM.png?alt=media&amp;token=5383ca75-e672-4ecd-817c-a048cc820339" alt=""><figcaption></figcaption></figure>

Total search cost?

Height of the tree is $$O(log\_an)$$.

Binary search (woah binary search to the rescue again!) for the key at every node takes $$O(log\_2b)$$ time. (Note that $$b$$ is a constant, and so we consider this as constant time)

Hence, total cost: $$O(log\_2b \times log\_an) = O(log\_an) = O(logn)$$.

## Insertion

The key idea is that just like in BSTs, we only insert at leaves here. So, the idea is to navigate to a suitable leaf and add the new key to its key list.

For example, consider the insertion of the key 71 to the $$(2,4)$$-tree below:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FJAzvjveSPd91pwQU0w1l%2FScreenshot_2022-03-06_at_6.24.44_PM.png?alt=media&amp;token=1343a774-874d-42fd-b6c4-47ae5f99b135" alt="" width="494"><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FdezPIFzFKXlSnRdzprGM%2FScreenshot_2022-03-06_at_6.24.30_PM.png?alt=media&amp;token=246ee51e-4b13-42bc-b1eb-2e527efd69dc" alt="" width="491"><figcaption></figcaption></figure>

But now what happens when you insert 72? You cannot have 4 keys at a single node! Something needs to be done to solve this problem!

Insertion may violate Rule 1: Recall that rule 1 enforces that nodes can have at most $$b - 1$$ keys. Insertion may cause the leaf nodes to grow too large. We need to have some operation to handle such cases.

**Idea**: Redistribute out the keys!

How can we redistribute the keys?

1. Over sibling nodes?
   * No! Cannot guarantee that the rule is still not violated (i.e., now the sibling may be too large)!
2. Over a new node?
   * Yes! We can always guarantee that the postcondition adheres rule 1.

### Split Operation (Key-redistribution)

1. Choose the median key in the overpopulated node.
2. Use that to split the keylist into 2 halves
3. Left half goes into a new node
4. Move median key to the parent node (what do we do when the root gets overpopulated? it has no parents! don’t worry, we will deal with this too)
5. Link the two nodes to the parent.

If we perform the split operation on the example tree above, the following steps are executed:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FgeC1uEj2xjv3aPm5Xgt8%2FScreenshot_2022-03-06_at_6.30.59_PM.png?alt=media&amp;token=938a4059-9b9c-4dcb-9082-c9e5c7d61650" alt="" width="503"><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2F7VM3bQOv7FYfQmpgAX5T%2FScreenshot_2022-03-06_at_6.31.36_PM.png?alt=media&amp;token=cac31282-2f2f-4011-b05c-a3ab2136716d" alt="" width="486"><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2F8WqKzwyfLP4exuiufMUO%2FScreenshot_2022-03-06_at_6.31.46_PM.png?alt=media&amp;token=a9869fce-a21a-4094-8a20-f0fb765ed543" alt="" width="494"><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FCKtGaQM7uXY597FsM4RV%2FScreenshot_2022-03-06_at_6.32.12_PM.png?alt=media&amp;token=bf7085b2-1607-4253-927a-3aedf3c8648a" alt="" width="486"><figcaption></figcaption></figure>

Why must the `split` operation “offer” one key to the parent?

After splitting, the parent will have one more child than before, therefore it must also have one more key. Taking the (median) key from the node to be split is convenient.

Will the split procedure ever end up with nodes too small (i.e, too few keys) such that they violate rule 1?

No. this is because:

1. Keylist size of LHS is $$\lfloor (b-1)/2 \rfloor = \lfloor b/2 - 1/2 \rfloor = \lfloor a - 1/2 \rfloor$$
2. Keylist size of RHS is $$\lceil(b-1)/2 \rceil = \lceil b/2 - 1/2 \rceil = \lceil a - 1/2\rceil$$
3. In both cases, the size of the keylist is at least $$a -1$$.

But there’s another problem.. What happens if the parent node becomes over-filled after one of its children is split? Umm.. no big deal. Just perform split on the parent node then. So, during insertion, in the worst case, you might have to perform a split at **every** node on the root-to-leaf path on the way back from the recursive call. But all split operations take $$O(1)$$ time (essentially its something like a rotation - just moving some pointers here and there and so the total time of insertion remains $$O(logn)$$).

What about when the root is overpopulated? How do you split the root?

1. Follow the same procedure as before
2. Instead of elevating split key $$v\_m$$ to the parent (there’s no parent for root), make it the new root! (This is exactly why we allow the root to have 1 key and there’s no minimum condition on the number of keys in the root)

In other words, if $$z$$ was the old root that become overpopulated, then the following steps explain how to split a root node:

1. Pick the median key $$v\_m$$ as the split key
2. Split $$z$$ into LHS and RHS using $$v\_m$$
3. Create a new node $$y$$
4. Move LHS split from $$z$$ to $$y$$
5. Create a new empty node $$r$$
6. Insert $$v\_m$$ to $$r$$
7. Promote $$r$$ to be the new root node
8. Assign $$y$$ and $$z$$ to be the left and right child of
9. Assign previous subtree $$t\_m$$ associated with $$v\_m$$ to be the final child of $$y$$

Will the split operation ever violate rule 3?

No! A split on node $$z$$ will create a new node $$y$$ so:

* If $$z$$ is an internal node, $$y$$ will be at the same level and nothing will be pushed down since $$y$$ was split from $$z$$
* If $$z$$ is a leaf node, $$y$$ will also be a leaf node at the same level
* If $$z$$ is the root node, everything will be pushed down 1 level since a new root is created above (maintaing the invariant that all leaf nodes are at the same depth).

**Unlike BSTs which grows the leaves downwards,** $$(a,b)$$**-trees grows the root upwards! Therefore, leaves are always guaranteed to be on the same level as one another.**

It should be pretty clear that the **cost of insertion into an** $$(a,b)$$**-tree with** $$n$$ **nodes is** $$O(logn)$$ **and the number of split operations that need to be performed during insertion is also** $$O(logn)$$**.**

## Deletion

We only explain deleting keys from leaves here. To delete a key from an internal node, swap with its successor, and then delete it off.

We first find the key. Then delete it from the keylist. But wait... what if the number of keys in the node falls below $$a - 1$$?

Deletion may cause internal nodes to shrink too small (and hence, violate rule 1).

**Idea: Join with an adjacent sibling!**

### Merge Operation

Let us explain this with an example. Consider a $$(2,4)$$-tree in which you wanted to delete the element with key = 30. That would go as follows:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FAgTrsfxZ2fHMSbnugGI6%2FScreenshot_2022-03-06_at_8.41.13_PM.png?alt=media&amp;token=9cf6a900-9421-4569-afad-c587d0e19ba3" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FhiEIksIgwiPC66I63noH%2FScreenshot_2022-03-06_at_8.41.37_PM.png?alt=media&amp;token=7933e948-522d-4f97-8146-bdfb55ce5582" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FAFR1O7GjalgZWss2BQnq%2FScreenshot_2022-03-06_at_8.41.53_PM.png?alt=media&amp;token=71c84c4c-db83-46f2-9579-31c2bf467425" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FgEPE69vCIeq0UhhORoWR%2FScreenshot_2022-03-06_at_8.42.05_PM.png?alt=media&amp;token=26eb5902-cdd0-455c-974b-4f1afae16c46" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FrHc7sfjozQwEBTAVNZrr%2FScreenshot_2022-03-06_at_8.42.30_PM.png?alt=media&amp;token=01d3669a-0ff7-4fe0-ab21-b04d99565389" alt=""><figcaption></figcaption></figure>

`Merge` is intuitively the reverse operation of `split`.

In `split`, we **promote** the median key to form LHS and RHS nodes. In `merge`, we **demote** the key in parent separating LHS and RHS to join them together.

Why can’t we just join the 2 children directly? Why do we need to bring down 1 key from the parent?

For the same reason as `split`. After merging, the parent will have 1 less child than before, therefore, it must have one less key than before. Moving that key into the newly merged node is convenient

Can a merged node be too large such that it violates rule 1?

Yes, but that is not a problem because then we can perform the `split` operation on that node to make it normal. FYI, when `merge` is followed by `split`, we call that a `share` operation. That is, `share` = `merge` + `split`. In summary,

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FBQW6Lgxy3I08piHyFApe%2FScreenshot_2022-03-06_at_8.47.34_PM.png?alt=media&amp;token=5086e75b-11a8-4393-86bf-2453cf0c61fb" alt=""><figcaption></figcaption></figure>

<mark style="background-color:red;">What about deleting a key from an internal node or root?</mark>

Think about AVL trees. Swap the key to be deleted off with its predecessor/successor **which will be in a leaf node (this is critical since we are explaining only deleting keys from leaf nodes, it would be a huge problem if the successor/predecessor of a key in an internal node was not in a leaf node since our algorithm wouldn’t be able to delete keys from internal nodes then)**. The predecessor would be the right-most key in the left subtree and the successor would be the left-most key in the right subtree.

### Handling Duplicates

Instead of just storing keys, store a pair of (key, insertion order) where insertion order refers to the order when said key is inserted (e.g. timestamp)

## Why B-Trees over BST?

Both B-trees and BST have $$O(logn)$$ time for search, insert and delete operations. Then why do we need to learn about B-trees when we can use BSTs anyway?

In general, data is stored on disk in blocks, e.g. $$B\_1, B\_2, \dots, B\_m$$. Each block stores a chunk of memory of size $$B$$. (Think of each block as an array of size $$B$$). When accessing a memory location in some block $$B\_j$$, the entire block is read into memory. You can assume that your memory can hold some $$M$$ blocks at a time.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2F7eV3Qbn5Su8jW4VLUDvD%2FScreenshot_2022-03-06_at_9.09.41_PM.png?alt=media&amp;token=e36a1cd0-6f81-49fd-b07e-349add1e01b4" alt=""><figcaption></figcaption></figure>

<mark style="background-color:red;">If you had an array of length</mark> $$n$$ <mark style="background-color:red;">how many blocks would you need to transfer to the memory to do a linear search for an element?</mark>

Ans: $$n/B$$ (since $$B$$ is the amount of data in any 1 block - let’s say that each element takes up 1 unit of data)

<mark style="background-color:red;">What about doing a binary search on an array of length</mark> $$n$$<mark style="background-color:red;">?</mark>

Ans: $$log(n/B)$$ block transfers. Think of this as doing a binary search on $$n/B$$ blocks. Once your search finds the right block, it is loaded into memory and the rest of the search is free.

<mark style="background-color:red;">Now imagine you are storing your data in a</mark> $$B$$<mark style="background-color:red;">-tree (Notice that you might choose</mark> $$a = B/2, b =B$$ <mark style="background-color:red;">depending on how you want to optimize). Notice that each node in your B-tree can be stored in</mark> $$O(1)$$ <mark style="background-color:red;">blocks. For example, one block stores the key list, one block stores the subtree links and one block stores the other information (e.g. parent pointer, auxiliary information, etc.) Now what is the cost of searching a keylist in a B-tree node? What is the cost of splitting a B-tree node? What is the cost or merging or sharing a B-tree node?</mark>

Ans: $$O(1)$$!!! Since after you load the block in memory, everything happens soo fast that the time taken for that is negligible compared to accessing data stored in disk.

<mark style="background-color:red;">So, what is the overall cost of searching a</mark> $$B$$<mark style="background-color:red;">-tree? Wht is the cost of inserting or deleting in a</mark> $$B$$<mark style="background-color:red;">-tree? (here</mark> $$B$$ <mark style="background-color:red;">refers to the block size)</mark>

Ans: $$O(log\_Bn)$$, i.e., the cost only depends on the height of the tree, since each of the operations to access a single node is only cost $$O(1)$$. The important thing here is in the value of $$B$$. Searching in a BST is $$O(log\_2n)$$ while searching in a $$B$$-tree is $$O(log\_Bn)$$. In practice, $$B$$ is a pretty large number. For instance, if your disk has 16KB blocks (which is reasonably normal) and you set $$B = 16k$$, then given a 10TB database, your $$B$$-tree just requires 3 levels. The root of your B-tree will always stay in memory. For typical memory sizes (e.g. 256MB disk cache), the first level of your B-tree will also always be in memory. Thus, the cost of searching your 10TB database is typically one block transfer. For a 1000TB disk, you have 4 levels and 2 block transfers. That’s why its really hard to beat a well-implemented B-tree.


# (k, d)-Trees

### (k,d)-Trees

A kd-tree is another simple way to store geometric data in a tree (very useful for finding nearest neighbour problems). Let’s think about 2-dimensional data points, i.e., points (x,y) in the plane. The basic idea behind a kd-tree is that each node represents a rectangle of the plane. A node has two children which divide the rectangle into two pieces, either vertically or horizontally. For example, some node v in the tree may split the space vertically around the line x = 10: all the points with x-coordinates ≤ 10 go to the left child, and all the points with x-coordinates > 10 go to the right child.

Typically, a kd-tree will alternate splitting the space horizontally and vertically. For example, nodes at even levels split the space vertically and nodes at odd levels split the space horizon-tally. This helps to ensure that the data is well divided, no matter which dimension is more important. All the points are stored at the leaves. When you have a region with only one node, instead of dividing further, simply create a leaf.

Here is an example of a kd-tree that contains 10 points:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fk4sNs1kpyJncwEmrp1zj%2FScreenshot_2022-03-08_at_5.34.37_PM.png?alt=media&amp;token=90f2ada1-1426-41e0-99a6-5812d3224d8b" alt=""><figcaption></figcaption></figure>

<mark style="background-color:red;">How do you search for a point in a kd-tree? What is the running time?</mark>

Start at the root. At each node, there is a horizontal or a vertical split. If it is a horizontal split, then compare the x-coordinate to the split value, and branch left or right. Similarly, for a vertical split. The running time is just $$O(h)$$, the height of the tree.

<mark style="background-color:red;">You are given an (unordered) array of points. What would be a good way to build a kd-tree? Think about what would keep the tree nicely balanced. What is the running time of the construction algorithm?</mark>

Solution: Basic approach: We can think of the construction recursively. At a given node, we have a set of points, and we need to split it horizontally or vertically. (We have no choice: that depends on whether it is an even or odd level.) Therefore, you might sort the data by the x or y coordinate (depending on whether it is a horizontal or vertical split), choose the median as the split value, and then partition the points among the left and right children. The running time of this is $$O(nlog^2(n)$$), since you spend $$O(n log n)$$ at every level of the tree to do the partitioning, i.e., the recurrence is

$$
T(n)=2T(n/2) +O(n\log n)
$$

How to do better: Instead of sorting at every level, we could either (1) choose a random split key, or (2) Use QuickSelect to find the Median. Then, the partitioning step is only $$O(n)$$, and so the total cost is $$T(n) = 2T(n/2) +O(n)=O(n \log n).$$

<mark style="background-color:red;">How would you find the element with the minimum (or maximum) x-coordinate in a kd-tree? How expensive can it be, if the tree is perfectly balanced?</mark>

Solution: To find the minimum, if you are at a horizontal split, it is easy: simply recurse on the left child. But, if you are at a vertical node, you have to recurse on both children, since the minimum could be in either the top half or the bottom half. (Write out the recursive pseudocodde.) To find the running time, let’s look at the recurrence from taking two steps of the search (one horizontal and one vertical): $$T (n) = 2T (n/4) + O(1)$$. At each step down the tree, the number of points divides in half, i.e., $$n/2$$ after one step and $$n/4$$ after two steps. After two steps of the search, there are two more recursive searches to do. Solving this recurrence, you get a recursion tree that is depth $$log\_4n =$$ $$log\_2(n)/2$$, each node has cost $$O(1),$$ and there are $$O(2^{\frac{log(n)}{2}})$$ nodes in that tree (these many nodes are candidates to be considered for the minimum x-coordinate), so the total cost is $$O(2^{log\_2n^{1/2}}) = O(\sqrt{n})$$


# Heap

The purpose of a heap is to perform `extractMin`/`extractMax`, `deleteMin`/`deleteMax`, and `peek`.

You cannot search for an element efficiently in a heap, i.e., a **heap is NOT a search tree.**

## Representing a Binary Tree using an Array

We store each node at a position in an array. But the key question is how do we know the structure of the binary tree? (i.e., how do we find a node’s parents and children).

A common implementation is as follows:

If a node $$u$$ is at index $$i$$ of the array, then its left child is at index $$2*i$$, its right child is at index $$2*i + 1$$, and its parent is at index $$\lfloor\dfrac{i}{2}\rfloor$$.

It is easy to visualize it as follows: draw the binary tree - starting from top and moving down, add the nodes at every level in left to right order.

But if you think hard about it, you realise that this only works for a complete binary tree (if nodes to the left of current node on the same level have missing children then the current node cannot have any children). You can represent non-complete binary trees too if you put a `null` value at the index for missing nodes.

So, why don’t we use an array representation everywhere? How about an AVL tree? Just insert `null` where there is an element missing right? What’s the point in creating so many nodes and having pointers to depict parent-child relations?

Umm.. what about rotations then? Changing the parent and child relations would involving shifting a lot of elements to ensure that our parent-child relationship information is maintained correctly. It would take $$O(n)$$ in the worst case, which, needless to say, is terrible.

## Full and Complete Binary Tree

A full binary tree of height $$h$$ has $$2^{h+1} -1$$ nodes. That is, adding a node (doesn’t matter where since there is no space anywhere lol) results in the increase of the height of the tree (that’s why we call it “full” - there is no more space left).

A complete binary tree is a binary tree in which all the levels are completely filled except possibly the lowest one, which is filled from the left. A way to visualise this is to consider the array representation of a complete binary tree - it must not have any `null` values between 2 non-null values.

The height of a complete binary tree (and obviously also a full binary tree) is $$O(logn)$$ (since it is full binary tree up to height $$h -1$$). In other words, a complete binary tree is balanced.

## Min-heap

We shall discuss only about min-heap here. A max-heap is exactly analagous.

A min-heap is a complete binary tree in which a node has a value lower than that of its children (called min-heap property). Observe that this is a local property, i.e., for any node, we only need to check its left and right children and not any other node. This makes it easy to update on insertion and deletion. (Think what would happen if we had a property that depended on all other nodes in the tree, and we performed insertion - it would take $$O(n)$$ to traverse the tree. Here, we only check the nodes along the root-to-leaf path of the newly inserted node)

**Invariant:** Formally, for any node `u`, `u.value <= u.right.value && u.value <= u.left.value`. It is crucial to be able to maintain this invariant (efficiently!) on insertion and deletion.

So, the root of a min-heap has the lowest value (it follows from the above property). Due to the recursive nature of the defintion, a node has a value lower than all its descendents and higher than all its ancestors (but no relation to ancestor’s other subtree, i.e., it is possible for a node at depth $$d$$ from the root to have a larger value than a node at depth $$d + 5$$ from the root. Obviously 5 is arbitrary here.) So, the lower we go in the heap, the greater the values become. (Remember that there is no condition on the relation between values of a left and right child)

## Insertion in Min-heap

Consider a min-heap represented by the array: $$\[2,4,3,5,6]$$ (verify the parent-child relationship using the formulae described before as an exercise). Its graph representation is as follows:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FrmHfXzdxB7Nhh0XaNJpp%2FScreenshot_2022-04-05_at_4.37.26_PM.png?alt=media&amp;token=dd384779-0f9a-4b6d-8d38-417720abfb87" alt="" width="375"><figcaption></figcaption></figure>

Say now we insert the element $$1$$. We need to maintain two properties - complete BT and min-heap property. Maintaining complete BT is more important since it is a structural property, i.e., it depends on the position of the nodes in the tree. min-heap property can easily be maintained by performing swaps)

The procedure is as follows:

1. Add the element to the end of the array (this maintains the complete binary tree property as there are no gaps) (just regular insert)
2. If the heap property is violated, i.e., if the newly added node has a value lower than its parent, swap them. (maintain invariant of the min-heap)
3. Keep performing step 2 until heap property is no longer violated.

Since we perform at most $$O(\log n)$$ swaps, insertion takes $$O(\log n)$$ (since we know that the height of a heap is $$O(\log n)$$ and we are only looking at the nodes along the root-to-leaf path)

```java
insert(u, heap):
	heap.add(u); // heap property may be violated
	int index = heap.size() - 1;
	while (index >= 0 && heap.get(index) < heap.get(Math.floor(index/2)).value) { // traverse leaf-to-root path
		swap(index, Math.floor(index/2), heap); // swap with parent to correct the heap property
		index = Math.floor(index/2);
	}
```

This paradigm of insertion/deletion is quite similar to a lot of other data structures involving trees. For example, consider deletion in an AVL tree. Once we delete a node, we travel up to the root, performing rotations as necessary to ensure that our invariant (height-balance) remains true.

Notice that the element bubbles upwards from the leaf to the root (if necessary) when inserted. So, the direction of adjustment is upwards.

In case of our above example, the final heap will look like this:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fhh8y28MtynnxwgtnsiFw%2FScreenshot_2022-04-05_at_4.51.47_PM.png?alt=media&amp;token=9f4317e4-5197-4fa9-9fd5-5c43853922b7" alt="" width="375"><figcaption></figcaption></figure>

and the array representation would be $$\[1,4,2,5,6,3]$$.

## Deletion in min-Heap

You are only allowed to delete the root of the min-heap. That’s the whole point of storing the minimum at the root - so that you can pop it out. Heaps are commonly used as implementations of a priority queue and in a priority queue, you want to be able to remove the element with lowest priority (or whatever you specify as the basis for the total order).

The question is: after you delete the root, which node should become the root? A naive answer would be to pick the lower of the two children. But if the left child has lower value, then it no longer remains a complete binary tree. Remember that you need to maintain 2 key properties of a heap: it should be a complete binary tree and the invariant (min-heap property) should be satisfied

Here is the procedure (quite neat!) for deletion

1. Pop out the root from the heap
2. Make the last element of the array (the right-most node on the bottom-most level) the root (this preserves complete binary tree property)
3. Now send the root towards the leaf by swapping with the smaller of the two children if necessary (maintains invariant)

Observe that the direction of adjustment is downwards in this case (opposite to that of insertion) - we push the node from the root to the leaf.

```java
pop():
	Node root = heap.get(0);
	heap[0] = heap.get(heap.size() - 1); // make the new root to be the last element
	heap.removeIndex(heap.size() - 1); // preserves complete binary tree property
	int index = 0;
	while (index < heap.size()/2) {
		if heap.get(index).value > min(heap.get(2*index).value, heap.get(2*index + 1).value): // violation of heap property
			swap(index,heap.get(2*index).value < heap.get(2*index + 1).value ? 2*index : 2*index + 1, heap); // swap to correct
	}
```

It should be obvious by now that the time for deletion is $$O(logn)$$ since we perform at most $$logn$$ swaps while traversing the root-to-leaf path.

If you want to delete a non-root node, you can use lazy deletion. When a delete operation is performed on a vertex, just flag is at “`INVALID`”. Then, if we encounter an `INVALID` vertex on an “`extractMin`/`pop`” call, we just remove them and call `extractMin` again (until we get a valid node). This notion of labelling as `DELETED`/`INVALID` is quite popular (recall that we used a similar idea while deleting during open addressing). It ensures that our structural property remains intact (in this case, complete BT; in case of open addessing, no `null` elements between two non-`null` elements that were originally mapped to the same bucket, which would lead to `keyNotFound()` while searching error even if the key exists).

**As an aside, it is super important to be able to spot such similarities in paradigms common tips and tricks for data structures, and use them while designing your own (ingenious and creative) data structures to solve problems. Joining the dots and seeing patterns between related (or even seemingly unrelated) topics is one of the surest ways to gain an insight.**

## Heap Sort

The main purpose of a heap is to be able to get the item with the lowest value efficiently in a dynamic data structure (supports insertion, deletion). If there were no more insertions or deletions that were going to be performed, we could just sort the elements and return the lowest value in order.

But, we can use a heap to sort the elements too. Given an array and an empty heap, just insert all the elements into the heap one by one (or use `heapify` if you want it to be slightly faster) and then delete them one by one (delete gives the lowest element). The order in which elements are obtained is the sorted order.

Since both insertions and deletions take $$O(logn)$$ time, the total running time of `HeapSort` is $$O(nlogn)$$ as insertions and deletions are performed exactly $$n$$ times each (for an array of size $$n$$). Even if you use `heapify`, deleting $$n$$ elements would take $$O(nlogn)$$ and so the total running time would remain unchanged.

In fact, one cool feature is that you can use the empty space of the same array that represents the heap to store the sorted prefix of the array while you are deleting the elements. (when you delete from a heap, the last space becomes free. Put this deleted element at that position). So, it takes only $$O(1)$$ extra space. Compare this with `MergeSort` with needs $$O(n)$$ additional space to store the intermediate stages of the array.

## Heapify

Heapify is a method to create a heap from an unordered array. One way to create a heap is to perform insertions for each element. Then, the direction of adjustment is from the leaf to the root. This will take $$O(nlogn)$$. Heapify is based on a different procedure (and is faster!!!).

Given an array that represents a complete binary tree (which does not satisfy the max-heap property), we want to create a heap (say, max-heap in this case)

**We correct a single violation of the heap property in a subtree’s root at every step. So, heapify takes in an array that is a heap with only a single violation of the max-heap property.**

```python
Heapify(array, size, i)
  set i as largest
  leftChild = 2i
  rightChild = 2i + 1

  if leftChild > array[largest]
    set leftChildIndex as largest
  if rightChild > array[largest]
    set rightChildIndex as largest

  swap array[i] and array[largest]
```

```python
MaxHeap(array, size)
  loop from the first index of non-leaf node down to zero #(right to left in the array)
    call heapify
```

The precondition is that if heapify is correcting a node at index $$i$$, its left and right children are valid heaps. The postcondition is that the tree rooted at index $$i$$ is now a valid heap.

Recall that if $$u$$ is the root of a heap, `u.left` and `u.right` are also roots of heaps. The loop invariant in case of heapify is that when heapify is correcting a node at index $$i$$, all the nodes after $$i$$ are part of some correct heap. Formally, after $$k$$ iterations of `heapify`, all subtrees stemming from the last $$k$$ items in the array are valid heaps. This means that by the time we finish $$n$$ iteratoins, all nodes in the tree are by themselves valid heaps and therefore, the heap property is achieved.

We greedily build a heap using a bottom-up approach. In any complete binary tree, each node in the lowest level of the tree is a heap by itself. In the second lowest level, perform swap if necessary.

Starting from the lowest level and moving upwards (leftwards in the array), ensure that each node is part of a heap.

We are performing at most $$n$$ swaps and so the time complexity of heapify is $$O(n)$$ (think about the maximum number of swaps that can be performed for every node and sum them all up - don’t use $$O(logn)$$ since that is a lose bound)

So, the minimum time to create a heap is $$O(n)$$ using heapify. Recall that creating a heap using insertions takes $$O(nlogn)$$

An important difference is that when the direction of adjustment is upwards (bubbling the node upwards) and you start from the leaf, it takes $$O(logn)$$ swaps since you need to check all the way to the root. But when the direction of adjustment is downwards (bubling the node down) and you start at a node at height $$h$$, it takes $$O(h)$$ time.

#### Proof that time taken for heapify is $$O(n)$$:

As the maximum number of swaps needed for each node increases as we go higher up the heap, the number of nodes decreases exponentially. In particular, the number of nodes halves and the number of swaps per node increases by 1 with each level higher. So, the two effects cancel out (neutralize each other).

Consider a full binary tree of height $$h$$ and having $$n$$ nodes (obviously $$h = 2^{n} -1$$). Then, for we have $$n/2$$ leaf nodes on which no swaps need to be performed. For $$n/4$$ nodes, we need to perform only 1 swap (only 1 level below this node). For $$n/8$$ nodes, we need to perform a maximum of 2 swaps and so on.

A more rigorous proof is as follows:

Observe that max\_heapify takes $$O(1)$$ time for nodes that are one level above the leaves and in general, $$O(l)$$ time for nodes that are $$l$$ levels above the leaves. Further, above that there are $$n/4$$ nodes at level 1, $$n/8$$ nodes at level 1, $$\dots$$, 1 node at level $$logn$$.

So, the total amount of work in the for loop can be summed as:

$$
T(n) = \dfrac{n}{4}(1c)+ \dfrac{n}{8}(2c) + \dfrac{n}{16}(3c)+ \dfrac{n}{32}(4c) + \dots + 1(log(n)c)
$$

For ease of computation, set $$n/4 = 2^k$$. Then, we have

$$
T(n) = c2^k\left( \dfrac{1}{2^0} + \dfrac{2}{2^1} + \dfrac{3}{2^2} + \dots + \dfrac{k + 1}{2^k} \right)
$$

The above convergent series in the brackets is bounded by a constant (in fact, the constant is about 3 since you’re adding 1 before the series below). So, we have $$T(n) = O(2^k) = O(n)$$.

Derivation for sum of the arithmetico-geometric series:

Consider the series $$S = \sum\_{i = 0}^{\infty} \dfrac{i}{2^i}$$

$$
\begin{equation\*} \begin{split} S &= \dfrac{1}{2} + \dfrac{2}{2^2} + \dfrac{3}{2^3} + \dots \ &= \dfrac{1}{2} + \dfrac{1}{2}\left(\dfrac{2}{2} + \dfrac{3}{4} + \dfrac{4}{8} + \dots \right) \ &= \dfrac{1}{2} + \dfrac{1}{2}\left(S + \sum\_{i = 1}^{\infty}\dfrac{1}{2^i} \right) \text{ (expand the first few terms of each to verify)}\ &= \dfrac{1}{2} + \dfrac{1}{2}(S + 1) \text{ (it is a common harmonic series)} \ \dfrac{S}{2} &= 1 \ S &= 2 \end{split} \end{equation\*}
$$

Another proof of heapify time complexity:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FwwocFAg4ZEqMnMJGavpn%2FScreenshot_2022-04-16_at_9.52.43_AM.png?alt=media&amp;token=1cfa88bf-9a3c-4ae8-9e59-8588bdfeb8cb" alt=""><figcaption></figcaption></figure>

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FVXuySDVQPJ4RfVeK5p2H%2FScreenshot_2022-04-16_at_9.53.22_AM.png?alt=media&amp;token=3e59e9ee-02ae-404a-b286-ad243db68652" alt=""><figcaption></figcaption></figure>

What is the height of the subtree rooted at item $$j$$ (0-indexed)?

Full height of tree = $$log\_2n$$.

Levels above subtree at $$j$$: $$log\_2(j+1)$$

Height of subtree rooted at $$j$$: $$log\_2n - log\_2(j+1) = log\_2(\dfrac{n}{j+1})$$

So, what is the maximum number of comparisons heapify requires on a subheap rooted at index $$j$$? $$log\_2(\dfrac{n}{j+1}) + 1 \leq O(log\dfrac{n}{j})$$ : For every vertex touched during the `bubbleDown` routine, $$O(1)$$ comparisons are needed. This includes the leaves. So, another analysis of heapify yields:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FirHfJtAgDpbNE42iGCTk%2FScreenshot_2022-04-16_at_9.57.57_AM.png?alt=media&amp;token=2bf01739-2e5e-4ab3-ae5c-3725d8352f49" alt=""><figcaption></figcaption></figure>

#### Heap vs AVL Tree

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2F7VWfXrTV8GPEFQVBQMDK%2FScreenshot_2022-04-16_at_9.59.12_AM.png?alt=media&amp;token=57d161e0-111a-45e7-99a6-57e8ea1ac3aa" alt=""><figcaption></figcaption></figure>

The advantage of using an AVL is numerous: not only can it serve as both a max PQ and min PQ at the same time, it also supports searching, predecessor and successor queries. A heap is not without its merits too: it has similar asymptotic costs for standard PQ operations, has faster real costs (no constant factors), is simpler to implement and enjoys slightly better concurrency.

Which implementation is preferred clearly depends on the problem context: what is the most frequent operation? Do we start off with a list of priorities or do they come in one at a time etc.


# Introduction

## Terminology

A graph consists of 2 types of elements - nodes (vertices) and edges (arcs).

Except an empty graph (which consists of no nodes and no edges), every graph must have at least 1 node.

Each edge connects 2 nodes in a graph. Each edge is unique, i.e., there cannot be 2 edges between the same pair of nodes. In this definition, we also disallow self-loops (an edge from a node to itself)

A **multigraph** can consist of multiple edges between the same pair of nodes. In this module, we do not consider multigraph to be a type of graph.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fhmx1N6clfpZMRaHzJb7z%2FScreenshot_2022-03-17_at_12.45.17_PM.png?alt=media&amp;token=5962773a-2a71-427d-9fea-9a3e1480cb09" alt="" width="375"><figcaption></figcaption></figure>

A **hypergraph** is a graph in which each edge can connect more than 2 nodes but each edge is unique. We don’t consider a hypergraph to be a type of graph in this module.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FLkgI58iTlZAL7Y8YF1DK%2FScreenshot_2022-03-17_at_12.44.36_PM.png?alt=media&amp;token=b31b7f63-cb78-4307-9f3b-a406d7f0e1d8" alt="" width="375"><figcaption></figcaption></figure>

So more mathematically, we can express any graph as a set of vertices and edges, i.e., $$G = (V,E)$$ where $$|V| > 0$$ and $$E \subseteq {(v,w): v \in V, w \in V }$$. Each edge $$e = (v,w)$$ denotes that it connects nodes $$v$$ and $$w$$. For all edges $$e\_1, e\_2 \in E: e\_1 \ne e\_2$$.

A **simple path** consists of at least 2 nodes and intersects each node at most once. That is, a node cannot be in a path more than one time. A path can be described in terms of the nodes, which indicates the order in which the nodes were visited.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FfrtDsf106VRE4ohkShHN%2FScreenshot_2022-03-17_at_12.50.43_PM.png?alt=media&amp;token=65242cde-c295-4868-ba8c-fcab265e8e19" alt="" width="375"><figcaption></figcaption></figure>

2 nodes are said to be **connected** if there is a path between them. The graph is said to be connected if every pair of nodes is connected.

If a graph is not connected, it is said to be disconnected. A disconnected graph has multilpe connected components.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fs0B55Ctisq9PortW8GHS%2FScreenshot_2022-03-17_at_12.52.48_PM.png?alt=media&amp;token=8a0822a2-29ef-4fae-8bf6-ca33491a8587" alt="" width="375"><figcaption></figcaption></figure>

A **simple** **cycle** is a “path” (well, not actually because one node appears twice) that starts and ends at the same node. A cycle must have more than 2 nodes and cannot contain repeated edges.

A **(unrooted) tree** is simply a connected graph with no cycles.

Some important properties of a tree:

1. **A tree with** $$n$$ **nodes has** $$n-1$$ **edges.**
2. **There is a unique path between any two nodes of a tree.**
3. **Adding an edge between any two nodes of a tree creates a cycle**

A **forest** is a graph with no cycles.

The **degree** of a node is the number of adjacent edges. The degree of the graph is the maximum degree of any node in the graph.

The **diameter** of a graph is the maximum distance between any pair of nodes, following the shortest path. In other words, diameter is a max-min property - it is the maximum (over all pairs of nodes) of the minimum distance between the 2 nodes. $$max(\forall u, v \quad \delta(u,v))$$ where $$\delta(u,v)$$ is the length of the shortest path between $$u$$ and $$v$$.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FfggQJJSzhjE82kvwTlTn%2FScreenshot_2022-03-17_at_12.57.47_PM.png?alt=media&amp;token=59297f0b-dd56-460e-aefb-3554f7b5972d" alt="" width="375"><figcaption></figcaption></figure>

We define a **sparse** graph when $$E = O(V)$$ and a **dense** graph when $$E = O(V^2)$$.

There are some special kinds of graphs as follows:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2F9iUCUH0sPkqplumBdQXr%2FScreenshot_2022-03-17_at_12.58.12_PM.png?alt=media&amp;token=79391fa2-1167-4239-a34d-21af455dee67" alt="" width="375"><figcaption></figcaption></figure>

A **clique** is a **complete graph** (denoted by $$K\_n$$ where $$n$$ is the number of nodes) - there exists an edge between any pair of nodes. So, there are $$\dbinom{n}{2} = \dfrac{n(n-1)}{2}$$ edges. The degree of each node is $$n - 1$$, the diameter of the graph is $$1$$.

A **line** (or path) is a graph in which the nodes are arranged like a line. The diameter is $$n - 1$$ and the degree is $$2$$.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FFh0BpM9P9DgVeEYk9DLD%2FScreenshot_2022-03-17_at_1.01.08_PM.png?alt=media&amp;token=03dd452c-5f80-46c1-9580-6e94249fcf97" alt="" width="375"><figcaption></figcaption></figure>

A **cycle** is a graph in which all the nodes form a cycle. The degree of the graph is $$2$$ and the diameter is $$\lfloor \frac{n}{2} \rfloor$$.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FvBkBAhhS5bocqu6LypDt%2FScreenshot_2022-03-17_at_1.02.39_PM.png?alt=media&amp;token=1c4f0e2a-dae8-4164-b917-ff78da1ae7ed" alt="" width="375"><figcaption></figcaption></figure>

A **bipartite** **graph** is a graph whose set of nodes can be divides into 2 sets such that there is no edge connecting 2 nodes from the same set. Informally, a graph is bipartite if is possible to “colour” nodes using only 2 colours such that no 2 adjacent nodes have the same colour.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FQYZJJtB1ssROC9PMSEYd%2FScreenshot_2022-03-17_at_1.04.31_PM.png?alt=media&amp;token=f87008c8-08d9-44dd-8c6a-68fb114c7d41" alt="" width="375"><figcaption></figcaption></figure>

It is not always obvious to determine whether a graph is bipartite or not but the following theorem helps: **A graph is bipartite if, and only if, it does not contain any odd-length cycles.**

A graph is said to be planar if we can draw it on a 2-D surface like paper without any intersecting edges. It is not always easy to determine whether a graph is planar. But using the “map 4-colouring theorem” we know that if we can colour all the nodes of a graph using at most 4 colours such that no 2 adjacent nodes have the same colour, it must be planar. Another theorem is **Kuratowski’s** **theorem**: **A finite graph is planar if, and only if, it does not contain a subgraph that is a subdivision of the complete graph** $$K\_5$$ **or the complete bipartite graph** $$K\_{3,3}$$**.**

A planar graph with n nodes has a maximum of 3n - 6 edges. This should intuitively make some sense because there cannot be too many edges without intersecting.

A **complete bipartite graph** is a bipartite graph on two disjoint sets $$U$$ and $$V$$ such that every vertex in $$U$$ connects to every vertex in $$V$$. If $$|U| = m$$ and $$|V| = n$$, the complete bipartite graph is denoted as $$K\_{m,n}$$.

A graph *H* is said to be a **subgraph** of graph *G* iff every vertex in *H* is also a vertex in *H*, every edge in *H* is also an edge in *G*, and every edge in *H* has the same endpoints as it has in *G*.

**Handshake Theorem: If the vertices of** $$G$$ **are** $$v\_1, v\_2, \dots, v\_n$$**, where** $$n \geq 0$$**, then the total degree of the graph =** $$\sum\_{i=1}^{n}deg(v\_i) = 2 \times ($$**the number of edges in** $$G)$$**.**

A corollary of the above theorem is that the total degree of the graph is always even. It also follows that in any graph, there are an even number (possibly 0) of nodes with odd degree.

A **walk** from $$v$$ to $$w$$ is a finite alternating sequence of adjacent vertices and edges of $$G$$. The number of edges is the length of the walk.

A **trail** from $$v$$ to $$w$$ is a walk from $$v$$ to $$w$$ that does not contain any repeated edge.

A **path** from $$v$$ to $$w$$ is a trail that does not contain a repeated vertex.

A **closed walk** is a walk that starts and ends at the same vertex.

**Connected Component:** A graph $$H$$ is a connected component of $$G$$ iff:

1. $$H$$ is a subgraph of $$G$$.
2. $$H$$ is connected.
3. No connected subgraph of $$G$$ has $$H$$ as a subgraph and contains vertices or edges that are not in $$H$$.

Let $$G$$ be a graph. An **Euler circuit** for $$G$$ is a circuit that contains every vertex and every edge of $$G$$. An **Eulerian graph** is a graph that contains an Euler circuit. If a graph has an Euler circuit, then every vertex of the graph has positive even degree.

In fact, If a graph $$G$$ is connected and the degree of every vertex of $$G$$ is a positive even integer, then $$G$$ has an Euler circuit. Further, we can make a stronger claim: A graph $$G$$ \*\*has an Euler circuit iff $$G$$ is connected and every vertex of $$G$$ **has positive even degree.**

Given a graph $$G$$, a **Hamiltonian circuit** for $$G$$ is a simple circuit/cycle that includes every vertex of $$G$$. (That is, every vertex appears exactly once, except for the first and the last, which are the same.) A **Hamiltonian graph** (also called **Hamilton graph**) is a graph that contains a Hamiltonian circuit.

If a graph $$G$$ has a Hamiltonian circuit, then $$G$$ has a subgraph $$H$$ with the following properties:

1. $$H$$ contains every vertex of $$G$$.
2. $$H$$ is connected.
3. $$H$$ has the same number of edges as vertices.
4. Every vertex of $$H$$ has degree 2.

In general, the problem of finding a hamiltonian circuit or proving that none exists is an NP-hard problem (which might seem a little surprising since finding an euler circuit is pretty simple and the two problems appear quite similar).

Let $$G$$ be an undirected graph with ordered vertices $$v\_1, v\_2, \dots, v\_n$$. The adjacency matrix of $$G$$ is the $$n \times n$$ matrix $$A = (a\_{i,j})$$ over the set of non-negative integers such that: $$a\_{i,j} =$$ the number of edges connecting $$v\_i$$ and $$v\_j$$ for all $$i,j = 1,2, \dots, n$$. In this module, $$A\[i]\[j] = \begin{cases}1, \text{ if there exists an edge between node i and j} \ 0, \text{ otherwise}\end{cases}$$

The adjacency matrix of an undirected graph is symmetric, i.e., $$a\_{i,j} = a\_{j,i}$$ for all $$i,j$$.

If $$G$$ is a graph with adjacency matrix $$A$$, then for each positive integer $$m$$ and for all integers $$i,j = 1, 2, \dots, n$$ where $$n$$ is the number of vertices, then the $$i,j$$ entry of $$A^m$$ gives the number of walks of length $$m$$ from vertex $$i$$ to vertex $$j$$. In particular, $$A^m\[i]\[j] > 0 \implies \text{ there exists a path of length m from node i to node j}$$.

**Euler’s formula**: For a connected planar simple (multiple edges between nodes are not allowed) graph $$\*G = (V, E)$$\* with $$*e = |E|*$$ and $$*v = |V|*$$, if we let $$\*f$$\* be the number of faces (including the outer area), then $$f = e - v + 2$$.

## Modelling

When we use graphs to model real world problems we need to make the following decisions:

1. What do our nodes represent? generally, nodes represent the possible states of a problem.
2. What do our edges represent? generally, edges represent the transition between two states in a problem
3. Are the edges directed or undirected? (If directed, what does the direction represent)
4. Are the edges weighted or unweighted? (If weighted, what does the edge weight represent?)
5. Should you use an adjancecy matrix or adjacency list (or an edge list too!) representation?
6. What are you trying to find in the graph? (e.g. shortest path, longest path, minimum vertex cover, maximum independent set, minimum spanning tree, topological sort, SCCs, )
7. Which algorithm will work for our problem? Do we need to modify the algorithm in any way?
8. Do we need to store any additional information at each node (i.e., augment our graph) to help us get the answer?

It is always **important to understand why the algorithm works - why does it give the correct output?** For example, why does running Dijkstra give us the shortest path from a node to all other nodes? Which key property (read Invariant!) is obeyed throughout the algorithm?

For example, if we consider the facebook network - we can let each user represent a node and each “friendship” represent an edge.

Similarly, for puzzles we can let each state of the puzzle be a node and each of the adjacent states (reachable within 1 move) to be its adjacent nodes. I other words, an edge represents a move. This is particularly useful for puzzles like rubicks cube.

What is the diameter of an ($$n \times n \times n)$$ cube? $$\theta \left(\dfrac{n^2}{logn}\right)$$

## Representation

There are 2 popular ways to represent a graph to solve problems

1. Adjacency List
2. Adjacency Matrix

(Another common way is to use an edge list: simply a list of triplets $$(u,v,w)$$ which indicates that there is an edge of weight $$w$$ from node $$u$$ to node $$v$$.)

### Adjacency List

It consists of nodes stored in an array and a linked list for every node that stores all its neighbours.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Ft4gAP620DRUGFbQvPQ1I%2FScreenshot_2022-03-23_at_1.46.14_PM.png?alt=media&amp;token=8576465d-12fc-4486-a834-bb5de92bebf9" alt="" width="375"><figcaption></figcaption></figure>

In the above representation, we can see that e and f are adjacent to a while b is not adjacent to a.

Space consumption: $$|V|$$ for the array. $$2|E|$$ since each edge appears twice - once et each entry of the endpoints. Total: $$O(V + E)$$

E.g. For a cycle, each vertex has exactly 2 edges and so, the space consumed is $$O(V)$$

### Adjacency Matrix

In an adjacency matrix, the $$i,j$$ entry denotes whether or not there is an edge between node $$i$$ and node $$j$$. That is, $$A\[v]\[w] = 1 \iff (v,w) \in E$$, where $$A$$ denotes the adjacency matrix of the graph whose edge set is $$E.$$

If the graph is undirected, its adjacency matrix is symmetric.

If the adjacency matrix of a graph is $$A$$, then $$A^k$$ represents the matrix in which each entry denotes the number of walks of length $$k$$ from node $$i$$ to node $$j$$.

The size of the matrix is $$V \times V$$ and so, the space consumption is also $$O(V^2)$$ for all kinds of graphs (including cycles)

As a basic rule of thumb, if the graph is dense, it is better to use an adjacency matrix (since you won’t be wasting a lot of space) and to use an adjacency list when the graph is sparse (very few edges).

#### Trade-offs

1. Adjacency matrix is fast at answering queries related to: “is there an edge between 2 nodes?”. Adjacency list takes longer.
2. Adjacency list is fast for “enumerating all the neighbours of a node” while adjacency matrix is slower.
3. Adjacency list is also fast for a “find me any neighbour of a given node” query.

Generally, if you use an adjacency matrix for an algorithm, you will probably need to visit all $$O(V^2)$$ elements of the matrix to “travel all edges”. So, it might be better to use an adjacency list in such a case since it would take $$O(V+E)$$ which might be less than $$O(V^2)$$ if the graph is sparse.

## Tips and Tricks

{% hint style="info" %}
Read this section after you've learnt (almost) all the graph-related algorithms.
{% endhint %}

There are some common patterns / themes in how real-world problems are solved using graphs, and they're often natural optimisations to&#x20;

1. Instead of running an algorithm (e.g. Dijkstra) from multiple different nodes, think if you can create a dummy node (super-source) that connects to all the sources you want to run your algorithm from.
2. If you want to find the shortest distance **from** every node to a particular destination node, you don’t need to run Dijkstra from all the nodes! Just reverse the edges, and run Dijkstra from the destination node to get the distance between each node and the destination.
3. When you want to maximize the sum of weights, think if you can negate the edge weights and use a minimisation algorithm.
4. If you want to maximize the path length where length is defined as the product of edge weights and your products are guaranteed to be between $$0$$ and $$1$$ (say, probabilities), you can take negative logarithm of each edge weight and use regular shortest path algorithms. Realize that maximising the $$f(x)$$ is equivalent to maximizing $$logf(x)$$ since $$log$$ is a monotonically increasing function.
5. A common theme of graph problems is to duplicate the graph or transform the graph in some way to get certain desirable properties (e.g. remove cycles from the graph). Think if transforming a graph helps solve your problem. For example, creating multiple copies of each node to represent different "states" of your problem.&#x20;
6. Whenever you transform the graph, make sure each node captures all the properties of the state that you need to determine which nodes you can visit from the current node. **Traversing an edge** $$(u,v)$$ **should not depend on the path used to get to** $$u$$**.** $$u$$ itself must capture all the information necessary to determine this! So, storing stuff like number of hops travelled so far is generally not a good idea. Instead store stuff like “minimum number of hops to get from $$u$$ to the destination” or “minimum superpowers needed to solve the maze” (if superpowers are being used to break walls in the maze). **Edges must be deterministic! No if-statements should be used to decide whether an edge is valid or not!**


# BFS and DFS

## BFS (Breadth First Search)

* Very simple yet important algorithm for traversing a graph and all its nodes.
* Start from a node - visit all its neighbours. Then, for each of the neighbours, visit all its neighbours, and so on.
* A BFS traversal covers all nodes and all edges (however, it is important to remember that it does **not** travel all paths between 2 nodes! **There can be an exponential number of paths between any two nodes** (even in a DAG) and so visiting all paths between two nodes necessarily takes exponential time! It is, nearly always, a terrible idea to brute force all paths between two nodes to determine some property.)
* **BFS gives you the shortest path from one node to all other nodes (i.e., SSSP) for an unweighted graph** (directed is allowed).
* All the edges in the parent BFS form a tree (since you don’t visit repeated vertices) - this is called a BFS tree. The order in which the edges are inserted into this BFS tree while running BFS is known as the BFS order of edges (with a given starting node).
* The edges not included in the BFS algorithm (not travelled by) are called **cross-edges.**
* Running time: $$O(V + E)$$ (explained later)

```java
// Pseudocode - high level overview

frontier = {s}
	while frontier is not empty:
		next-frontier = {}
		for each node u in the frontier:
			for each edge (u,v) in the graph:
				if v is not marked visited, add v to next-frontier mark v as visited.
		frontier = next-frontier
```

```java
BFS(Node[] nodeList, int startId) {
	boolean[] visited = new boolean[nodeList.length];
	Arrays.fill(visited, false);
	int[] parent = new int[nodelist.length];
  Arrays.fill(parent, -1);
	Collection<Integer> frontier = new Collection<Integer>;
	frontier.add(startId);

	while (!frontier.isEmpty()){
		Collection<Integer> nextFrontier = new ... ;
		for (Integer v : frontier) {
			for (Integer w : nodeList[v].nbrList) {
				if (!visited[w]) {
					visited[w] = true;
					parent[w] = v;
					nextFrontier.add(w);
				}
			}
		}
		frontier = nextFrontier;
	}
}
```

Why is the running time $$O(V + E)$$ and not $$O(VE)$$?

$$O(VE)$$ is a very loose upper bound (obtained by simply looking at the two for loops and thinking: we visit each node once and for each node, we look at all its outgoing edges, which can be $$E$$ (this itself should raise your suspicions). Hence, $$O(VE)$$). On careful analysis of the algorithm above, we observe that every statement can be associated with either a vertex or an edge. In particular, each vertex is only a part of 1 frontier and so the number of times that we repeat the statements within the while loop is at most $$V$$. Moreover, the total number of edges is $$E$$ and we only check each edge exactly once. So, even though it appears to have 2 nested for-loops, the running time is $$O(V+E)$$ because some frontiers are small, others are big. Some nodes have high degree, others have a low degree. Thinking from a higher level of abstraction, we know that BFS visits each node exactly once and each edge exactly once. So, the running time should be $$O(V+E)$$

Moreover, it is important to note that the running time of BFS is $$O(V+E)$$ when we are using an **adjacency list**. If we decide to use an adjacency matrix, it takes us $$O(V)$$ time to enumerate all the neighbours of a node. Since, we need to do this for every node, we end up with a $$O(V^2)$$ BFS algorithm. Think of it this way: for each node, you need to look at all the entries corresponding to its row (recall that $$A\[u]$$ will give a row of $$V$$ numbers, with $$0$$ indicating an absence of an edge and $$1$$ indicating its presence). You need to do this for each node. So, you look at each element of the adjacency matrix once, resulting in an $$O(V^2)$$ algorithm.

If a graph is disconnected, you need to start BFS again from another node to cover the remaining nodes that have not yet been visited.

Note that BFS can only solve shortest path problems for unweighted graphs (or when all the weights are the same)

#### DFS (Depth First Search)

* Follow a path until you get stuck
* Backtrack until you find a new edge (a node that was not fully explored yet)
* Recursively explore it.
* Be careful to not repeat a vertex

Note: **DFS does not give you the shortest path from one vertex to another (for a general graph, even if it is unweighted and undirected).**

But if you think about it, **DFS can be used to give the shortest path from a node to another node in an unweighted tree** (since there is only one path between any two nodes anyway and DFS can find that path. With little modification, we can store the “depth” of DFS currently being run to determine the length of the path between a node to another node in an unweighted tree)

* All the parent edges in the DFS form a tree (since you don’t visit repeated vertices) - this forms a DFS tree.

**pre-order DFS**: add node to a list/array the first time you see it (when you start exploring it)

**post-order DFS**: add node to a list/array once you have explored it completely (i.e., all its outgoing edges have been explored)

```java
// DFS is ridiculuously simply to code!
DFS(Node[] nodeList){
	boolean[] visited = new boolean[nodeList.length];
	Arrays.fill(visited, false);
	for (start = i; start<nodeList.length; start++) {
		if (!visited[start]){
			visited[start] = true;
			DFS-visit(nodeList, visited, start);
		}
	}
}

DFS-visit(Node[] nodeList, boolean[] visited, int startId){
	for (Integer v : nodeList[startId].nbrList) {
		if (!visited[v]) {
			visited[v] = true;
			DFS-visit(nodeList, visited, v);
		}
	}
}
```

The running time of DFS is also $$O(V+E)$$. Again, it should be obvious that `DFS-visit` is called on each node exactly once - for every call, we enumerate its neighbours. In total, we enumerate all edges twice (number of neighbours enumerated = number of edges), once at each end-point of the edge. Hence, $$O(V+E)$$.

Similar to BFS, this is only true if we use an adjacency list. If we use an adjacency matrix, it takes us $$O(V)$$ to enumerate all edges for **every** node (not in total!). So, the running time using an adjacency matrix would be $$O(V^2)$$

#### General Graph Search

Actually, if we think from a high level, both BFS and DFS are exactly the same algorithm. They just use a different data structure to store the current nodes being visited. In particular, BFS uses a queue while DFS uses a stack.

```java
BFS(s):
	Queue.enqueue(s)
	while Queue is not empty:
		u = Queue.dequeue() // mark as visited here
		for each edge (u,v) in the graph:
			if v has not yet been visited, add Queue.enqueue(v) // or mark as visited here

DFS(s):
	Stack.push(s)
	while Stack is not empty:
		u = Stack.pop()
		for each edge (u,v) in the graph:
			if v has not yet been visited, add Stack.push(v)
```

It is very important to remember what BFS and DFS do: they visit every node, they visit every edge, but they DO NOT visit every path between 2 nodes.

In fact, traversing every path (even every shortest path) between two nodes takes exponential time (since there can be an exponential number (exponential in the number of nodes) of paths between two nodes)

#### Edge Classification using DFS

We can define four types of edges in a graph after performing DFS:

**Tree** edge: It is an edge which is present in the tree obtained after applying DFS on the graph. All green edges are tree edges in the graph below.

**Cross** edge: An edge connecting $$(u,v)$$ such that $$u$$ and $$v$$ have no “ancestor-descendent” relationship between them in the original graph. Cross edges are not part of the DFS tree. The edge $$(5,4)$$ is a cross edge below.

**Back** edge: It is an edge $$(u, v)$$ such that $$v$$ is ancestor of node u but the edge is not not part of DFS tree. The edge $$(6,2)$$ is a back edge in the graph below.

**Forward** edge: It is an edge $$(u, v)$$ such that $$v$$ is a descendant of $$u$$ but the edge is not not part of the DFS tree. The edge $$(1,6)$$ is a forward edge in the graph below.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FKRPlM1GVz37gKHCAc4EB%2FScreenshot_2022-04-26_at_8.39.58_AM.png?alt=media&amp;token=28c93756-569d-4c82-92fb-e9827ee7ea09" alt=""><figcaption></figcaption></figure>

Observe that an undirected graph cannot have forward edges and cross edges. Try it out yourself.

How would you identify a back edge in DFS? When you’re exploring a node, mark it as “exploring” (since it is still on the recursion stack). When you’re done exploring it entirely, mark it as “not exporing”. If while exploring a node, you reach any other node that is currently on the stack (still being explored), that edge is a back edge.

```python
dfs(v):
	v.inProcess = true # currently being explored
	visited[v] = true
	for u in v.neighbours():
		if visited[u] == false:
			dfs(u)
		elif u.inProcess == true:
				# mark (u,v) as back edge
	v.inProcess = false # out of the recursive stack
```

Another cool thing about classifying these edges is that we can use them to detect cycles: **a graph has a cycle** $$\iff$$ **the DFS of the graph has a back edge.** (pretty easy to understand)

This gives us a linear time algorithm to detect a cycle (rather than using Bellman ford or what not)

If you consider the “start” of exploration of a node as an opening parantheses $$($$ and the “completion” of exploration of a node as a closing parantheses $$)$$ then you can observe that when you run DFS you get a balanced parantheses. That is, for each closing paranthesis, its matching/corresponding paranthesis lies before it. For example, you might get something like: $$(()()(()))$$ but not like $$(()))()(()$$. This is part of the depth first nature of DFS.


# DAG and Topological Sort

## Problem

A directed graph is a graph in which the edges are unidirectional. That is, $$(u,v) \in E \implies$$ there is an edge from $$u$$ to $$v$$ (it does not say anything about a way to get from $$v$$ to $$e$$).

For each node, we define the in-degree of a node to be the number of incoming edges, and the out-degree of a node to be the number of outgoing edges.

Similar to an undirected graph, we can use an adjacency matrix or adjacency list to represent it. In case of an adjacency list, the node $$j$$ is in the linked list at index $$i$$ of the array if there is a directed edge from $$i$$ to $$j$$. That is, the linked list stores the outgoing edges of each node.

In case of a matrix, if $$A$$ is the adjacency matrix of a directed graph $$G$$, then $$A\[i]\[j] = 1 \iff (i,j) \in E$$, i.e., there is a directed edge from $$u$$ to $$v$$.

Like before, an adjacency list takes space $$O(V+ E)$$ while an adjacency matrix takes space $$O(V^2)$$

A directed acyclic graph (DAG) is a directed graph with no cycles.

One can view a directed acyclic graph as a partial order.

Recall that a partial order is a relation that is

1. Reflexive ( $$\forall x, \ (x,x) \in R$$)
2. Antisymmetric ( $$\forall x, y, \ (x,y) \in R \wedge (y,x) \in R \implies x = y$$),and
3. Transitive ( $$\forall x,y,z,\ (x,y) \in R \wedge (y,z) \in R \implies (x,z) \in R$$)

A total order is a partial order in which all the elements are comparable: $$\forall x,y, (x,y) \in R \text{ or } (y,x) \in R$$

In other words, if a partial order describes a sequence of events with dependencies such that one event should take place before another event if there is an edge from the event to the other event, then it can be represented as a DAG. It is natural to ask, then, given all the constraints on the ordering of events, is there a possible order that respects all these constraints? That is, given a partial order (the order in which the events can be performed) (in the form of a DAG), we want to find a total order (the actual order in which you will perform those events). This total order is a topological order.

It should be obvious why there cannot be a cycle - a cycle would denote a cyclic dependency and so, there is no way to perform any of the events, since you’d need to do the other one before, and the same is true for the other events in the cycle. For example, if CS1101S has CS2040S as a prerequisite and CS2040S has CS1101S as a prerequisite, there is no way (order) in which we can do the modules while respecting the prerequisites.

A topological sort of a DAG is not unique since there can be multiple total orders for a partial order. More generally, if there is a set of constraints regarding order you need to follow while performing a sequence of steps, you can still do those steps in multiple orderings.

A topological ordering of a DAG can be visually interpreted as arranging all the nodes in a horizontal line such that the edges only point forward (towards the right).

There are 2 algorithms that we can use to find a topological sort

1. Post-order DFS
2. Kahn’s algorithm

## Post-order DFS

Process each node when it is last visited. This builds up the sequential ordering of tasks backwards. Try out a few examples to convince yourself that the algorithm works. When it reaches a node with no outgoing edges (base case of DFS), the algorithm appends it to the end of the schedule. Then it backtracks to find the tasks that need to be done before that. It prepends nodes and hence, the nodes that need to be done last are put in the schedule first (and they get pushed down each time another node is prepended)

```java
DFS(Node[] nodeList){
	boolean[] visited = new boolean[nodeList.length];
	Arrays.fill(visited, false);
	for (start = i; start<nodeList.length; start++) {
		if (!visited[start]){
			visited[start] = true;
			DFS-visit(nodeList, visited, start);
			schedule.prepend(v); // add to the front of the schedule after you have done visited everything that needs to be done
													 // after that.
		}
	}
}

DFS-visit(Node[] nodeList, boolean[] visited, int startId){
	for (Integer v : nodeList[startId].nbrList) {
		if (!visited[v]) {
			visited[v] = true;
			DFS-visit(nodeList, visited, v);
			schedule.prepend(v);
		}
	}
}
```

Since this is basically DFS, it takes $$O(V+E)$$ to find a topological ordering.

## Kahn’s algorithm

Kahn’s algorithm does not use DFS. In fact, you can think of it as using a variant of BFS since it goes “level” by “level”.

Moreover, it builds the schedule starting from the first to the last (unlike Post-order DFS which builds it backwards)

Repeat until the graph is empty:

1. Find S = the set of all nodes with no incoming edges (this forms the stuff that you can directly do - put in the front of the schedule. These have no prerequisites).
2. Append all nodes in S to the the end of the schedule. (you are free to do these events now since you have done all the things you need to do before them)
3. Remove all edges adjacent to nodes in S
4. Remove nodes S from the graph (and so you move to the next level of nodes that you can freely do as their prerequisites have also been completed)

Kahn’s algorithm, like post-order DFS, also runs in $$O(V+E)$$ time. This is because, each node is processed exactly once (when it is appended to the schedule) and each edge is processed exactly once (when you are finding the edges adjacent to nodes in S to remove).

However, since nodes are being removed from the graph, you don’t need to maintain a visited array. On the other hand, you need some data structure to store the indegrees of each node (perhaps, a priority queue so you can get the node with least indegree - in fact, you need the indegree to be exactly 0)

Actually a priority queue would not be efficient. Rather we can just use an ordinary queue (or even a stack works) to store the current set of nodes with indegree 0 and an array to store the current indegree of each node. First traverse the graph to find the nodes with indegree = 0 and add them to the queue. Then each time you dequeue a node, look at all the outgoing edges and subtract 1 from it's neighbors’s indegree in the array. If the indegree becomes 0, add it to the queue. If not, move on.

It can be shown that every DAG has a node with indegree = 0 and another node with outdegree = 0. (think about what would happen if this weren’t the case - there has to be some way to start the schedule, and some node to finish at. If not, it would give rise to cycles.)

## Longest Path

Given a graph, how would we find the longest path between 2 nodes? In fact, this problem is NP-hard. There is no better solution we can come up with apart from brute force. However, for a DAG, we can use a neat trick to help us. Multiply all the edge weights by -1. Then, find shortest path using DAG\_SSSP (topological sort followed by relaxing edges). Multiply all the edge weights by -1 again and return the absolute value of the length of the shortest path we obtained.

This does not work in general because it is possible for a cycle to exist within a graph. Then, when -1 is multiplied to all weights, it may become a negative weight cycle. In such a case, shortest paths are not defined since you can keep going in loops in the cycle and get smaller and smaller distances.


# SCC (Tarjan's and Kosaraju's)

## Problem

Recall that a connected component of an undirected graph is defined as follows: $$v$$ and $$w$$ are said to be in the same connected component if, and only if, there is a path from $$v$$ to $$w$$.

But in case of directed graphs, it is possible to have a path from $$v$$ to $$w$$ but not from to $$w$$ to $$v$$. Then, how do we define connectedness?

We define a **Strongly Connected Component (SCC)** as follows:

A subgraph $$H$$ is an SCC of graph $$G$$ if

1. $$\forall v, w \in V\_H$$ there is a path from $$v$$ to $$w$$ and there is a path from $$w$$ to $$v$$. (Here $$V\_H$$ denotes the vertices in subgraph $$H$$)
2. There is no bigger subgraph of $$G$$ that contains $$H$$ as its subgraph and satisfies property (1) - In other words, the SCC should be maximally sized (as big as possible)

**Note**:

1. If a graph is “strongly connected”, it has exactly 1 strongly connected component.
2. Any DAG with $$n$$ vertices has $$n$$ strongly connected components (since there are no cycles! so, even if there is a path from $$v$$ to $$w$$, it is impossible to find a path from $$w$$ to $$v$$ due to absence of cycles)

This shows that any strongly connected component must have a cycle (or it must be an isolated node) for all its nodes to be reachable from each other.

Another cool property is that the graph of SCCs is a directed acyclic graph. In particular, when each SCC is replaced by one representative node in the graph, the resulting graph is acyclic. This is because different SCCs cannot be part of a cycle - otherwise, they could merge to form a larger SCC since all nodes would be reachable from them.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fre0gBwrqWycZDQLmMEZb%2FScreenshot_2022-03-23_at_8.15.51_PM.png?alt=media&amp;token=ccb5d26f-6186-4f74-a021-84e4680d713c" alt=""><figcaption></figcaption></figure>

There are various algorithms to find SCCs. Some of the include:

1. Kosaraju’s algorithm
2. Tarjan’s algorithm

Both these algorithms run in $$O(V+E)$$ time (though I much prefer Kosaraju's algorithm because it's more elegant).

## Kosaraju's Algorithm

It uses 2 DFS passes to determine the SCCs.

1. Run DFS from each unvisited node, and add it to a stack once you’re done processing it (i.e., store the nodes in reverse post-order manner)

   ```python
   stack = []
   visited = set()
   for i in range(n):
   	if i not in visited:
   		dfs(i)

   def dfs(node):
   	visited.add(node)
   	for v in graph[node]:
   		if v not in visited:
   			dfs(v)
   	stack.append(node)
   ```
2. Reverse all the edges of the graph

   ```python
   temp = defaultdict(list)
   for node in graph:
   	for v in graph[node]:
   		temp[v].append(node)
   grah = temp
   ```
3. Pop from stack, run dfs and assign nodes to their components if they’re not already done so. Each component is identified by its root / “leader” which is the highest node in the stack (first node in its component to be processed in this step).

   ```python
   visited = set()
   component = [-1] * n
   while stack:
   	curr = stack.pop()
   	if curr in visited: continue
   	assign(curr, curr)
   	
   def assign(node, root):
   	visited.add(node)
   	component[node] = root # node belongs to root's (leader) component
   	for v in graph[node]:
   		if v not in visited:
   			assign(v, root)
   ```

The code itself is easy to understand, but the main question is: why does this work?? What is the key invariant here??

The key intuition (and proof sketch) is as follows:

1. If `u` is above `v` in the stack, then either `u` and `v` are in the same component (so the relative ordering does not matter anyway) XOR there is NO path from `v` → `u` (i.e., exactly one of these is true).

   This must be true because if there were a path from `v` → `u` but they were not in the same component, then that means there is no path from `u` → `v`. Then, it’s impossible for `u` to finish being processed after `v`. Why??

   Because if you visit `v`, and `u` is already finished processing, then `u` is already in the stack while `v` is not → so `v` is above `u`. If `u` is not on the stack but is marked visited while you are at `v`, this means there’s a path from `u` → `v`, but this would mean that they’re in the same component (since by our hypothesis, there is also a path from `v` → `u` ). So, the only remaining case is that `u` is not visited when you arrive at `v`, and then you would reach `u` eventually via the path from `v` → `u`, finish `u` and push it to the stack before `v`.
2. Now, when we reverse the edges, the above invariant for the reversed graph becomes: If `u` is above `v` in the stack, then there is either NO path from `u` → `v`, XOR `u` and `v` are in the same component.

   Note that reversing all edges doesn’t change which nodes belong to which strongly connected component, since “strongly” implies bidirectional connectivity for any pair of nodes in the same SCC anyway.
3. This is why, in the second DFS-pass, if we start at `u` and reach `v`, it must mean that they’re in the same SCC. Why?

   Since there is a `u` → `v` path in the reversed graph (hence, `v` → `u` in the original graph), AND `u` is above `v` in the stack, the only way this can happen is if there was also a `u` → `v` path in the original graph, as we’ve shown in (1). So, there is a path from `u` → `v` as well as `v` → `u` in the original graph, and hence, they must be in the same SCC.

## Tarjan’s Algorithm

The algorithm takes a [directed graph](https://en.wikipedia.org/wiki/Directed_graph) as input, and produces a [partition](https://en.wikipedia.org/wiki/Partition_of_a_set) of the graph's [vertices](https://en.wikipedia.org/wiki/Vertex_\(graph_theory\)) into the graph's strongly connected components. Each vertex of the graph appears in exactly one of the strongly connected components. Any vertex that is not on a directed cycle forms a strongly connected component all by itself: for example, a vertex whose in-degree or out-degree is 0, or any vertex of an acyclic graph.

The basic idea of the algorithm is this: a depth-first search (DFS) begins from an arbitrary start node (and subsequent depth-first searches are conducted on any nodes that have not yet been found). As usual with depth-first search, the search visits every node of the graph exactly once, declining to revisit any node that has already been visited. Thus, the collection of search trees is a [spanning forest](https://en.wikipedia.org/wiki/Spanning_forest#Spanning_forests) of the graph. The strongly connected components will be recovered as certain subtrees of this forest. The roots of these subtrees are called the "roots" of the strongly connected components. Any node of a strongly connected component might serve as a root, if it happens to be the first node of a component that is discovered by search.

The invariant of the algorithm is this (**The Stack Invariant**):

Nodes are placed on a [stack](https://en.wikipedia.org/wiki/Stack_\(data_structure\)) in the order in which they are visited. When the depth-first search recursively visits a node `v` and its descendants, those nodes are not all necessarily popped from the stack when this recursive call returns. The crucial [invariant property](https://en.wikipedia.org/wiki/Invariant_\(computer_science\)) is that a node remains on the stack after it has been visited if and only if there exists a path in the input graph from it to some node earlier on the stack. In other words, it means that in the DFS a node would be only removed from the stack after all its connected paths have been traversed. When the DFS will backtrack it would remove the nodes on a single path and return to the root in order to start a new path.

At the end of the call that visits `v` and its descendants, we know whether `v` itself has a path to any node earlier on the stack. If so, the call returns, leaving `v` on the stack to preserve the invariant. If not, then `v` must be the root of its strongly connected component, which consists of `v` together with any nodes later on the stack than `v` (such nodes all have paths back to `v` but not to any earlier node, because if they had paths to earlier nodes then `v` would also have paths to earlier nodes which is false). The connected component rooted at `v` is then popped from the stack and returned, again preserving the invariant.

Simply put, Tarjan’s algorithm maintains a stack of valid nodes from which to update low-link values from. Nodes are added to the stack as they are explored for the first time. Nodes are removed from the stack each time a complete SCC is found. (There is no path back to the same SCC from which you are leaving - because then you can merge those nodes to form a larger SCC)

Before going into the details, we need to understand what a low-link value of a node is: the **low-link** value of a node is the smallest (lowest) node index that is reachable from that node (and on the stack) when doing a DFS (including itself).

**All nodes with the same low-link value belong to the same SCC.**

**A node started a SCC if its index is equal to its low-link value.**

Each node `v` is assigned a unique integer `v.index`, which numbers the nodes consecutively in the order in which they are discovered. It also maintains a value `v.lowlink` that represents the smallest index of any node on the stack known to be reachable from `v` through `v`'s DFS subtree, including `v` itself. Therefore `v` must be left on the stack if `v.lowlink < v.index`, whereas v must be removed as the root of a strongly connected component if `v.lowlink == v.index`. The value `v.lowlink` is computed during the depth-first search from `v`, as this finds the nodes that are reachable from `v`.

The pseudocode is as follows:

```java
algorithm tarjan is
    input: graph G = (V, E)
    output: set of strongly connected components (sets of vertices)

    index := 0
    S := empty stack
    for each v in V do
        if v.index is undefined then
            strongconnect(v)
        end if
    end for

    function strongconnect(v)
        // Set the depth index for v to the smallest unused index
        v.index := index
        v.lowlink := index
        index := index + 1
        S.push(v)
        v.onStack := true

        // Consider successors of v
        for each (v, w) in E do
            if w.index is undefined then
                // Successor w has not yet been visited; recurse on it
                strongconnect(w)
                v.lowlink := min(v.lowlink, w.lowlink)
            else if w.onStack then
                // Successor w is in stack S and hence in the current SCC
                // If w is not on stack, then (v, w) is an edge pointing to an SCC already found and must be ignored
                // Note: The next line may look odd - but is correct.
                // It says w.index not w.lowlink; that is deliberate and from the original paper
                v.lowlink := min(v.lowlink, w.index)
            end if
        end for

        // If v is a root node, pop the stack and generate an SCC
        if v.lowlink = v.index then
            start a new strongly connected component
            repeat
                w := S.pop()
                w.onStack := false
                add w to current strongly connected component
            while w ≠ v
            output the current strongly connected component
        end if
    end function
```


# SSSP (Bellman-Ford and Dijkstra)

## Problem

SSSP is a common acrnoym for Single-Source Shortest Path. This means that we are interested in trying to find the shortest path from one node in the graph (called the source) to all other nodes in the graph. There are a lot of algorithms that can solve this problem efficiently but we will discuss only 2 of them.

Firstly it is important to remember that BFS is able to find the SSSP. Then, why do we need another algorithm? Because BFS only works for unweighted graphs. BFS finds the minimum number of hops, not the minimum distance. Moreover, BFS does not explore every path in the graph (although neither do these SSSP algorithms - in fact any algorithm that tries to explore all possible paths between 2 nodes must be exponential in time).

So for weighted graphs, each edge has a weight associated with it. You can think of the weight as the cost from travelling from one node to another via that edge. In most cases, we are interested in finding the path with the shortest sum of weights. You could define shortest paths in another way (say, the lowest product of all weights, or the number of edges whose weight is greater than 5, the smallest maximum-weight-edge along the entire path, etc.).

We store the edge weights in the adjacency list too. Formally, we define a weight function $$w(e) : E \xrightarrow{} \mathbb{R}$$ as an assignment to each edge a real number.

We denote the shortest distance from $$u$$ to $$v$$ as $$\delta(u,v)$$. Our aim is to find $$\delta(u,x)$$ for all $$x \in V$$ for a given $$u$$.

The key idea for most (if not, all!) shortest path algorithms is the triangle inequality: $$\delta(S,C) \leq \delta(S,A) + \delta(A,C)$$.

This means that the shortest path from S to C cannot exceed the path length of the shortest distance from S to A + that from A to C. Because if it did, we could just go from S to C via A and we would get a shorter distance. In particular, the inequality holds trivially if A lies on the shortest path between S and C

The triangle inequality does not refer to the mathematical one in the sense that the sum of 2 sides of a triangle can be less than the third side when dealing with a graph because the weights of the graph are arbitrary. This is not a violation of the triangle inequality.

As we have to find the minimum distance, this is an optimisation problem. Optimisation problem can either be solved by brute-force (BF - Bellman Ford (also brute force lol)) or greedily (Dijkstra)

## Bellman-Ford Algorithm

BF is essentially a brute force algorithm.

We start by maintaining an estimate for each distance. Our aim is that by the end of the algorithm, all our estimates will precisely equal the actual shortest distances. (From now, we drop the prefix “shortest” and let distance refer to the shortest distance)

**Our invariant is: For every node, the estimate is always greater than or equal to the distance**

In the beginning, since we don’t know any of the distances, we mark all estimates to be infinity and the estimate of the source to be 0 (the distance from the source to itself is 0). Then, we start to “relax” the edges. Relaxation is a very important step in all shortest-path algorithms.

**In Bellman-Ford, we do not care about the order of relaxations.**

Relaxing an edge means to update the estimate of the node if we have found a shorter path to that node (using the triangle inequality)

```java
relax(int u, int v) {
	if (dist[v] > dist[u] + weight(u,v)) { // the dist[] array keeps track of our current estimates
		dist[v] = dist[u] + weight(u,v);
	}
}
// we can write it more succinctly as:
dist[v] = min(dist[v], dist[u] + weight(u,v));
```

All the above code does is this: if you found a shorter path from the source to v via u, then update the distance so that you now follow this path.

If you want to recover the shortest path too, you can keep track of the parent each time you udpate the distance.

But the key question is: is it enough to relax each edge once to find SSSP?

No! Because you are performing the relaxations in any arbitrary order, it is possible that some relaxations have no effect on updating the distances because you should have performed other relaxations before (I.e., the updation needs to propagate throughout the path) In short, the number of times you need to relax depends on the order of edges.

So, how many times do we need to relax each edge in the worst case?

Observe that the length of the longest path from the source to a node is $$V - 1$$ (think of a line, whose diameter is $$V -1$$). Obviously you wouldn't repeat vertices when trying to find the shortest path. Here, we are assuming that there are no negative cycles.

Consider finding the shortest path from the source $$S$$ to a vertex $$v$$. **Let** $$P$$ **be the shortest path from** $$S$$ **to** $$v$$**. Then, observe that after each iteration of relaxing all the edges, at least one more vertex along the path** $$P$$ **gets its correct estimate** (i.e., estimate = distance). For example, if the path $$P$$ is: $$S \xrightarrow{} A \xrightarrow{} B \xrightarrow{} C \xrightarrow{} D \xrightarrow{} v$$, after the 2nd iteration, at least both $$A$$ and $$B$$ will have the right estimates. So, since the longest possible length of a shortest path (read: diameter of the graph) is $$V - 1$$, we need to relax all the edges at most $$V -1$$ times to ensure that we have found the correct distances from the source to all other nodes.

```java
for (int i = 0; i < n - 1; i++) {
	for (Edge e : graph) {
		relax(e);
	}
}
```

But sometimes you don’t need to wait for all $$V - 1$$ iterations of relaxations? When can you terminate early?

We can terminate early if we are sure that relaxing all the edges again does not update any more distances. In particular, we can terminate early if an entire iteration of relaxing all deges have no effect on the distances.

**Running time: O(VE)**

Each edge is relaxed at most $$V$$ times (We abuse notation - the hallmark of a true computer scientist - and simply write $$V$$ instead of $$|V|$$)

But why does Bellman Ford work? Why is it able to find the shortest paths?

Firstly, notice that the shortest path from any node to any other node cannot have any loops/cycle (we deal with negative cycles soon). This is because, it is possible to eliminate that cycle and reduce the path length.

**Another key invariant is that after 1 iteration, our 1 hop estimate on the shortest path is always correct.** After $$n - 1$$ iterations, our estimates along all the nodes in the shortest path is correct. (Can be proved inductively)

**Let** $$T$$ **be a shortest path tree of graph** $$G$$ **rooted at source** $$s$$**. After iteration** $$j$$**, all nodes which are** $$j$$ **hops alway from** $$s$$ **on tree** $$T$$**, have their correct estimates equal to the shortest distance.**

**If** $$P$$ **is the shortest path from** $$S$$ **to** $$D$$**, and if** $$P$$ **goes through** $$X$$**, then** $$P$$ **is also the shortest path from** $$S$$ **to** $$X$$ **(and from** $$X$$ **to** $$D$$**). That is, a shortest path between two nodes is made up of the shortest path between all its intermediate nodes.**

This follows from the triangle inequality. If $$P$$ did not go through $$X$$, then another path $$Q$$ from $$S$$ to $$D$$ that went through $$X$$would have the shortest distance.

Does every node at 1 hop from the source have the correct shortest path after 1 iteration? No! Only those nodes which lie along the shortest path from the source to another node and are 1 hop away from the source have their correct estimates.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FaRsQMgJHY7s8xkG6Q8Pm%2FScreenshot_2022-03-26_at_10.19.07_AM.png?alt=media&amp;token=aeb48280-e21b-4ef7-b44a-acd65190fdbe" alt=""><figcaption></figcaption></figure>

This is an easy example to show that after 1 iteration, a node 1 hop away from the source need not have its correct estimate.

Does this algorithm also work for graphs with negative weights?

Yes. At no step along the way are we assuming that weights have to be positive.

BUT, shortest paths are not defined in graph with negative-weight cycles. Because, then it is possible to keep cycling through the negative cycle to lower the shortest distance and the algorithm would never converge. (In fact, it is meaningless to talk about shortest paths in such graphs)

A cool byproduct of Bellman-Ford is that it is able to detect negative cycles using this very property. We proved that for a graph with no negative cycles, the path length (not the actual distance) for any shortest path is at most $$n - 1$$. Running Bellman-Ford on the $$n^{th}$$ iteration should not affect any of our estimates (as we expect them to be correct by now). So, if we observe any updates in the estimations after $$n -1$$ iterations of relaxations, we discover that our graph has a negative cycle. Many implementations of Bellman-Ford, hence, run the algorithm for $$n$$ iterations, with the last iteration being used to check if any negative cycles are present.

If we don’t have any cycles in a graph, how would you try to find the **longest path distances** from a source node to every other node?

A really neat trick is to negate all the edge weights and then run Bellman-ford to find the shortest path. Negate all the distances to recover the actual distances. It is important that this graph be a tree (no cycles) or else after negation, we end up with (possibly) negative weight cycles. Or just use DAG\_SSSP with negated edges in $$O(V+E)$$ time.

**In BF, once the estimate of a node has been set, it can be updated multiple times throughout the** $$n-1$$ **iterations until it finally reaches the minimum distance (this is an important distinction between BF and Dijsktra). So, if we stop the BF algorithm after** $$k$$ **iterations, only the nodes whose shortest path lengths are less than or equal to** $$k$$ **hops are guaranteed to have their correct estimates.** (however note that if by luck, we relax the edges in the perfect order in the first iteration itself, all the nodes will have the correct estimate. So, we cannot make claims like “after the first $$k$$ iterations, **only** those nodes that are within $$k$$ hops from the source on the shortest path will have the correct estimates”)

**In Dijkstra, once we pop a node from the priority queue, we can be sure that its estimate will not change.** In fact, if you’re interested in finding the shortest path from a source $$u$$ to a single vertex $$v$$, you can terminate Dijkstra as soon as you pop $$v$$ from the priority queue.

## Dijkstra’s Algorithm

This is arguably one of the most commonly implemented SSSP algorithm because it runs faster than BF (Bellman Ford) and it is pretty easy to code out.

Dijkstra’s algroithm is an example of a greedy algorithm. In a greedy method, a problem should be solved in stages by making a sequence of decisions and considering one input at a time to get an optimal solution. There are prefined procedures that we use for getting an optimal solution (in this case, the SSSP).

Greedy algorithm: Make the best decision at every step and you will get the optimal solution in the end.

We saw in BF that we had to relax each edge at most $$V - 1$$ times to be sure that all our estimates were correct. We are now trying to get the shortest paths by only relaxing each edge once! First, we need to ask ourselves:

Is there always a right order to relax the edges (assuming non-negative weights) such that if we follow this correct order, we only need to relax each edge once?

Yes! A right order always exists if there is no negative weight cycles. Assume that $$T$$ is the shortest path tree of a graph $$G$$ with no negative cycles and with the root being the source $$s$$. Now if we relax the tree edges in BFS order starting from $$s$$, we will ensure that before relaxing the edges of the children, we have relaxed the edges of the parent nodes and so, the parent would have a correct estimate. We can relax non-tree edges in any order. (This proves that a right ordering exists but does not provide a useful way to find such an ordering since we don’t know the shortest path tree before running Dijkstra lmao circular dependency)

In fact, we don’t even need to go in BFS order. **We just need to ensure that before relaxing all outgoing edges of a node, all the incoming edges of the node have been relaxed. So, the order in which we relax the edges is exactly the same order in which the edges occur in the actual shortest path from the source to a node. (This works even for negative weight edges)** - But this only works for DAGs (in a general graph, there are cyclic dependencies; so you may not be able to relax any edge if you strictly follow this. Dijkstra does not use this property. Dijkstra allows you to relax a node even when there may be incoming edges that have not been relaxed because you are sure that this node’s estimate is the least it can be - you have already relaxed all the incoming edges to this node **from the nodes with lower estimate** when you relaxed those nodes. The other incoming edges arise from nodes with higher estimates and cannot lower this node’s estimate since the weight of this edge must be non-negative.

**Note that relaxing the edges of a graph in BFS order from the source would not work because we may have to relax the same edge multiple times** (and hence leads to greater time complexity) (think about why it wouldn’t work: you are assuming that lower hops $$\implies$$lower distance, which is not necessarily true)

Now that we know a correct order to relax the edges exists, we can come up with an algorithm (Dijkstra’s) to exploit this property and only relax each edge once.

(Note that in the context of Dijkstra, when we say “relax a node”, we mean “relax all the outgoing edges from the node”)

Dijkstra’s algorithm is very similar to [**Prim’s algorithm for minimum spanning tree**](https://www.geeksforgeeks.org/prims-minimum-spanning-tree-mst-greedy-algo-5/). Like Prim’s MST, we generate a *SPT (shortest path tree)* with a given source as a root. We maintain two sets, one set contains vertices included in the shortest-path tree, other set includes vertices not yet included in the shortest-path tree. At every step of the algorithm, we find a vertex that is in the other set (set of not yet included) and has a minimum distance from the source. (observe the difference between Dijkstra’s and Prims: Dijkstra stores the distance estimate of a node to the source, Prim stores distance estimate of a node to any other node already in the spanning tree set.

### Algorithm

1. Create a set *sptSet* (shortest path tree set) that keeps track of vertices included in the shortest-path tree, i.e., whose minimum distance from the source is calculated and finalized. Initially, this set is empty.
2. Assign a distance value to all vertices in the input graph. Initialize all distance values as INFINITE. Assign distance value as 0 for the source vertex so that it is picked first.
3. While *sptSet* doesn’t include all vertices
   1. Pick a vertex $$u$$ which is not there in *sptSet* and has a minimum distance value (we use a priority queue of nodes (NOT EDGES) to achieve this, prioritized by their distance).
   2. Include $$u$$ to *sptSet*
   3. Update distance value of all adjacent vertices of $$u$$. To update the distance values, iterate through all adjacent vertices. For every adjacent vertex $$v$$, if the sum of distance value of $$u$$ (from source) and weight of edge $$w(u,v)$$, is less than the distance value of v, then update the distance value of v. (In other words, relax all the outgoing edges from $$u$$.)

**Invariant**: **Once a vertex has been added to the&#x20;*****sptSet,*****&#x20;its distance always remains the same (and never reduces). That is, the&#x20;*****sptSet*****&#x20;contains the set of vertices whose shortest path distance has already been found. This is the reason why we only need to relax each edge once (no further relaxation can happen once you are sure you have found the shortest path)**

In other words, we are building the shortest paths greedily.

HOWEVER, the above invariant is true only if ALL the edges have non-negative weights. An easy example of why it wouldn’t work for a graph with negative weights is given below:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FwkFtzICyo7icvI8Wm4Oi%2FScreenshot_2022-03-28_at_3.01.05_PM.png?alt=media&amp;token=9ba3ac56-3aba-43c3-9598-9a2cf9f9c89c" alt="" width="177"><figcaption></figcaption></figure>

Let $$A$$ be the source vertex and say, we start running Dijkstra. We would first mark the distances of $$B$$ and $$C$$ as 4 and 3 respectively. Then, we would look at $$C$$. Since it has no outgoing edges, we move on. (But since we “explored” $$C$$, we don’t expect the distance of $$C$$ to change again according to our invariant). Then we look at $$B$$, update the distance of $$C$$ to be 2 since $$d\[B] + w(B,C) < d\[C]$$ (the distance of C was greater than the distance of B plus the cost of an edge from B to C).Hence, our invariant no longer holds. It is easy to see why Dijkstra would fail for graphs with negative edges (even though in this case, the final distances would be correct, it is not true in general).

Consider the following case:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FMYWiNFxLlF34zgefihUt%2FScreenshot_2022-03-28_at_3.07.19_PM.png?alt=media&amp;token=ccd04d0d-7455-4c06-8eae-ba756c58db91" alt="" width="196"><figcaption></figcaption></figure>

Run Dijkstra from $$A$$. Since $$B$$ is explored before $$D$$, the updation of distance of $$B$$ takes place while relaxing node $$D$$ (and at that step, $$B$$ will have a distance of 2) but this change is not propagated to the shortest paths containing $$B$$ as their intermediate node. In particular, the distance of $$C$$ would still remain 2 ($$A \xrightarrow{} B \xrightarrow{} C)$$ at the end of Dijkstra’s algorithm even though the correct answer would be 0 ($$A \xrightarrow{} D \xrightarrow{} B \xrightarrow{} C$$)

**This is an important distinction between BF and Dijkstra - BF can handle negative edges but Dijkstra cannot** as long as there is no negative cycle (in fact, it can even detect cycles).

### Proof of Correctness

At each step, we are sure that our estimate is greater than or equal to the correct distance. We are assuming non-negative weights for Dijkstra’s algorithm.

**Claim**: When a node $$u$$ is taken out of the priority queue, its estimate is correct.

Suppose not. Let $$H$$ be the set of all nodes that have been explored and whose distance estimates are correct (inductive hypothesis). Since node $$u$$ was taken out of the priority queue, among all the nodes remaining, $$u$$ has the lowest estimate. The shortest path from the source $$s$$ to $$u$$ cannot go through the vertices not in $$H$$ because otherwise, their distances would have been smaller than that of $$u$$, and hence they would have been removed from the PQ before $$u$$. But since $$u$$ was popped off before them, the shortest path from $$s$$ to $$u$$ must go through only the vertices in $$H$$ and since we have already explored all vertices in $$H$$ and their estimates are correct (inductive hypothesis), the estimate of $$u$$ must also be correct.

In other words, Dijkstra ensures that the order in which the edges are relaxed is precisely the order of the edges in the shortest path from a source to a node. It greedily builds up the shortest path tree.

This relies heavily on the fact that **extending a path does not make it shorter which is true whenever our edges have non-negative weights**

### Implementation/Other Stuff

Recall that in BF, we had to relax each edge $$n-1$$ times to be sure that we had found our correct distances. This was because we picked the edges to be relaxed in an arbitrary order.

Dijkstra optimises the process of relaxation by relaxing edges in the “correct” order. Instead of arbitrarily picking edges to be relaxed, we maintain a data structure that tells us exactly which edge to relax. Using this “correct ordering”, we only need to relax each edge once!

To get the path information using Dijkstra, we can create a parent array, update the parent array when distance is updated (i.e., when relaxing an edge leads to updation of distance of destination vertex) and use it to show the shortest path from source to different vertices.

Moreover, **if we are interested only in the shortest distance from the source to a single target, we can stop the loop when the picked minimum distance vertex is equal to the target** (recall our invariant).

### Priority Queue

To be able to get the minimum key (in this case, we can let the key be our current estimate of the node from the source), we need to support the following operations from any data structure that stores our vertices (our PQ stores the nodes, NOT EDGES! storing edges would be pretty pointless since it does not give us any information about the distances to nodes from the source):

* `isEmpty()`- Checks if there are any more elements in the data structure
* `contains(key k)` - Checks if the key `k` exists in the data structure
* `decreaseKey(key k, priority p)` - reduces the priority of key `k` to be equal to `p`. (so that we can decrease priority when the estimate is reduced)
* `deleteMin()` - Deletes and returns the key with the minimum priority (in this case, because we are interested in the node whose estimate is the least)
* `insert(key k, priority p)` - inserts a key `k` with priority `p`.

Notice that a priority queue is an abstract data type - bunch of operations to be supported - and can be implemented in many ways.

### Psuedo-Java Code for Dijkstra

```java
public Dijkstra {
	private Graph G;
	private IPriorityQueue pq = new PriQueue();
	private double[] distTo;

	searchPath(int start) {
		pq.insert(start, 0.0);
		distTo = new double[G.size()];
		Arrays.fill(distTo, INFTY);
		distTo[start] = 0;
		while (!pq.isEmpty()) {
			int w = pq.deleteMin();
			for (Edge e : G[w].nbrList) {
				relax(e);
			}
		}
	}
	relax(Edge e) {
		int v = e.from();
		int w = e.to();
		double weight = e.weight();
		if (distTo[w] > distTo[v] + weight) {
			distTo[w] = distTo[v] + weight;
			parent[w] = v; // to recover the shortest path also
			if (pq.contains(w))
				pq.decreaseKey(w, distTo[w]);
			else
				pq.insert(w, distTo[w]);
		}
}

```

### Time Complexity Analysis of Dijkstra’s Algorithm

For the sake of understanding Dijkstra’s deeply, let us assume that we don’t know how the PQ is implemented. Say, we only know that the `decreaseKey` operation takes $$g(n)$$ time while the `insert` and `deleteMin` operations take $$h(n)$$ time. Let `contains` and `isEmpty()` take $$O(1)$$ (this is not an unreasonable to assume since `contains` can be implemented using a hash table - whenever you insert, add it to the hash table too. Moreover, even if we don’t have the `contains` function, we can just call `decreaseKey` which can delete the key, if it exists, and reinserts it using the new priority).

We will try to break down the steps in Dijkstra to come up with the overall time complexity:

Firstly, each edge is relaxed exactly once. Hence, relax is called exactly $$E$$ times.

Our priority queue stores the nodes and their estimates as the priority. So, the maximum size of the PQ is $$V$$ at any time. (In fact, $$V - 1$$ since you remove the starting vertex in the beginning itself)

All the cost of the algorithm essentially depends on how expensive the relaxation process is.

Each node is inserted exactly once and deleted from the PQ exactly once. So, `insert` and `deleteMin` are called $$V$$ times. The time taken for this is $$Vh(n)$$.

Since there are $$E$$ edges, `decreaseKey` is called at most $$E$$ times (in case every relaxation leads to an updation of the estimate). This takes $$Eg(n)$$.

So, the overall time complexity is $$Vh(n) + Eg(n)$$.

The actual values of $$h(n)$$ and $$g(n)$$ depend on the implementation of the PQ. For example, if we use an AVL tree then `insert`, `deleteMin`, `contains`, `decreaseKey` (just search, delete, insert again to decrease the key) all take $$O(logn)$$. So, the total running time of Dijkstra’s when AVL tree is used as PQ is $$O((E + V)logV)$$. (Notice that $$n =$$ size of the priority queue and hence is upper bounded by $$V$$)

For a connected graph $$E \geq V -1$$ , and so we can simply write $$O(ElogV)$$.

However, if we use an array as a PQ, `insert` `decreaseKey` and `contains` takes $$O(1)$$ (can use a Hashmap to map a node to an integer if the keys of the node are not actually integers). `deleteMin` takes $$O(n)$$ since we need to traverse the entire array.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FmMvwS8bdTtfhNZE9aVOM%2FScreenshot_2022-03-29_at_9.37.13_AM.png?alt=media&amp;token=f41014f5-ed5b-465e-aebf-ddbe22b61ed1" alt=""><figcaption></figcaption></figure>

Think of the time complexity of using a hash table to implement a priority queue: `insert` and `decreaseKey` would take $$O(1)$$ but `deleteMin` would take $$O(V)$$ since it stores nodes in an unordered fashion. Since `deleteMin` would be called exactly $$V$$ times, and `decreaseKey` would be called at most $$E$$ times, the running time would be $$O(V^2 + E)$$ which is $$O(V^2)$$ since $$E$$ cannot exceed $$2 \times \binom{V}{2} = O(V^2)$$ in case of a directed graph. Observe that this is identical to simply using an array (after using a hash function to map to a distinct integer in the range $$1$$ to $$V$$) and so, there is no point in using a hash table over an ordinary array - don’t complicate it unnecessarily.

#### Drawbacks of Dijkstra

1. Cannot be used for graphs with negative weights

Question: If we have a graph $$G$$ with negative edges and the maximum negative weight is $$-c$$, can’t we just add $$c$$ to all edge, use Dijkstra and then subtract $$c$$ again to find the shortest path lengths?

No! Absolutely not! **When you add** $$c$$ **to each edge, you are essentially prioritising the paths that have a shorter number of hops. You are reweighting the edges by modifying the shortest path length by a factor of** $$c\*#$$**edges along the shortest path**. That is, if the actual shortest path has 2 hops but you add $$100$$ to each of the edges (so 200 to the path), while there is another (longer) path only 1 hop away, you only add 100 to the total path, and you end up with the wrong answer.

But\*\*, multiplying a constant $$c > 0$$ to each of the edges (reweighting by multiplying by a positive factor) preserves the shortest path (as the new total path length is also increased by a factor of $$c$$, and does not depend on how many edges are in the shortest path)\*\*

#### Dijkstra’s quotes

> *“Computer Science is no more about computers than astronomy is about telescope”*

> *“There should be no such thing as boring as mathematics.”*

> *“Elegance is not a dispensable luxury but a factor that decides between success and failure.”*

> *“Simplicity is a prerequisite for reliability”*

#### Comparison

BFS, DFS, and Dijkstra all basically use the same algorithm but different data structure to store the order of nodes to be explored. All the three follow the general outline as follows:

1. Maintain a set of explored vertices.
2. Add vertices to the explored set by following edges that go from a vertex in the explored set to a vertex outside the explored set.

| BFS                                                      | DFS                                                     | Dijkstra                                        |
| -------------------------------------------------------- | ------------------------------------------------------- | ----------------------------------------------- |
| Take edge from vertex that was discovered least recently | Take edge from vertex that was discovered most recently | Take edge from vertex that is closest to source |
| Use queue                                                | Use stack                                               | Use priority queue                              |
| SSSP for unweighted graphs                               | Does not give shortest paths                            | SSSP for graphs with non-negative edges         |

## SSSP on DAGs

Let us suppose that we have a DAG and we want to find the shortest path. Obviously we can still use BF (and Dijkstra too if the edges are non-negative). But can we do better since we are sure that there are no cycles? (generally, if we have more constraints - a specific kind of problem - it is much easier to solve than a general problem. For example, longest path problems are NP-hard on general graphs but are super easy on DAGs, as you shall soon see)

Again, we aim to relax the edges exactly once. For this, we need to find the the “right order” of relaxations.

Observe that BFS would not work (just as before)

Our key insight is that **if we relax the edges in the order that they appear in the shortest path from the source to a node, we only need to relax each edge once for the correct estimate to propagate to every node in the path**. If you’re using $$v$$ as an intermediate node from the source $$s$$ to a node $$u$$, before you look at the outgoing edges of $$v$$, you need to make sure that $$v$$ has its correct estimate. If it does, you only need to look at the outgoing edges once because no further reduction of the estimate of $$v$$ can happen (and hence, your estimates of the neighbours of $$v$$ are also correct).

To be sure that a node has a correct estimate, **we only process a node after all its incoming edges have been relaxed** (this should bring flashbacks of Kahn’s algorithm to mind)

We have already learnt how to find such an ordering - Topological sort!!!

If we arrange the node left to right such that all the edges only point towards the right, then we can simply start from the source and relax all the nodes from left to right (relaxing a node is equivalent to relaxing all its outgoing edges). Observe that if a node appears on the left of a source in the topological sort, there is no path from the source to that node (since all edges point right).

The algorithm works because if a path from $$S$$ to $$D$$ goes through $$A$$, then we can be sure that $$A$$ is relaxed before $$D$$ (since $$A$$ must occur before $$D$$ in the topological ordering)

To obtain a topological sort, we can run a post-order DFS and add each node to the end of the current topological ordering to get the final ordering. This takes $$O(V+E)$$ time. Then, all we need to do is iterate through every vertex and relax its outgoing edges, thus taking $$O(V+E)$$ time as well.

Hence, we can find SSSP on a DAG in $$O(V+E)$$ time!!!

Does this also work if there are negative weights?

Yes! We are not assuming that the weights are positive at any step.

How can we find the longest path in a DAG?

Yes! It’s super easy! Just negate the weights of each edge and use the same algorithm above (topological ordering). Then, negate the distances in the end to get the longest path distances. So, we can find the **longest path in a DAG in** $$O(V+E)$$ **time!**

How about finding the longest path in a general graph (which can have cycles)?

No! If we negate the edges now, it is possible for negative cycles to be present and all our algorithms fail to find the shortest path with negative cycles. In fact, if you think carefully about it, if there exists a negative cycle in the negated graph, there exists a positive cycle in the original graph. So, you can keep going in cycles and the longest path distance can be $$\infty$$. So, we should ideally specify that we mean “simple path” (no repeated edges)

Finding a longest path in a general graph (with possibly cycles) is NP-hard - if you could find the longest simple path, then you could decide if there is a path that visits every vertex. Any polynomial time algorithm for longest path thus implies a polynomial time algorithm for Hamiltonian Path. Hence, by reduction from Hamiltonian Path (which we know to be NP-hard), we can conclude that finding the longest simple path is also NP-hard.

## Clarification on “Shortest Path” and “Longest Path”

<mark style="background-color:red;">Q. Why is longest path NP-hard but shortest path easily solvable? Why does it not work to negate all edges and run a SSSP algorithm to find longest path?</mark>

Ans: There is a very subtle issue here.

We have spent quite some time discussing the shortest path problem and how certain algorithms does not work under the presence of negative cycles. It's a common source of confusion (or at least, lack of intuition) and I think the main issue comes from not defining terms carefully enough.

The following discussion deals with directed weighted graphs and uses these definitions:

* A **walk** is a sequence of edges joining a sequence of vertices.
* A **trail** is a walk in which all edges are distinct.
* A **path** is a walk in which all vertices are distinct. (Note that if a walk is path, then the walk is automatically a trail)
* A **simple path** is a path. They are the same thing.

We are concerned with the shortest path problem. The SSSP variant asks for the shortest path from a source node to every node in the graph while the APSP variant asks for the shortest path between any two nodes in the graph. These paths should not have repeated vertices.

So far, we have learnt a handful of algorithms that "solves" SSSP or APSP, some of which are useful against special graphs (e.g. BFS when all edge weights are equal, relax edges in topological order when we are given a DAG). Here, we shall focus on the more general Dijkstra's algorithm, Bellman-Ford algorithm and Floyd-Warshall algorithm. Note that

* Dijkstra's algorithm fails when the graph has negative edge weights.
* Bellman-Ford algorithm fails when the graph has negative cycles.
* Floyd-Warshall algorithm fails when the graph has negative cycles.

The lecture explained in detail why Dijkstra's algorithm fails when there are negative edge weights. In summary, the assumption "all edge weights are non-negative" is used in proving the correctness of the algorithm. Without this assumption, we can construct a graph for which the algorithm fails.

Some might argue that Bellman-Ford algorithm does not "fail" against graph with negative cycles. Paths in such graphs can be infinitely short because we can repeatedly walk around the negative cycles, so there really is no "shortest path" and hence there is no meaningful output.

However, according to the definitions given above, a path must not have repeated vertices. Therefore, we are not allowed to repeatedly walk around the negative cycles in the first place. It turns out that the shortest paths of graphs with negative cycles are still well-defined. For instance, consider the graph below:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FqkSYLDuTgYB5ChmG0lbq%2FUntitled.png?alt=media&amp;token=0c9fccdb-7d1c-48a0-a7e4-e429b0c69e2d" alt="" width="375"><figcaption></figcaption></figure>

If we were to run Bellman-Ford algorithm on this graph, we would not be able to correctly find the shortest path from node `s` to node `v`. In this case, the desired shortest path exists and has length 0, achieved via the path `s->u1->u2->u3->v`. Any attempts to walk through the negative cycle more than once is illegal. In particular, `s->u1->u2->u3->u1->u2->u3->v` is not a valid path. Instead, it falls under the category of a walk.

The reason negative cycles were brought up in the lecture is to show that Bellman-Ford algorithm does not always work for any graphs. In particular, it fails to find the shortest paths in graphs with negative cycles. The algorithm does not "remember" whether a node has been visited, and so might incorrectly decrease the estimates of the nodes. It is important to note that in such cases, the shortest paths still exist, but are not able to be found using Bellman-Ford algorithm. The algorithm does nothing more than accurately detecting these negative cycles.

Although this was not mentioned in the lectures, it is interesting to note that Floyd-Warshall algorithm fails for graphs with negative cycles as well. Consider the following graph:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FOL1OWpiYBRffC1YNsZ3S%2FUntitled%201.png?alt=media&amp;token=d9a087ed-e7d2-425e-93d5-d2aad417d5bb" alt="" width="185"><figcaption></figcaption></figure>

Let `P0 = { }, P1 = { a }, P2 = { a, b }, P3 = { a, b, c }`. Note that the shortest path from every node to itself must be 0. However, from the recurrence given in the lecture, `S[c, c, P2] = min(S[c, c, P1], S[c, b, P1] + S[b, c, P1]) = min(0, -4 - 2) = -6`. This answer corresponds to the invalid path `c->a->b->c`, therefore the output of Floyd-Warshall algorithm in this case will be incorrect. We can similarly use the algorithm to detect negative cycles though.

In summary, notice how we never really had an algorithm that solves the shortest path problem for general graphs in polynomial time. If such algorithm exists, it turns out that we can similarly solve the longest path problem in polynomial time by negating all edge weights and running this algorithm. Indeed, as mentioned during the lecture, the longest (simple) path problem is NP-complete (or NP-hard, depending on how the problem is formulated). This also implies that the shortest path problem for general graphs is NP-complete.


# MST (Prim's and Kruskal's)

## Problem

First let us define the problem statement clearly. Given a weighted undirected graph (think about why it would be difficult for a directed graph), a spanning tree is defined as a tree that contains all the nodes of the graph. **A Minimum Spanning Tree (MST) is defined as a spanning tree with the lowest total cost (weight).**

Formally, a spanning tree is an acyclic subset of the edges that connects all nodes.

Note that there cannot be any cycles since we need it to be a tree. Moreover, if all the edges have non-negative weights and if there were cycles, we could remove one edge of the cycle (still preserving connectedness) and reduce the weight.

An example of an MST is:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FLNuodq0j7pBX1ick1Yfb%2FScreenshot_2022-04-10_at_10.47.46_AM.png?alt=media&amp;token=d7e74b30-9384-43e8-b1b4-40673d2f7d59" alt="" width="375"><figcaption></figcaption></figure>

Can an MST be used to find shortest paths? That is, between two nodes, does the shortest path between them lie on the MST?

No! An MST minimizes the total weight but not the shortest distance between two nodes. For example, in the graph above, the shortest path between the top-left and bottom-left nodes is 9 (direct path) but the path in the MST is 4 + 1 + 8 = 13 > 9.

So, MST is used for “minimizing the total cost” problems. In general, it is important to realize when to use shortest path algorithms and when to use MST algorithms.

Is an MST for a graph unique?

No! If edges have the same weight, it is possible that there are multiple MSTs with the same minimum weight.

But, if all the edge weights are distinct, then the MST must be unique (because there is no ambiguity in sorting the edges in Kruskal’s algorithm or choosing the minimum outgoing edge from a vertex in Prim’s).

**Hence, If all edge weights in a connected graph G are distinct, then G has a unique minimum spanning tree**

To simplify the analysis and avoid the annoyingly subtle case of non-distinct edge weights, we consider the case where all the **weights are distinct**. Hence, we can refer to *an* MST of a graph as being *the* MST.

## Properties of an MST

1. **There are no cycles.**
2. **When an MST is cut along any edge, the two resulting spanning trees are MSTs for those particular set of nodes.**
   1. But the converse is not true. That is, **if two MSTs are joined by the smallest edge between them, the resulting spanning tree need not be an MST.** Think about what would happen if you decided to split the set of nodes poorly to begin with. <img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2F0mlbfCBiLuraNX67ecPS%2FScreenshot_2022-04-10_at_10.58.48_AM.png?alt=media&amp;token=393d97cb-a30f-4a52-8c6c-3f83ad4c24cd" alt="" data-size="original">
3. **Cycle property: For every cycle, the maximum weight edge is not in the MST.**
   1. Proof (Cut and paste argument): Assume the heaviest edge is in the MST. Now, remove the maximum weight edge. This cuts the MST into 2 MSTs. Since there is a cycle, there is another edge (the one that we left out initially) that joins the 2 MSTs. Use this edge to join. The total weight is lower since you replaced a heavier edge with a lighter one. Moreover, you still get a spanning tree. Hence, it contradicts the fact that the initial ST was an MST.
   2. In the proof above, we implicitly used the idea that for any cycle, an even number of edges are cut across a cut (for any line drawn, the cycle intersects the line at an even number of points)
   3. It is important to note that the inverse of the cycle property is not true in general, i.e., the statement “For every cycle, the minimum weight edge is always in the MST” is false! In fact, a minimum weight edge of one cycle can be the maximum weight edge of another cycle and hence, by the cycle property itself, it cannot be in the MST. Hence, **for every cycle, the minimum weight edge may or may not be in the MST.**
4. **Cut property**: Let us define a **cut** of a graph $$G = (V,E)$$ as a partition of the vertices $$V$$ into 2 disjoint subsets. An edge is said to **cross a cut** if it has one vertex in each of the two disjoint subsets. Then, **for every partition of the nodes, the minimum weight edge across the cut is in the MST.**
   1. Proof is similar to the cut and paste argument made as in the cycle property. Suppose not. Then another edge that crosses the cut must be in the MST (which has a weight higher than our minimum weight edge that crosses the cut). We can “cut and paste” this edge to get an MST of lower weight. So, our assumption was incorrect. Hence, proved.
   2. A direct consequence of the cut property is that **for every vertex, the minimum outgoing edge is always part of the MST**. This follows necessarily because the cut property holds for **any** partition. In particular, we can create $$V$$ partitons - each of which divides the graph into 2 sets - one containing exactly one node, and the other containing the rest of the nodes.
   3. The inverse of the cut property is not true in general, i.e., the statement “The maximum outgoing edge is never part of the MST” is false. It is easy to come up with some examples to prove this. (e.g. in the graph above, look at the rightmost node. Both its edges are in the MST. In particular, the maximum outgoing edge is in the MST. Hence, **for every node, the maximum outgoing edge may or may not be part of the MST.**

Can an MST be used to find the smallest maximum edge path between two nodes? That is, if we define the weight of a path to be the maximum weight of all the edges in the path, does the shortest path between two nodes lie on the MST?

Yes! At every step, we are trying to put the minimum weight edge into the MST. So, naturally, all the edges in the MST have low weight. This leads to the minimsation of the maximum edge path between any two nodes. (Note that an MST minimizes the maximum edge weight present in the path, but NOT the total sum of the weights along the path)

#### Generic MST Algorithm

Every MST algorithm relies fundamentally on the following two rules:

1. **Red rule: If C is a cycle with no red arcs, then colour the maximum weight edge in C red.**
2. **Blue rule: If D is a cut with no blue arcs across the cut, then colour the minimum weight edge in D blue.**

In the end, all the blue edges will form an MST. The above generic algorithm is just a direct cosequence of the cycle property and the cut property. So, we can greedily build the MST by repeatedly applying red rule or blue rule to an arbitrary edge.

## Prim’s Algorithm (Jarnik 1930, Dijkstra 1957, Prim 1959)

The algorithm itself is based on the cut property and quite simple to understand:

1. Pick an arbitrary node $$u$$
2. Add it to a set (which will store all the nodes already connected by the spanning tree) *`sptSet`*
3. Look (read: relax) at all the outgoing edges of $$u$$ (essentially, observe the edges that are across the cut $$V - sptSet$$ and $$sptSet$$) and update the distances of other nodes in the priority queue by setting the distance of each node to be the minimum of the current distance and the weight of this edge connecting $$u$$ and this node). Pick the minimum weight edge connecting a node in *`sptSet`* to one outside the *`sptSet`*. Say, the other node is $$v$$. Add $$v$$ to the *`sptSet`* and add the edge connecting $$(u,v)$$ to a set that stores the edges of the MST.
4. Then, look at all the outgoing edges of the newly added node $$v$$ and update the distances of other nodes in the priority queue.
5. Pick the minimum node in the priority queue (the least distance between this node and any node already in the *`sptSet`*).
6. Repeat steps 2-6 until the priority queue is empty (all nodes are in the *`sptSet`*)

Note: **The priority queue stores the nodes outside the&#x20;*****sptSet*****&#x20;prioritised by their minimum distance to any node inside the&#x20;*****sptSet*****.**

A key invariant of Prim’s algorithm is that at every step, the edges being chosen form an MST for those set of nodes connected by the tree. That is, it greedily builds the MST. This is in contrast to Kruskal’s algorithm in which the edges at any arbitrary step need not form a tree (since they may be disconnected). So, if you stop runnning Prim’s algorithm midway, you still get an MST for a subset of the original graph, but this is not true for Kruskal’s as you get mulitple MSTs for multiple subsets of the graph.

Another observation is that every node in the graph is either in the priority queue or the *`sptSet`*. That is, the two form a partition of the set of nodes.

### Pseudocode

```java
while (!pq.isEmpty()) {
	Node u = pq.deleteMin();
	sptSet.put(u);
	for each (Edge e: u.edgeList()) {
		Node v = e.otherNode(u);
		if (v not in sptSet && pq.getPriority(v) > e.getWeight()) // v is either in sptSet or in pq
			pq.decreaseKey(v, e.getWeight());
			parent.put(v,u); // mark that we visited v from u in the MST
```

Initially, other than the starting node, the priorities of all other nodes are `Integer.MAX_VALUE` since we don’t know the distances.

### Running time of Prim’s using AVL tree for PQ: $$O(ElogV)$$

`decreaseKey` operation takes $$O(logn)$$ when there are $$n$$ elements in the PQ implemented using AVL tree.

In this case, the size of the PQ is at most $$V$$ since it stores the vertices. We look at each vertex once (total cost $$V$$) when we delete it from the PQ (total cost $$O(VlogV)$$). We look at each edge once and perform at most one `decreaseKey` operation per edge (total cost $$O(ElogV)$$).

Adding all the costs together and assuming $$E \geq V - 1$$, **the running time of Prim’s is** $$O(ElogV)$$**.**

Notice how we analysed the algorithm above by assigning each cost of an operation to an edge or a vertex. So, rather than thinking in terms of each node and each edge, we think from a higher level and view the total cost of an operation as being dependent on the number of edges or vertices. This makes it much easier to analyse.

It is worthwhile to compare Prim’s algorithm to Dijkstra’s since they are quite similar (mostly because Dijkstra also came up with this algorithm for making an MST)

| Prim’s MST                                                             | Dijkstra’s Shortest Path                                                        |
| ---------------------------------------------------------------------- | ------------------------------------------------------------------------------- |
| Maintain a set of visited nodes (`sptSet`)                             | Maintain a set of visited nodes (not in the priority queue)                     |
| Greedily grow the set by adding a node connected via the lightest edge | Greedily grow the set by adding neighbouring node that is closest to the source |
| Use PQ to order nodes by edge weight                                   | Use PQ to order nodes by distance from source.                                  |

Greedily in this case means that every step of the algorithm, we consider the best decision that we can make with the current information. Greedy algorithms can solve optimisation problems. Both, shortest path and MST are optimisation (minimisation, in particular) problems.

## Kruskal’s Algorithm

Also a greedy algorithm - it adds the lowest weight edges to the MST. Skip the edges that connect 2 nodes already connected by a blue edge since otherwise it would form a cycle (and this edge in fact, would have the maximum weight in the cycle since you are looking at edges in increasing order of weight).

1. Sort edges by weight from smallest to biggest.
2. Consider edges in ascending order:
   1. If both endpoints are already in the tree, skip this edge (colour it red) (perform a `Find` operation)
   2. Otherwise, join the two nodes with a blue edge (colour it blue) (perform a `Union` operation)

We can use a Union-Find data structure to keep track of which nodes are in the same blue tree.

### Pseudocode

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FwugzPr9GXr9IjrSOfcfo%2FScreenshot_2022-04-10_at_11.32.05_AM.png?alt=media&amp;token=33286141-cde4-4390-9b2b-b237c6505685" alt="" width="563"><figcaption></figcaption></figure>

### Running time of Kruskal’s algorithm: $$O(ElogE)$$

Say, we are using the most optimized Union-Find data structure that takes $$O(\alpha)$$ for each union/find operation. We perform at most $$O(E)$$ such operations resulting in a total cost of $$O(\alpha E)$$. BUT, the most expensive part of Kruskal’s algorithm is actually to sort the edges! This takes $$O(ElogE)$$ and so, the running time of Kruskal’s is dominated by this factor and hence, is $$O(ElogE)$$.

Note that $$E$$ is $$O(V^2)$$ (in case of a clique - worst case) and so, $$logE = O(logV^2) = O(2logV) = O(logV)$$

Hence, Prim’s and Kruskal’s have the same asymptotic running time.

## MST Variants

1. What if all the edges have the same weight?
   1. Well, then any spanning tree is a minimum spanning tree. So, you can just use BFS or DFS and find MST in $$O(V+E)$$ time.
   2. In particular, if all the edge weights are $$c$$, then the cost of an MST is $$c\times(V-1)$$ (Because any tree with $$V$$ nodes has $$V-1$$ edges)
2. How can we improve Kruskal’s algorithm if we know that all the edges have weights from $${1,\dots n}$$ where $$n$$ is not too big?
   1. The most expensive part of Kruskal’s algorithm is sorting the edges. In this case, we can use counting sort (with an array of size $$n$$ to sort the edges in $$O(E)$$ time). Hence, the running time of Kruskal’s is $$O(\alpha E)$$ because for each edge, performing union takes $$O(\alpha)$$ and performing find takes $$O(\alpha)$$. Remember that $$\alpha$$ is the Ackermann function (iterated log) but it is not a constant. It is just an extremely slowly growing function.
   2. A cool feature of such a graph would be that we can also optimize Prim’s algorithm for this. We can use an array of size 10 as a priority queue of linked lists where the slot $$A\[j]$$ holds a linked list with edge weight $$j$$ to a node in the *sptSet*. Then, `decreaseKey` would move a node to the new linked list. In this case, the running time of Prim’s would be $$O(E)$$ because:
      1. `insert` and `deleteMin` are performed $$V$$ times. (cost: $$O(V)$$ since deleteMin just looks at the minimum bucket and takes any node - we can store a pointer to remember the minimum bucket if you don’t want to traverse the array eacht time)
      2. `decreaseKey` is performed at most $$E$$ times. (decreaseKey takes $$O(1)$$ because we can lookup the node (e.g. in hash table), delete it from the current linked list and move it to the new slot’s linked list. We don’t need to traverse the old linked list to find the node if we simply use a hash table. So, the total cost of `decreaseKey` is $$O(E)$$.
      3. Hence, the total cost is $$O(V+E) = O(E)$$.

A natural question to ask is: If we can use the second variant of MST to solve in $$O(E)$$, why does this not work for Dijkstra? The answer is subtle: even though the maximum weight of any edge is $$n$$, the total path length can be upto $$(V-1)\times n$$ since we are concerned with the total distance from the source and not just the weight of each edge. We know that the maximum diameter of a graph is $$V - 1$$ (think of a line graph) and if each edge has weight $$n$$, the total path length is $$(V-1) \times n$$. It is (generally) not feasible to have an array of such a large size, especially since it is a function of the maximum edge weight and not a function of the number of edges.

## MST for Directed Graphs?

MST is more difficult to define for a directed graph - does it require that **every** node be connected to every other node through some set of edges in the MST? Or is one-way connectedness between a pair of nodes sufficient?

We define a rooted spanning tree as a tree in which every node is reachable on a path from the root (and there are no cycles obviously).

This is a much harder problem to solve now since:

1. the cut property does not hold
2. the cycle property does not hold
3. the generic MST algorithm does not work

As a special case, however, consider a directed acyclic graph with one root (we define a root as a node with no incoming edges).

For every node except the root, add the minimum weight incoming edge. Then, obviously there are no cycles since the graph itself is acyclic. Each edge is chosen once for a vertex except the root and so there are $$V-1$$ edges. Hence, it is a tree. Moreover, it is an MST! This should seem obvious once you realise that you have chosen the minimum weight incoming edge for each node. Every node has to have at least one incoming edge in the MST so this is the minimum spanning tree. Hence, we can find an MST for a directed acyclic graph with one root in $$O(V+E)$$ time (for every vertex, look at all its incoming edges. Each edge is considered once. Each vertex is considered once)

## Maximum Spanning Tree

Define a MaxST to be a spanning tree of maximum weight. How to find a MaxST?

Negate the edges. Find MinST. This is your MaxST.

Notice that having negative edges does not really matter. **Our MST algorithms work perfectly fine even for negative edges - this is because only the relative weights of the edges matter**. So, if you have a graph with negative edges: you can simply run Prim’s or Kruskals (OR) you can add a positive constant $$k$$ to each edge to make each edge positive.

Or, another neat way to find a MaxST would be to run Kruskal’s in reverse. That is, sort the edges in descending order so that you add the heaviest weight edges first.

What happens if you add a constant $$k$$ to the weight of every edge? Does it change the MST?

No! In fact, MST only depends on the relative weight of different edges. By adding $$k$$ or multiplying a positive constant $$k$$, you are not changing the order of the edges (when sorted by weight). It might be easier to think of Kruskal’s algorithm to explain this - when you sort the edges, you only care about the relative weights. Adding a constant does not change this sorted order. Hence, Kruskal will inspect the edges in the same order, resulting in the same MST.

This is different in case of shortest paths since there we consider the weight of a path to be the sum of the weights of all the edges. So, adding a constant $$k$$ to each edge weight will result in unequal weights being added to paths of differing lengths. In particular, shorter paths have been effectively prioritised since the amount of weight added to a path is $$k \times (\text{path length})$$

## Miscellaneous

Other MST algorithms do exist (e.g. Boruvka’s $$O(ElogV)$$) and are slightly optimized for modern requirements and parallelizability.

The currently best known algorithm is that of Chazelle (2000) in which he came up with an MST algorithm that runs in $$O(E\alpha(E,V))$$ where $$\alpha$$ is the classical functional inverse of Ackermann’s function.

### Boruvka’s Algorithm Advantages

Despite its relatively obscure origin, early Western algorithms researchers were aware of Boruvka’s algorithm, but dismissed it as being “too complicated”. As a result, despite its simplicity and eciency, most algorithms and data structures textbooks unfortunately do not even mention Boruvka’s algorithm. This omission is a serious mistake; Borvka’s algorithm has several distinct advantages over other classical MST algorithms.

1. Boruvka’s algorithm often runs faster than its O(E log V) worst-case running time. The number of components in F can drop by significantly more than a factor of 2 in a single iteration, reducing the number of iterations below the worst-case $$\lceil log\_2V \rceil$$
2. A slight reformulation of Borvka’s algorithm (actually closer to Boruvka’s original presentation) actually runs in O(E) time for a broad class of interesting graphs, including graphs that can be drawn in the plane without edge crossings. In contrast, the time analysis for the other two algorithms applies to all graphs.
3. Boruvka’s algorithm allows for significant parallelism; in each iteration, each component of F (subgraph of MST) can be handled in a separate independent thread. This implicit parallelism allows for even faster performance on multicore or distributed systems. In contrast, the other two classical MST algorithms (i.e., Prim’s and Kruskal’s) are intrinsically serial.


# Concept

Dynamic Programming (DP) is just a problem-solving technique. It's nothing fancy. The key idea is very simple really: instead of doing the same work multiple times, we can be, err, lazy, and "store" the result of the computation we did previously and use that directly.

If I asked you to solve 437 x 89 without a calculator, you might take some time (after getting annoyed at me for a while) to solve the question using a pen and paper.

And if i ask you the same question 5 minutes later, are you going to actually do the multiplication again? I should hope not. You would just look at the piece of paper which you had used earlier, and tell me the answer (almost immediately).

That's it. That's all dynamic programming is. It's just a way to "cache" the result. Everything that follows is just a way of expressing this idea in the programming lingo.

## When to use DP?

**Optimal Substructure:** An optimal solution can be constructed from optimal solution to smaller sub-problems. That is, to solve a larger problem, we can solve the smaller problems and combine the solutions to get our required original solution.

{% hint style="info" %}
Optimal substructure basically allows us to break down the problem into smaller pieces, and solve them individually / independently, and then using the solutions of these smaller pieces to get the solution to the bigger problem.

If this is *not* the case, it woudn't make sense to split the problem in the first place...? Since we wouldn't get the correct answer using this approach anyway. So, we would probably have to use some approach.
{% endhint %}

DP is basically brute force (solve all subproblems in order to solve the original problem) + memoization (store the result of the subproblems you solve so you only ever to have solve them once).

Examples of problems that have an optimal substructure include:

1. Sorting - We have seen in MergeSort that we sort two smaller array and then merge them to get a sorted array.
2. Reversing a string - To reverse a string of length $$n$$, we can reverse the last $$n-1$$ characters and then add the first character to the end of this reversed string. (actually this is equivalent to reversing an array which can be done by splitting the array into two halves, recursively reversing each part and joining them in the other order)
3. Merging two arrays - We can split the problem into merging two smaller arrays
4. Shortest paths - **We know that if** $$P$$ **is the shortest path from** $$u$$ **to** $$v$$ **and it contains** $$w$$**, then** $$P$$ **contains the shortest path from** $$u$$ **to** $$w$$ **and from** $$w$$ **to** $$v.$$ **So, a shortest path between two nodes is composed of the shortest path between many intermediary nodes too.**
5. Minimum Spanning Tree - **We know that if we cut an MST, we get 2 MSTs.**

So, it becomes clear that optimal substructure is a very common property. In fact, nearly every problem has an optimal substructure. There are two kinds of algorithms used to solve such problems:

1. Greedy Algorithms: e.g. Dijkstra, Prim’s MST, Kruskal’s MST
2. Divide-and-Conquer: e.g. MergeSort, Fast Fourier Transform

But having an optimal substructure is not the only requirement to be able to use DP effectively.

DP should be used when the problem has an **optimal substructure with overlapping subproblems.** That is, the same problem is used to solve multiple bigger problems. Then it is worth storing the result (memoisation) to avoid recomputing the same problem.

{% hint style="success" %}
This is just a fancy way of saying "it only makes sense to save the result if we're going to be needed it again."
{% endhint %}

So, both Divide-and-Conquer and DP algorithms have an optimal substructure but the key difference lies in whether or not the problem has overlapping subproblems.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FXgcsNqcwJ4T1U8VppVm1%2FScreenshot_2022-04-11_at_8.27.41_PM.png?alt=media&amp;token=65bb4fed-065c-42a2-8a33-e3dc04f5c818" alt=""><figcaption></figcaption></figure>

There are two main strategies to solve DP problems:

1. Bottom-up approach: start from the smallest problems and “build” the solution upwards until you reach your required case. This is similar to topologically sorting the DAG representation of the problem and solving it in reverse order.
2. Top-down approach: Try to solve the main problem by breaking it down into smaller problems and then recursively trying to solve those, while memoizing the answers to solved problems.

### DP as a table

People often view DP strategies as trying to fill up a table. Each entry in the table corresponds to a subproblem that is being solved.

The key requirement is that filling any entry (i.e., solving any subproblem) should only depend on the entries that have already been filled, preferably, just the nearest ones (latest filled entries). So, it is necessary to fill the DP table in the right order.

What is more important (and generally the difficult part) is deriving the relation/formula between the entries of the table - i.e., given the solution to smaller subproblems, how do you combine them to get your larger solution?

Often it is also difficult to decide what the subproblems are and how they can be effectively used to solve the original problem. All these questions must be answered before a DP algorithm can work.

It is worth mentioning that this “table” can be an array, a 2-D matrix, or even a 3-D or 4-D matrix. It all depends on the question.

### DP Recipe

In general, we will follow the following steps to solve a problem using DP:

1. Define sub-problems (in a clever way such that we have optimal substructure of the problems)
2. Identify the optimal substructure (i.e., if you're given the solutions to the subproblems, can you solve the original problem?)
3. Identify the base cases (i.e., what's the smallest problem you can solve without knowing the solutions to any other problems?)
4. Solve problem using subproblem, usually in terms of a recurrence relation (i.e., HOW would you construct the solution of the main problem using the solutions of subproblems)
5. Write (pseudo)code

### Analysing Time Complexity

While analysing the time complexity of DP, it is useful to split the analysis into:

1. Number of subproblems (or even a higher level e.g. row in DP table)
2. Cost of solving each subproblem (e.g. cost of solving a row in DP table)


# APSP Floyd-Warshall

## Problem

Given a directed weighted graph (with no negative weight cycles), we want to be able to answer queries of the form “what is the minimum distance between $$v$$ and $$w$$?” quickly. This is a classic All Pairs Shortest Path Algorithm.

## Attempt 1

Do not pre-process the graph at all. Run Dijkstra each time you get a query (if the query has the same source vertex as a previous query, no need to run Dijsktra again).

Then, to answer $$Q$$ queries $$(Q > V)$$, it would take $$O(VElogV)$$. In case of a dense graph, this becomes $$O(V^3logV)$$

## Floyd-Warshall (FW)

Floyd and Warshall gave a beautifully simple algorithm to calculate APSP in $$O(V^3)$$ time. So, it is better to use FW rather than repeatedly running Dijsktra in case of a dense graph. In case of a sparse graph, running Dijkstra $$V$$ times is faster than FW since $$logV$$ grows slower than $$E = O(V)$$. In fact, in case of a sparse graph, we don’t know how to solve APSP faster than $$O(V^2logV)$$.

Notice that if all the edge weights were identical, we could simply run BFS/DFS from each node and get the APSP in $$O(VE)$$ time.

FW is also useful for finding the diameter of a graph (since diameter involves knowing the shortest path between all pairs of nodes, and then taking the maximum one)

FW outputs $$dist\[v,w]$$ to be the shortest distance from $$v$$ to $$w$$, for all pairs of vertices $$(v,w)$$.

Why can we use DP here? Well, shortest paths have an amazing amount of optimal sub-structure: We know that if $$P$$ is the shortest path from $$u$$ to $$v$$ and it contains $$w$$, then $$P$$ contains the shortest path from $$u$$ to $$w$$ and from $$w$$ to $$v.$$ So, a shortest path between two nodes is composed of the shortest path between many intermediary nodes too.

Moreover, (and more importantly) many shortest path calculations depend on the same sub-pieces. That is, they have overlapping subproblems!

Although it is easy to understand and believe that shortest paths have overlapping subproblems, it is much more difficult to correctly identify these right subproblems?

This is where the genius of Floyd and Warshall truly shines:

**Let** $$S\[v,w,P]$$ **be the shortest path from** $$v$$ **to** $$w$$ **that only uses intermediate nodes (if any) from the set** $$P$$**.** In other words, $$S\[v,w,P]$$ is the length of the shortest path from $$v$$ to $$w$$ that does not include any vertices not in $$P$$.

Let $$e(v,w)$$ be the weight of an edge from $$v$$ to $$w$$.

Then, our base case is: $$S\[v,w,\phi]= e(v,w)$$ (where $$\phi$$ represents the empty set). That is, if you cannot use any intermediate nodes, the only way to get from $$v$$ to $$w$$ is through a direct edge, if any. If no such edge exists, $$e(v,w) = \infty$$.

But the problem now is that there are so many possible such sets $$P$$. In particular, there are $$2^V$$ possible subsets of $$P$$ that are all candidates and possible subproblems that we need to solve. But the question is, do we really need to solve all of them? Or can we only choose a few to solve and still guarantee that we get the correct answer.

This step represents another flair of creativity and intelligence by Floyd and Warshall. They realised that they only needed to solve $$n + 1$$ subproblems (where $$n = V$$). In particular, only the following sets need to be considered as subproblems:

$$P\_0= \phi$$

$$P\_1 = {1}$$

$$P\_2 = {1,2}$$

$$P\_3 = {1,2,3}$$

$$\dots$$

$$P\_n = {1,2,3,\dots,n}$$

At each step, as we grow our set $$P$$, we are allowed to use more nodes as intermediate nodes if necessary. So, in the last step, we are allowed to use all possible $$n$$ nodes as intermediate nodes, giving us the correct shortest paths.

How do we obtain the recurrence relation now, using the pre-calculated subproblems? Say, we are trying to calculate $$S\[v,w,P\_8]$$ and we have already calculated all the shortest paths when we are allowed to use nodes in $$P\_7$$ as intermediaries.

Then, there are two possibilities:

1. The shortest path in $$S\[v,w,P\_8]$$ includes 8 (the new shortest path contains 8 as an intermediate node)
   1. Since $$8$$ is an intermediate node along the shortest path from $$v$$ to $$w$$ using only the nodes in $$P\_8$$, the shortest distance from $$v$$ to $$w$$ along this new path must be $$S\[v,8,P\_7] + S\[8,w,P\_7]$$
   2. We cannot have any other nodes like $$9,10,11,\dots$$ in this path from $$v$$ to $$8$$ or from $$8$$ to $$w$$ since they do not appear in the overall path from $$v$$ to $$w$$ using $$P\_8$$.
2. The shortest path in $$S\[v,w,P\_8]$$ does not include 8 (that is, even though we are allowed to use $$8$$, it does not give us a shorter path)

So, the recurrence relation is $$S\[v,w,P\_8] = min(\ S\[v,w,P\_7]\ ,\ S\[v,8,P\_7] + S\[8,w,P\_7]\ )$$.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FAa7WDDugbMzrvKq9FE0F%2FScreenshot_2022-04-12_at_6.39.11_PM.png?alt=media&amp;token=0056e74b-8f89-4fa2-bc3c-ccc802c0e68d" alt="" width="563"><figcaption></figcaption></figure>

### Optimising Space

Notice that we don’t actually need to store a 3-D matrix for S. To calculate the APSP using intermediate nodes in $$P\_i$$ we only need the values from . So, a single 2-D matrix suffices as we store the current value and keep over-writing the old values, updating as and when necessary. Notice that it can never be the case that the shortest path from $$v$$ to $$k$$ includes $$k$$ as an intermediate node (as that would indicate a negative cycle containing $$k$$). So we don’t need to worry about some values already using $$P\_k$$ while others using $$P\_{k-1}$$ while we are adding $$k$$ to the set of allowed intermediate nodes as we progressively update the dp table.

### Pseudocode

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fgp9OCoasBxj3VtMINPwx%2FScreenshot_2022-04-12_at_6.45.06_PM.png?alt=media&amp;token=104454cf-877f-45d1-957a-ef8f176284b4" alt=""><figcaption></figcaption></figure>

In the above code, the outer loop tracks which nodes are allowed to be used (the current value of $$k$$ determines $$P\_k$$). The inner 2 loops, deal with looking at every pair of nodes. We return a 2-D matrix where $$S\[v]\[w]$$ is the shortest path from node $$v$$ to $$w$$.

Merely glancing at the 3 nested for loops should convince you that the running time of FW is $$O(V^3)$$

In fact, FW is so elegant that it only needs 4 lines of code to express the key algorithm: 3 of which are for-loops, and one represents the sheer brilliance of the two computer scientists.

Note that there are $$V^3$$ subproblems in FW: for each node (there are $$V$$ nodes), you need to find the shortest path to all other nodes (again $$V$$ nodes) using $$V$$ sets of allowed intermediate nodes. So, $$V\times V \times V$$ = $$O(V^3)$$. Another way to think about this is that we were originally using a 3-D matrix to store all our subproblems but now we are overwriting entries in a 2-D matrix (since we don’t need to store older values). In particular, each entry in the 2-D matrix is overwritten exactly $$V$$ times (once for each iteration of the outermost loop) and since the size of the matrix is $$V^2$$, there must be $$V^3$$ subproblems. Using this, we also observe that all our time is spent filling this table and it takes is $$O(1)$$ to fill up a cell in the memo table since we are just calculating the minimum of two values. So, the running time is $$O(V^3)$$.

### Path Reconstruction

What if you want the path, along with the path length between any two nodes?

There is also an optimal substructure for this! If $$z$$ is the first hop on the shortest path from $$v$$ to $$w$$, then the shortest path from $$v$$ to $$w$$ is $$z +$$ shortest path from $$z$$ to $$w$$.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FMomdJvKtERMR0Y56YUVo%2FScreenshot_2022-04-12_at_6.50.10_PM.png?alt=media&amp;token=b2b9e091-70e9-4efd-90a3-d9f6a1a56e25" alt=""><figcaption></figcaption></figure>

So, rather than storing the entire path, it suffices to store just the first hop for each destination (e.g. routing table) and you can reconstruct the path between any pair of nodes.

You only need $$O(V^2)$$ space for this. For each pair of nodes, store the first node in the path. That is, $$path\[v]\[w]$$ stores the node that is 1 hop away from $$v$$ in the path from $$v$$ to $$w$$. Then, to reconstruct the path, keep looking at those 1-hop away nodes till you reach $$w$$.

For example, in the above diagram, $$path\[v]\[w] = z$$. Then look at $$path\[z]\[w]$$ to determine the next node. And so on.

Actually, there is no reason we need to even store the “first” node. You can store any node (say, $$z$$) along the shortest path from $$v$$ to $$w$$ and then recursively find the shortest path from $$v$$ to $$z$$ and $$z$$ to $$w$$. In FW, you can store this intermediate node each time you modify/update the matrix entry for a pair.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FvAMCPkeulaZQfYfwavQA%2FScreenshot_2022-04-12_at_6.54.55_PM.png?alt=media&amp;token=8c94f84f-eef7-4cfd-b297-cb07d3696188" alt=""><figcaption></figcaption></figure>

### Variants of FW

1. Transitive closure - Return a matrix $$M$$ where $$M\[v]\[w] = 1$$ if there exists a path from $$v$$ to $$w$$; $$M\[v]\[w] = 0$$ otherwise
2. Minimum bottleneck edge - For $$(v,w)$$, the bottleneck edge is the heaviest edge on a path between $$v$$ and $$w$$. Return a matrix $$B$$ where $$B\[v]\[w]$$ = weight of the minimum bottleneck along $$v$$ to $$w$$.


# Longest Increasing Subsequence

## Problem

Given a sequence of integers (say, an array), output the length of an increasing subsequence (not necessarily contiguous) of maximum length.

For example, if the input sequence was $${8,3,6,4,5,7,7}$$, the answer would be $$4$$ since the LIS would be $${3,4,5,7}$$.

## Attempt 1 : Graph Modelling

Think of the elements in the sequence as nodes. Draw a directed edge between the nodes $$(u,v)$$ only if $$v > u$$ and $$v$$ occurs after $$u$$ in the sequence. This forms a DAG. Notice that in this case the topological ordering is the order in which the elements occur in the sequence. The problem is now essentially to find the longest path in the DAG. We can run our DAG SSSP from every node with the edges reversed.

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2Fqtw5m3KHh2YNNP0rLnYV%2FScreenshot_2022-04-11_at_8.40.10_PM.png?alt=media&amp;token=c90ba583-eb3f-4cc6-8010-97d5663cd4ab" alt=""><figcaption></figcaption></figure>

Our DAG SSSP takes $$O(V+E)$$ time to run once. In the worst case, $$E = O(V^2)$$ (think of an increasing sequence) and so, each SSSP takes $$O(n^2)$$ where $$n$$ is the length of our input sequence. We need to run this $$n$$ times, and so our algorithm takes $$O(n^3)$$.

Observe that we are recomputing a lot here! In particular, we relax each edge at most $$n$$ times. Can we do better?

In fact, we can do much better. Let us try to think in terms of DP and break our problem into smaller subproblems.

The trivial case is when the sequence is of length $$1$$. Then, we know that the LIS is of length 1.

For each outgoing edge (in reverse topological order of nodes), find the maximum LIS of the destination node and add 1. That gives you the LIS starting at that node.

Formally, define $$S\[i] = LIS(A\[i \dots n])$$ starting at $$A\[i]$$ where $$A\[1, \dots n]$$ is the input array. In terms of our table view, at each index $$i$$ of our table, we store the length of the longest increasing subsequence starting at index $$i$$ of the array. Our problem is to find the maximum entry in the table.

Our DP recurrence relation is:

1. Base Case: $$S\[n] = 1$$(length of LIS in an array of length 1 is 1)
2. Recurrence: $$S\[i] = (max\_{(i,j) \in E} S\[j]) + 1$$.

Some pseudocode is as follows:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FuaSRwYJPdYXUwjONRVe3%2FScreenshot_2022-04-11_at_8.52.49_PM.png?alt=media&amp;token=87fcd396-049b-4577-b678-9089e07ba07a" alt=""><figcaption></figcaption></figure>

The running time of the above algorithm is essentially $$O(V+E) = O(n^2)$$ (Be sure to be able to prove this)

## Attempt 2 : Dynamic Programming

Let’s stop thinking about this as a graph now.

Define $$S\[i] = LIS(A\[1\dots i])$$ **ending** at $$A\[i]$$

So, each index $$i$$ in the dp table stores the length of the LIS using the first $$i$$ elements.

Then,

1. $$S\[1] = 1$$ (length of LIS ending at first index)
2. $$S\[i] = (max\_{(j < i, \ A\[j] < A\[i])} S\[j]) + 1$$ (Look at everything to your left which is smaller than you. Find the maximum length of LIS ending at all those indices. Add 1 to get your maximum length (since you are essentially extending the sequence). If there is nothing to the left of you that is smaller than you, you cannot extend any of those LISs and so, you need to start a new LIS and your value will be 1.

Note that “ending at index $$i$$” necessarily means that $$i$$ is a part of the LIS. It does not include those LIS which come before it but do not contain this element itself (as then you wouldn’t know whether to extend this LIS or not since you don’t know the maximum element of the LIS) - To be able to extend an LIS, all you need to know is the current maximum element in the LIS. Here, index $$i$$ stores the maximum element of the LIS (since it ends at index $$i$$). This is also why to determine the LIS of the entire array, you need to look at every element in the end again. We cannot be sure that the LIS contains the last element and so, we cannot simply look at the last index.

Some pseudocode:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FgSiuJVklAB1MwFoTJDRA%2FScreenshot_2022-04-11_at_9.00.38_PM.png?alt=media&amp;token=07231380-02cf-497f-a1fc-b548f9a13bdf" alt=""><figcaption></figcaption></figure>

Again, this algorithm is $$O(n^2)$$, which should be fairly obvious by the 2 nested for-loops.

Another way of looking at it would be to realise that there are $$n$$ subproblems (where a subproblem is defined as the length of the LIS ending at a particular index). A subproblem at index $$i$$ takes $$O(i)$$ (since you need to look at all previously solved subproblems, and take the maximum). Then, $$\sum\_{i = 1}^n O(i) = O(n^2)$$.

The key invariant that we are maintaing is that at every iteration of the outer-loop, $$S\[i]$$ has the correct value of the maximum length of LIS ending at index $$i$$.

## Faster, Faster, Faster

It is possible to solve LIS in $$O(n\log n)$$ using binary search to solve subproblems faster. The key observation that allows us to use binary search is that as we extend the sequence, the length of the LIS can only increase or stay the same - hence, there is a monotonic behaviour of LIS.


# 0-1 Knapsack

## Problem

Given a backpack which can carry a weight of $$W$$ and $$n$$ snacks, each of weight $$w\_i$$ and happiness value $$h\_i$$, select the best possible combination of snacks to put in your backpack. Output the maximum happiness

## Solution

Classic DP problem. Try it yourself first (by thinking about the subproblems).

```java
import java.util.Scanner;

public class Knapsack {
    public static void main(String[] args) {
        Scanner s = new Scanner(System.in);
        System.out.println("Enter capacity of bag: ");
        int w = s.nextInt();
        System.out.println("Enter number of items: ");
        int n = s.nextInt();
        System.out.println("Enter weights of all items (space-separated): ");
        int[] weights = new int[n + 1]; // weight[i] == weight of item i (1-indexed)
        int[] happiness = new int[n + 1]; // happiness[i] = happiness of item i (1-indexed)
        int temp = n;
        weights[0] = 0; // dummy item weight to make it 1-indexed
        happiness[0] = 0; // dummy item happiness to make it 1-indexed
        while (temp-- > 0) {
            weights[n - temp] = s.nextInt();
        }
        temp = n;
        System.out.println("Enter happiness of items (space-separated): ");
        while (temp-- > 0) {
            happiness[n - temp] = s.nextInt();
        }
        s.close();
        int[][] dp = new int[w + 1][n + 1];
        // dp[i][j] stores the maximum possible happiness when you have a bag of
        // capacity i and you're allowed to take the first j items
        // then, dp[i][j] = max(dp[i-1][j], dp[i][j -1], happiness[i] +
        // dp[i-weight[i]][j-1])
        // dp[i - 1][j]: take the same stuff you took when you had capacity i - 1 and
        // allowed j items
        // dp[i][j - 1]: take the same stuff you took when you had a capacity of i and
        // allowed j items
        // if you can take the ith item, try taking it and see how much from the
        // remaining capacity, how much happiness you get

        // notice we added an extra 0th row to serve as the base case of the problem:
        // when the capacity is 0, all happiness = 0 and when 0 items are allowed, max
        // happiness = 0. This forms a "border" of the dp table filled with 0's
        // this makes it easy while filling the dp table since "remaining capacity" can
        // be 0 and this disallows ArrayOutOfBoundsException
        for (int j = 0; j <= n; j++) {
            dp[0][j] = 0;
        }
        for (int j = 0; j <= w; j++) {
            dp[j][0] = 0;
        }

        // now we fill the table in increasing order of capacity, adding one element at
        // a time for each row
        for (int i = 1; i <= w; i++) {
            for (int j = 1; j <= n; j++) {
                if (weights[j] <= i) { // if there is a chance we can include item j (even if we have to remove
                                       // everything else) then try including it (and then from the remaining capacity,
                                       // take the best of the j - 1 items)
                    dp[i][j] = Math.max(Math.max(dp[i][j - 1], dp[i - 1][j]), happiness[j] + dp[i - weights[j]][j - 1]);
                    // need to do 2 Math.max because annoying Java does not allow more than 2 integers
                    // wow

                } else {
                    dp[i][j] = Math.max(dp[i][j - 1], dp[i - 1][j]); // you can't include j anyway so this is the best
                                                                     // you can do
                }

            }
        }
        // our answer will be dp[w][n] (obviously)
        for (int i = 0; i <= w; i++) {
            for (int j = 0; j <= n; j++) {
                System.out.print(" " + dp[i][j] + " ");
            }
            System.out.println();
        }
        System.out.println("Maximum happiness: " + dp[w][n]);

    }
}
```

## Time Complexity Analysis

The time complexity of this 0-1 knapsack solution is $$O(nW)$$ , where `n` is the number of items and `w` is the capacity of the bag. This is because the algorithm uses dynamic programming to fill up a 2D table (`dp`) of size `(n + 1) x (w + 1)`, and each cell requires constant time to compute. The nested loops iterate over all items and capacities, leading to the $$O(nW)$$ complexity.

This illustrates a common technique to find the time complexity of any DP algorithm:

time taken per subproblem (excluding recursive calls, if any) $$\times$$ the number of subproblems

The space complexity is also $$O(nW)$$ due to the size of the `dp` table.


# Prize Collecting

We know that finding a longest path in general is an NP-hard problem. But, finding the longest path of length $$k$$ where length is defined as the number of hops (number of edges in the path) is not.

**Problem:** Given a directed weighted graph (with possible positive and negative cycles), find the maximum weight path containing **at most** $$k$$ edges.

This can also be framed as prize-collecting problem: If each edge weight represents a prize and you have $$k$$ levels of energy left, find the maximum amount of prizes you can collect by walking around the graph (you can repeat edges and gain the prize again). We shall now refer to this as the prize-collecting problem.

(As an aside, to detect positive weight cycles, you can negate the edges and run BF and see if it converges after $$V - 1$$ iterations. If it does not, the graph contains a positive weight cycle).

## Idea 1 : Graph Modelling

Transform the input graph into a DAG. How? Make $$k$$ copies of each node (duplicate the graph $$k$$ times) and draw edges to connect nodes between 2 adjacent graphs if there is an a edge between those nodes in the original graph. So, all edges point right and the path length is at most $$k$$ since an edge takes you from one graph to the next. An example is shown below:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FEvJN9gnWtr3NIU0Tio3b%2FScreenshot_2022-04-11_at_10.06.40_PM.png?alt=media&amp;token=ad2f771e-f220-4210-8e90-86022d8e540e" alt=""><figcaption></figcaption></figure>

Obviously there cannot be any cycles since an edge only points to a node in the next graph (hence, it forms a DAG).

Observe that our newly transformed graph contains $$kV$$ nodes and $$kE$$ edges.

Then the problem becomes equivalent to finding the longest path (in terms of sum of weights) in the DAG. We are certain that the maximum path length is $$k$$. So, we can run the DAG SSSP with negated edges for each source (to see where we should start from)

Because of the obvious symmetry of the graph (since each graph is a duplicate of the other), we only need to run SSSP from one set of nodes (i.e., all nodes of 1 graph). We don’t need to run it from all the nodes of all the graphs even though we are allowed to have lengths $$< k$$ because in the end, we will look at all nodes and take the maximum value.

This will take $$O(kVE)$$ time since we are running DAG\_SSSP (which takes $$O(kV + KE)$$ time on the new graph for each source) $$V$$ times. (Whenever you transform a graph, do not forget to recompute the number of nodes and edges in the new graph).

We can optimize this by creating a dummy node to act as the super source to run the DAG\_SSSP from. We connect this dummy node to all the nodes of the first graph from which we want to find the heaviest paths (maximum prizes) (this is a very very common technique to use when you are running an algorithm multiple times for different sources, just create a dummy node). Below, the blue node is the “super source” dummy node:

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2F4h0wldUAuwP1eBGHEFRz%2FScreenshot_2022-04-11_at_10.14.38_PM.png?alt=media&amp;token=88672208-b605-4583-8a44-620b6bd7562c" alt=""><figcaption></figcaption></figure>

If we use a dummy node, we are running DAG\_SSSP only once from the dummy node (to find the heaviest path in the graph from all the source vertices) which takes $$O(kV + kE + E)$$ because now you have added $$E$$ edges to connect the dummy node, and $$O(kV)$$ time to look at each node in the end to find the maximum prize we can collect. We need to look at all the $$kV$$ nodes and not just the last level of nodes because we are allowed to travel less than $$k$$ hops as per the problem. So, the total running time becomes $$O(kE)$$ (assuming the graph is connected and $$E > V$$)

## Idea 2: DP

If you know the optimal solution for $$k - 1$$, then it is easy to compute the optimal solution for $$k$$.

Define $$P\[v,k]$$ to be the maximum prize you can collect starting at $$v$$ and travelling **exactly** $$k$$ steps (notice how we modified our subproblem by ensuring exactly $$k$$ steps rather than at most, this makes it easier to reason about later - if you had kept it “at most”, you wouldn’t know how many steps you had actually taken and so, you wouldn’t be able to use that to solve larger subproblems and fill the memo table correctly)

Trivially, our base case is $$P\[v,0] = 0$$ for all nodes $$v$$. That is, if you cannot travel anymore, you cannot win anymore prizes.

The crucial recurrence relation is:

$$
P\[v,k] = \max{P\[w\_1, k-1] + w(v,w\_1),P\[w\_2, k-1] + w(v,w\_2), \dots, P\[w\_n, k-1] + w(v,w\_n)}
$$

where $$v.nbrList() = {w\_1,w\_2, \dots, w\_n}$$ and $$w(u,v)$$ is the cost of an edge from $$u$$ to $$v$$.

In other words, if you know the maximum prize you can win if you have $$k-1$$ steps left from all the neighbours, just calculate the maximum of all the neighbours, while adding the prize won by travelling to each neighbour.

### Pseudocode

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2FA7IugqTZTSXSo7tSDSFZ%2FScreenshot_2022-04-11_at_10.28.05_PM.png?alt=media&amp;token=675376c1-f929-49ec-ad89-57e081e8daca" alt=""><figcaption></figcaption></figure>

For every node, you know that the maximum you can earn in 0 steps is 0.

Then for each node, you check how much you can travel if you have 1 step: so look at all its neighbours and pick the maximum weight edge.

Then for each node (say, $$v$$), you check how much you can travel in 2 steps: look at all the neighbours, and find the maximum neighbour $$w\_i$$ where $$P\[w\_i,1] + w(v,w\_i)$$ is maximum among all neighbours of $$u$$. This means starting from $$u$$ if you have to travel **exactly** 2 steps, you should go from $$u$$ to $$w\_i$$ and then from $$w\_i$$ to some other node (depending on the neighbours of $$w\_i$$)

In other words, for each node, calculate how much you would travel in exactly $$k$$ steps if you went to all your neighbours (essentially, just brute force). But you have already computed how much you can travel from your neighbours in $$k-1$$ steps so you don’t need to recompute - this is exactly why we fill up the memo table from bottom to top, in increasing order of $$k$$ for all the nodes. This ensures that we have all the information we need to make the right decision. We look at all possible solution and pick the best one at every step - so, this is a greedy algorithm implemented using DP to avoid the unnecessary recomputation.

Notice that we find the maximum in the **entire** memo table and not just the last row because the number of edges in the longest path needs to be **at most** $$k$$ and not necessarily equal to $$k$$.

Realize that the main part of this problem was to spot the subproblems and identify the correct recurrence relation - once you do that, the problem is essentially solved.

### Time Complexity Analysis

There are $$kV$$ subproblems: each node has to store $$k$$ possible values regarding the prizes you can win starting from that node if you travel exactly $$k$$ steps. In the worst case, each node is connected to all other nodes and we need to look at all other nodes, for every node, $$k$$ times, giving us a $$O(kV^2)$$ complexity. But, on closer inspection, this is a pessimistic bound that is only true for very dense graphs. In general, the bound is pretty loose.

A more detailed analysis is as follows:

Each edge is looked at $$k$$ times, once each time to determine the value of the node using the neighbour’s value. In terms of a table view, think of a 2-D table. There are $$k$$ rows and $$V$$ columns. Then, each row is constructed based on the previous row (i.e., $$k^{th}$$ row requires $$(k-1)^{th}$$ row answers). Moreover, while filling any row, we look at exactly $$E$$ entries of the table (in total for the entire row) since we precisely look at each of the neighbours of a node, which adds up to $$E$$ when we consider all the nodes. So, it takes us about $$O(kE)$$ to fill the table. Then, to find the maximum value in the table, it takes us $$O(kV)$$ (size of the table) time. Overall, the time complexity becomes $$O(kE)$$.


# Vertex Cover on a Tree

## Problem

Given an undirected unweighted graph $$G = (V,E)$$ , a vertex cover is defined as a set of nodes $$C$$ where every edge is adjacent to at least one node in $$C$$.

A minimum vertex cover is a vertex cover with the minimum possible number of nodes.

In general, Minimum vertex cover is an NP-complete problem, i.e., there is no polynomial time algorithm unless $$P = NP$$.

However, there is an easy 2-approximation algorithm via matching (A 2-approximation means that your solution will be at most 2 times worse than the optimal solution).

We are solving an easier problem in this case: given an undirected unweighted **tree**, and a root of the tree $$r$$, we need to find the minimum vertex cover of the tree.

## DP Solution

As always, let us follow our DP recipe:

1. Define subproblems (and base cases)
2. Identify optimal substructure
3. Solve problem using sub-problems
4. Write (pseudo)code

An initial attempt might try to store the size of the vertex cover of the subtree rooted at the node and use it to solve larger subproblems. But that alone is not sufficient because we wouldn’t know whether we are forced to include its parent or not unless we know whether the child is in the vertex cover or not - so this leads to 2 cases: node in vertex cover and node not in vertex cover. This is sufficient information to compute the vertex cover of the parent too.

Note that it is not sufficient alone to store merely the size of the vertex cover of the subtree rooted at that node for each node. We need to know whether that node itself is included or not. In particular, if the child is not included in the vertex cover of its subtree, the parent must be included (only then the edge connecting them can be adjacent to a node in the vertex cover). Moreover, even if a child is included in its vertex cover for the subtree, it may be reasonable to include the parent in case the parent has other children who are not included in their respective sub-vertex covers.

Define $$S\[v,0] =$$ size of a vertex cover in subtree rooted at node $$v$$, if $$v$$ is NOT covered. Similarly, define $$S\[v,1] =$$ size of a vertex cover in subtree rooted at node $$v$$, if $$v$$ IS covered. For example,

<figure><img src="https://2303207012-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FyjtnddPQTRb4eLUp3QZe%2Fuploads%2F4nuz7vDOE6B5crF6Bnb7%2FScreenshot_2022-04-12_at_5.45.31_PM.png?alt=media&amp;token=e3308114-0d21-431e-9474-74bf6a5e35fb" alt=""><figcaption></figcaption></figure>

So, for each node you need to consider whether it is in the cover or not. Hence, there are $$2V$$ subproblems that we need to solve. (Note that the number of subproblems is NOT $$2^V$$- We are not considering it like “for each node, we can either include or not include. So, check all possible ways and pick the minimum that satisfies vertex cover property”. We are just looking at two possibilities for each node (INDEPENDENT of other nodes in the tree! we are not chaining the results so there’s no need to multiply the subproblems of all nodes together)

The base case is in case of leaves: $$S\[leaf, 0] = 0$$ and $$S\[leaf, 1] = 1$$.

After a bit of observation, you should realise that the recurrence relation is as follows:

1. $$S\[v,0] = S\[w\_1,1] + S\[w\_2,1] + S\[w\_3,1] + \dots + S\[w\_n, 1]$$ where $$v.children() = {w\_1, w\_2, \dots, w\_n}$$. In other words, if you don’t cover the node, you better make sure to cover all the children so that each edge between $$v$$ and its children is covered.
2. $$S\[v,1] = 1 + min(S\[w\_1,0],S\[w\_1,1]) + min(S\[w\_2,0],S\[w\_2,1]) + \dots + min(S\[w\_n,0], S\[w\_n,1])$$. That is, if you are covering the parent, then it is not mandatory to cover its children but often it is optimal to cover some of the children too (depending on the lower subtrees). So, you take the minimum of the two to decide whether to cover each child or not.

Then our final answer is $$min(S\[root,0],S\[root,1])$$ - whether to cover the root or not.

Look how elegantly we realised that using subtrees as subproblems is the right way to go - the importance of identifying this overlapping subproblem cannot be overstated.

## Pseudocode

```java
int treeVertexCover(V){ // Assume tree is ordered from root-to-leaf
	int[][] S = new int[V.length][2]; // create memo table S
	for (int v=V.length-1; v>=0; v--){ // From the leaf to the root
		if (v.childList().size()==0) { // If v is a leaf...
	    S[v][0] = 0;
      S[v][1] = 1;
		}
		else{ // Calculate S from v’s children.
			int S[v][0] = 0; // not including node v
			int S[v][1] = 1; // including node v
			for (int w : V[v].childList()) {
				S[v][0] += S[w][1]; // you're forced to take the vertex cover that includes the child since you are not including v
				S[v][1] += Math.min(S[w][0], S[w][1]); // no constraint that you cannot include both adjacent nodes.
			}
		}
	}

	return Math.min(S[0][0], S[0][1]); // returns min at root
}
```

## Running Time analysis

You’re looking at each edge exactly once and each node exactly twice (once when determining its own $$S$$ values, and once when trying to determine it’s parents $$S$$ value - except the root). So, the running time is $$O(V+E)$$. But observe that our input is a tree and hence, $$E = V - 1$$. Thus, running time is $$O(V)$$.

Alternatively, you can think like this.

There are $$2V$$ subproblems:

1. Each edge is explored once since each subproblem involves exploring children edges.
2. Hence, $$\sum\_{v \in V} degree(v) = O(E)$$